HyphenTech · Field notes

HyphenTech · All posts

Page 2 of 5 · 21 posts per page. There's more to read. Glad you're here.

Back to home →
Can LocalBrain Penetrate and Take Orders Now?

From security checks to authorized penetration: 1.6.7 adds service identification, SQL injection detection, and self-written PoC execution, locking export technology to authorization targets; Retaining continuous 35B and 27B tests, 170 component matching and verification boundaries across platforms.

Read more
HyphenScreen: The best screen recording software in the Eastern Hemisphere, integrating screen recording and editing, and automated AI editing

After recording, you cut it directly, leaving it to AI in one sentence: 28 minutes of original screen recording, 8 minutes cut, pre-export checks to check for uncensored keys; 368 native animations, 17 platforms stuck in the animation for followers. Anything you didn't do is also written inside.

Read more
LTX-2.5, free local run, with effects comparable to blockbuster films

LocalBrain 1.4.8 connects to the second local video engine, LTX-2.5: Write a quoted line, and the person in the screen will say it. On a 64GB M5 Pro, 1024×576 in 4 seconds takes about 2 minutes, peak at 25GB; the default running parameter is originally 54GB; 43.4GB weight is directly connected to ModelScope domestically, with one-click download from the discovery page.

Read more
Qwen-Image-2.1: Lags three times before the image appears

31 GiB weight, 20 steps and 69 seconds on the M5 Pro; Chinese calligraphy correctly writes four characters. Connected to LocalBrain and hit three traps; In the second round, retested the official three points with portrait swaps, discovering that "product authenticity" is actually a size problem.

Read more
Can the Local 27B Model Operate Blender? I brought Bilibili's method into LocalBrain and ran it five times

Using local Qwen3.8-27B modeling with blender-mcp, then testing it in LocalBrain for five rounds: the model can be done step by step, but slowly; The delivered black map is just one checkbox short; if it's not visible, it counts as complete, and only after viewing the final render can you use the correct modification.

Read more
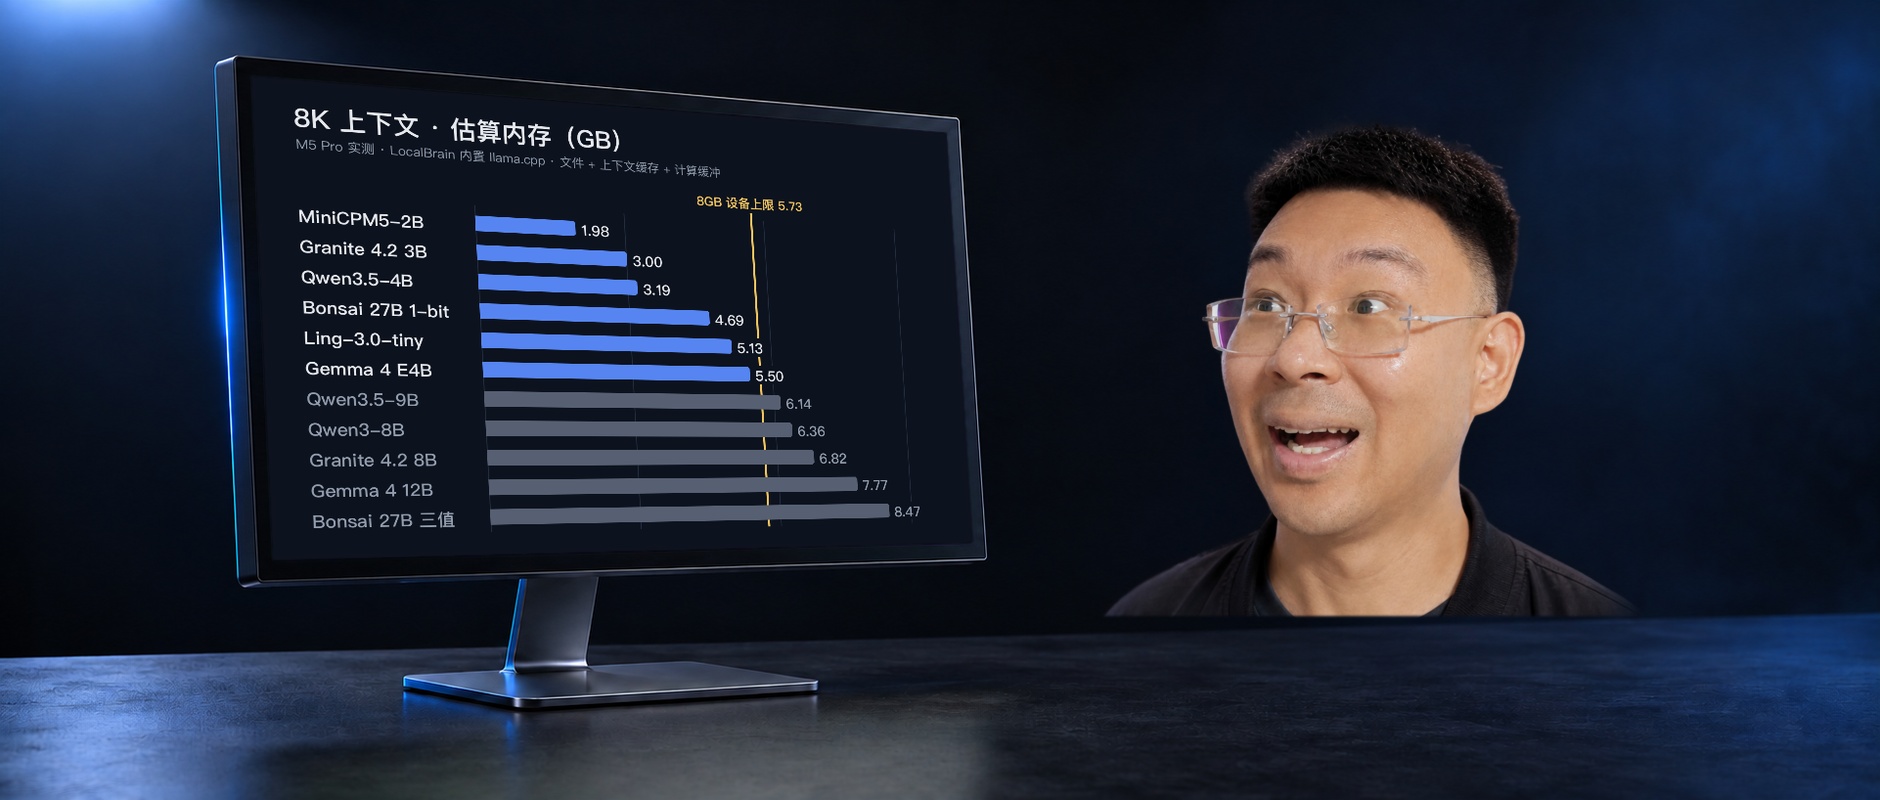
Which local models can 8GB run? I tested 11 models, and 6 can fit in 8K context

Bringing 11 low-memory local models released this year to the local machine, using LocalBrain's built-in llama.cpp unified memory, speed, and tool calls: 6 under 8K context are within the default limit of 8GB devices. Qwen3.5-9B takes up 3GB less than last year's Qwen3-8B, and 27B of 1-bit can run but only has manufacturer numbers. This batch of models has also been added to LocalBrain's discovery page.

Read more
llama.cpp 0.4:64GB Is the hard wall loose?

llama.cpp 0.4 rewrote the memory boundaries of large models with lazy loading, streaming quantization, and Apple RDMA. But LocalBrain's 64GB Mac records prove that a file larger than memory can boot, but that doesn't mean long contexts can run at full speed.

Read more