
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
Summary 12 real requests: answers, rate limiting, old models, and half JSON HyphenTech · Data and measurements from November 2, 2026
OpenRouter first round of two free models both returned 429. I kept trying other free local configurations before finally getting the full order answer. Among the 12 requests, there were correct results, as well as names translated, output was truncated, and the old model 404. You can’t stop at the first two errors, nor just pick the later successes.
OpenRouter puts multiple model vendors in the same interface, like a mall with many stalls. Getting a mall pass doesn’t mean every stall is stocked, equally free, or just as crowded. When connecting, check the exact model and the actual routing for this time.
For the same order, leave the original result for each item
This time, I used the correct total price of 3400 yuan for equipment orders, requiring fixed JSON fields. This time, I used an existing account, and the local HyphenBox forwarded the request to the corresponding platform. The timing was from the request sent locally to the completion of the response, including network and service waiting; Each model’s order question was only run once. The account was configured to free mode and did not read the final bill.
| Request model/task | Completing it takes time | Actually return |
|---|---|---|
| google/gemma-4-26b-a4b-it:free <br>order | 3.175 seconds | 429; call failed |
| cohere/north-mini-code: <br>free order | 2.916 seconds | 200; the total price is correct, and the equipment name is translated into English |
| dots-studio/dots-3-note-preview: <br>free order | 3.517 seconds | 200; JSON field and amount match the standard answer |
| inclusionai/ling-3.0-flash-fin:free <br>order | 1.135 seconds | 404; Call failed |
| inclusionai/ling-3.0-flash-sante: <br>free order | 0.491 seconds | 404; Call failed |
| nvidia/nemotron-3-super-120b-a12b: <br>free order | 0.296 seconds | 404; Call failed |
| nvidia/Nemotron-3-Ultra-550B-A55B: <br>Free order | 7.821 seconds | 200; JSON field and amount match the standard answer |
| Nvidia/Nemotron-3.5-Lightning: <br>Free order | 29.515 seconds | 200; Returns incomplete content, JSON cannot parse it |
| OpenRouter/Free <br>order | 3.061 seconds | 200; JSON field and amount match the standard answer |
| poolside/laguna-s-2.1: <br>Free order | 0.293 seconds | 404; Call failed |
| poolside/laguna-xs-2.1: Free <br>order | 0.255 seconds | 404; Call failed |
| Liquid/lfm-2.5-2.6b: Free <br>orders | 1.195 seconds | 429; call failed |
This machine forwards via HyphenBox; One request per line, not multi-turn averaging. Time consumption includes network and upstream waiting.
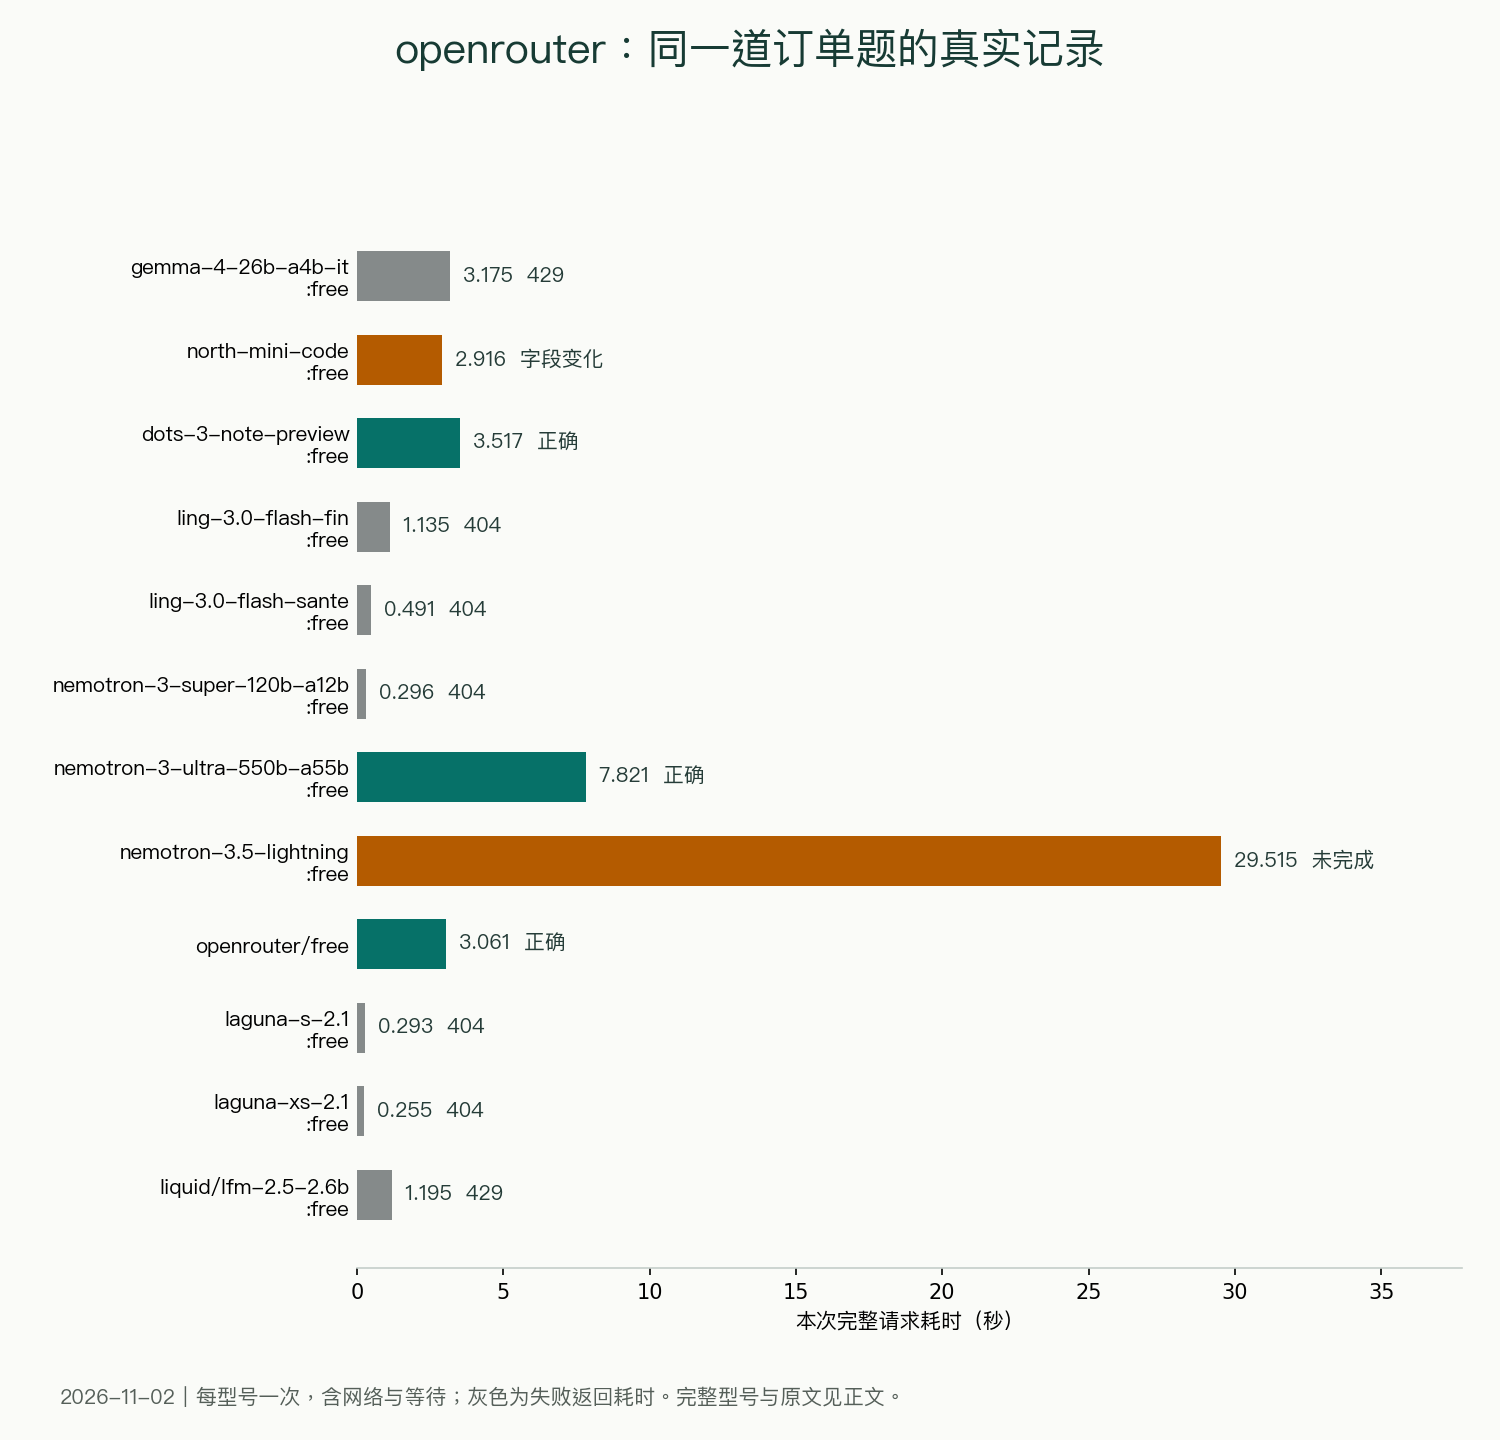
dots-studio/dots-3-note-preview: free gives a complete correct result after 3.517 seconds; nvidia/nemotron-3-ultra-550b-a55b: free gives a full correct result after 7.821 seconds. Below is one of the original answers.
{"items":[{"name":"设备A","quantity":2,"unit_price":1200,"subtotal":2400},{"name":"设备B","quantity":3,"unit_price":350,"subtotal":1050}],"shipping":80,"discount":130,"total":3400}
Specify the free model for original return
Free automatic routing depends on which one actually lands
Once a request was selected as openrouter/free, and the return model field was nvidia/nemotron-3-nano-omni-30b-a3b-reasoning:free, completed in 3.061 seconds. This was an automatic routing result, not an independent test I performed directly on this NVIDIA model. Save the request name and return name to reproduce exactly what you used.
cohere/north-mini-code: The amount for free is correct, but write “Device A/Device B” as “Device A/Device B”. It’s not a big problem for a quick reading; If subsequent programs must match the product by the original name, then the field must be followed. This is recorded separately from the total price calculation error.
200 may only get half an answer
nvidia/nemotron-3.5-lightning:free took 29.515 seconds this time, HTTP is 200, but JSON is not closed, finish_reason is length. The max_tokens of this round of requests is 1024; After the output budget is exhausted, the task is not yet finished. Inference models may also consume internal inference budget, so the returned usage information needs to be checked together.
HTTP 200
finish_reason: length
本次请求 max_tokens: 1024
实际验收:JSON不完整,无法解析
This time, I didn’t retest after raising the budget, so I kept “This configuration is not complete” and casually rated it as the capability limit for this model. On the program side, you can check HTTP status, reason for termination, whether JSON can parse, and key fields simultaneously, rather than treating 200 as “completed.”
How do you find the free model, and how do you fill in the key and address?
Apply for your own key from the OpenRouter key page ⟧, base address https://openrouter.ai/api/v1. Find the current free model in the model directory and, verify the input and output prices, then copy the full name. Keep the ‘free’ at the end of the name; do not mistake the paid model with the same name as the free version.
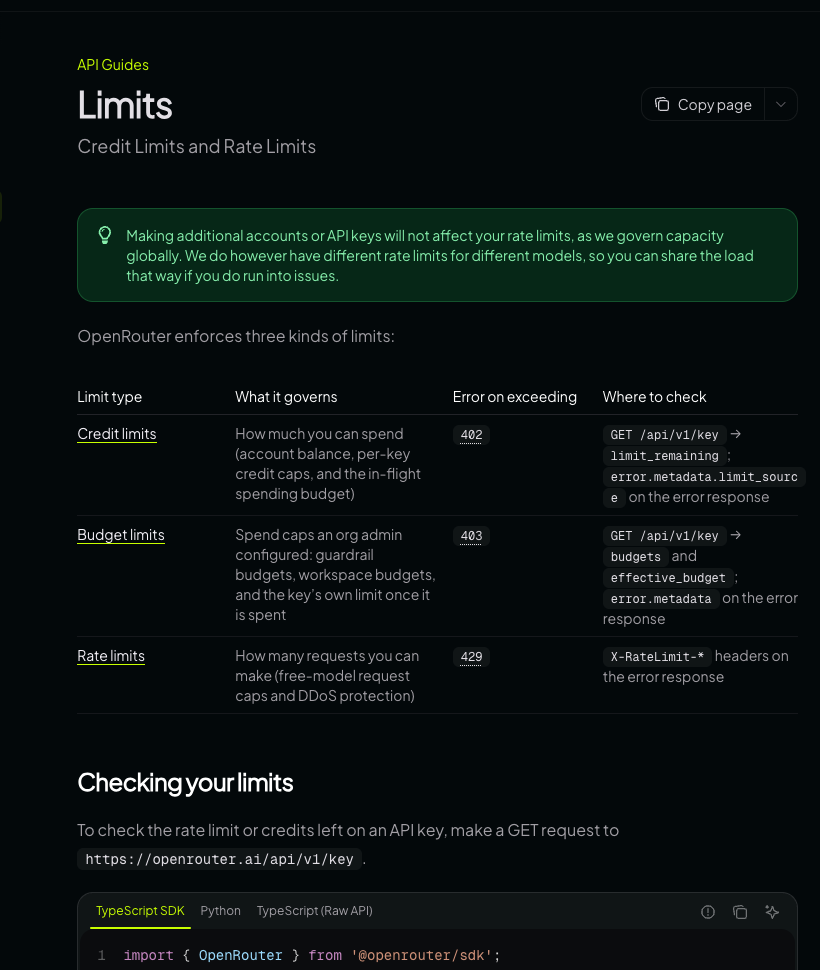
The daily request quota depends on the current account. This round does not read your account equity and does not provide the same number for everyone. 429 waits for rate limit restoration; 404 first checks whether the model is still in the current directory; Negative balances may also prevent free calls. View benefits after recharge and accounts without recharge separately.
Quote: My judgment Want to try multiple free text models with one entry, OpenRouter is convenient. This round has a successful answer, but rate limiting, availability, and output format differ significantly between different ports. For fixed tasks, specify the model first; When using automatic routing, record the actual returned model.
Main sources of verification
Self-made software
Versions, changes and supported installers all come from the same public release records.
HyphenAssistant
Continue your computer’s DeepSeek Harness session from a phone browser. The service, computer and network must stay online; model costs follow your existing setup.
View public downloads and updates ↗LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗ScreenLex
Turn subtitles from your own films and shows into an English vocabulary library, entirely offline.
View public downloads and updates ↗HyphenScreen
Screen recording and editing with a Resolve-style timeline, automatic redaction and pre-export checks.
View public downloads and updates ↗Support HyphenTech
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Save the QR codeScan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

WeChat tips · Any amount welcome



Comments
Loading comments…