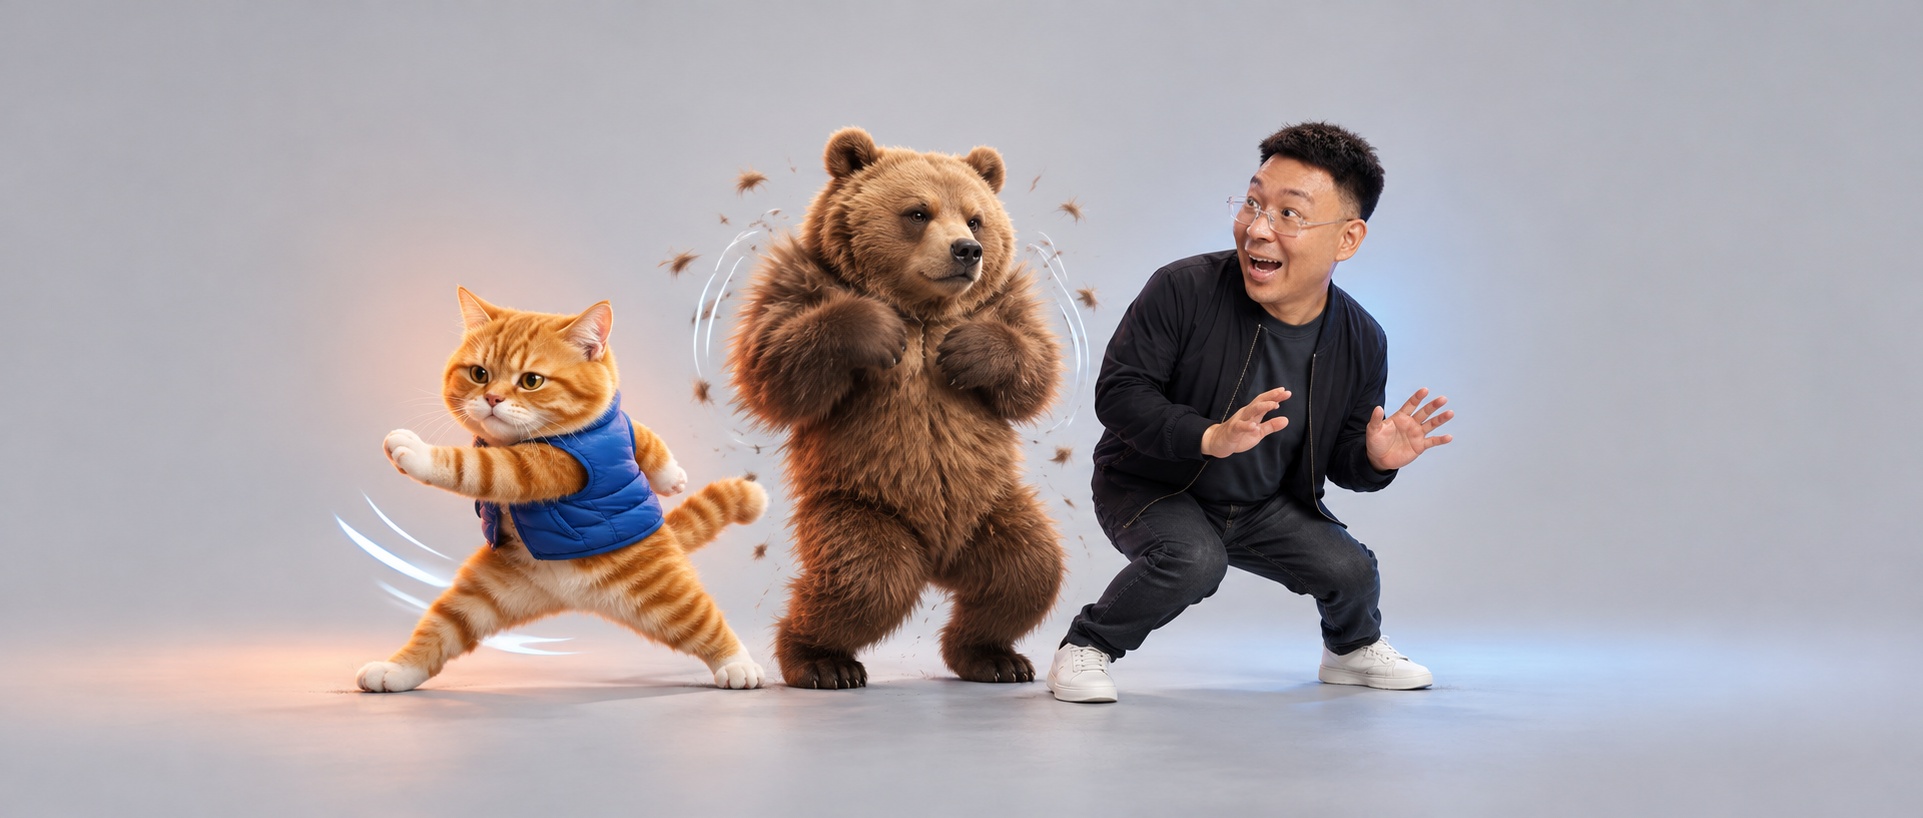
Qwen-Image-2.1-Turbo本地出图快三倍:美女萌宠、闪身步与狗熊哆嗦毛实测
M5 Pro 64GB实测普通Turbo Q4:两项对照约快三倍,追加六张美女萌宠与舞蹈热梗图,保留完整原图、动作偏差和运行截图。
Read morePage 1 of 4 · 21 posts per page. There's more to read. Glad you're here.
Back to home →M5 Pro 64GB实测普通Turbo Q4:两项对照约快三倍,追加六张美女萌宠与舞蹈热梗图,保留完整原图、动作偏差和运行截图。
Read more
Qwen-Image-2.1-Turbo provides weighting and official usage, but hardware, licensing, and service boundaries still require itemized acceptance.
Read more
It breaks down books, long videos, and podcasts into callable skills, but free code doesn't mean the entire process is cost-free.
Read more
Huashu Design clearly explains what it can deliver, free boundaries, and usage thresholds all at once.
Read more
It breaks down emotions, facts, and actions, but open-source code does not mean the entire process is free or tested.
Read more
career-ops entrusts job screening, resume rewriting, and application tracking to AI, but the final submission is still decided by the applicant.
Read more
The era of on-device AI has arrived. Local AI is not a cheap cloud solution; it is a new deployment model where "data goes out without leaving the door." I used 11 LocalBrain models—from 1.5GB LFM2.5 to 80GB Qwen3.8-Flash-Next—breaking down definitions, mental models, hardware boundaries, quantization, families, multimodals, workflows, hybrid architectures, business significance, entry paths, common pitfalls, and all aspects.
Read more
Control cameras, actions, and art style with code; characters must have authorization; Operational effects still need to be tested.
Read more
From script to finished film, Uncle Lan's skills connect voice acting, visuals, and acceptance evaluation; The operational effect still needs to be tested.
Read more
Mistral Large 4 preview is now live, with weighting planned for the end of the month; The local threshold has not yet been announced.
Read more
Besides the 12GB graphics card, how much more memory do you need? Breaking down Strata's official speed, quantitative trade-offs, and Mac access boundaries.
Read more
30 sessions are not 30 lessons. From a talking program, two AI winters, to models that can truly work on your computer: following a storyline, connecting knowledge, real products, and choices.
Read more
The parts have been disassembled, now put back together. Follow "Today's Weather True" into a translation agency that only recognizes numbers, see how a sentence becomes probability, and then into text on your screen.
Read more
From security checks to authorized penetration: 1.6.7 adds service identification, SQL injection detection, and self-written PoC execution, locking export technology to authorization targets; Retaining continuous 35B and 27B tests, 170 component matching and verification boundaries across platforms.
Read more
After recording, you cut it directly, leaving it to AI in one sentence: 28 minutes of original screen recording, 8 minutes cut, pre-export checks to check for uncensored keys; 368 native animations, 17 platforms stuck in the animation for followers. Anything you didn't do is also written inside.
Read more
LocalBrain 1.4.8 connects to the second local video engine, LTX-2.5: Write a quoted line, and the person in the screen will say it. On a 64GB M5 Pro, 1024×576 in 4 seconds takes about 2 minutes, peak at 25GB; the default running parameter is originally 54GB; 43.4GB weight is directly connected to ModelScope domestically, with one-click download from the discovery page.
Read more
For AI computers, Mac should buy shared memory and low maintenance, Windows should be compatible with graphics card options, Linux should be the production stack; After adding the official spot price on September 28, the answer becomes more specific.
Read more
17 old entry points were reviewed one by one, and 4 candidates were reviewed; 3 callable platforms were screened based on current non-empty real requests, with quotas and failure boundaries recorded.
Read more
All 12 sets are delivered, but repeating the same problem is 15 times worse: long tasks get stuck in the loop outside, not in the model.
Read more
31 GiB weight, 20 steps and 69 seconds on the M5 Pro; Chinese calligraphy correctly writes four characters. Connected to LocalBrain and hit three traps; In the second round, retested the official three points with portrait swaps, discovering that "product authenticity" is actually a size problem.
Read more