
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
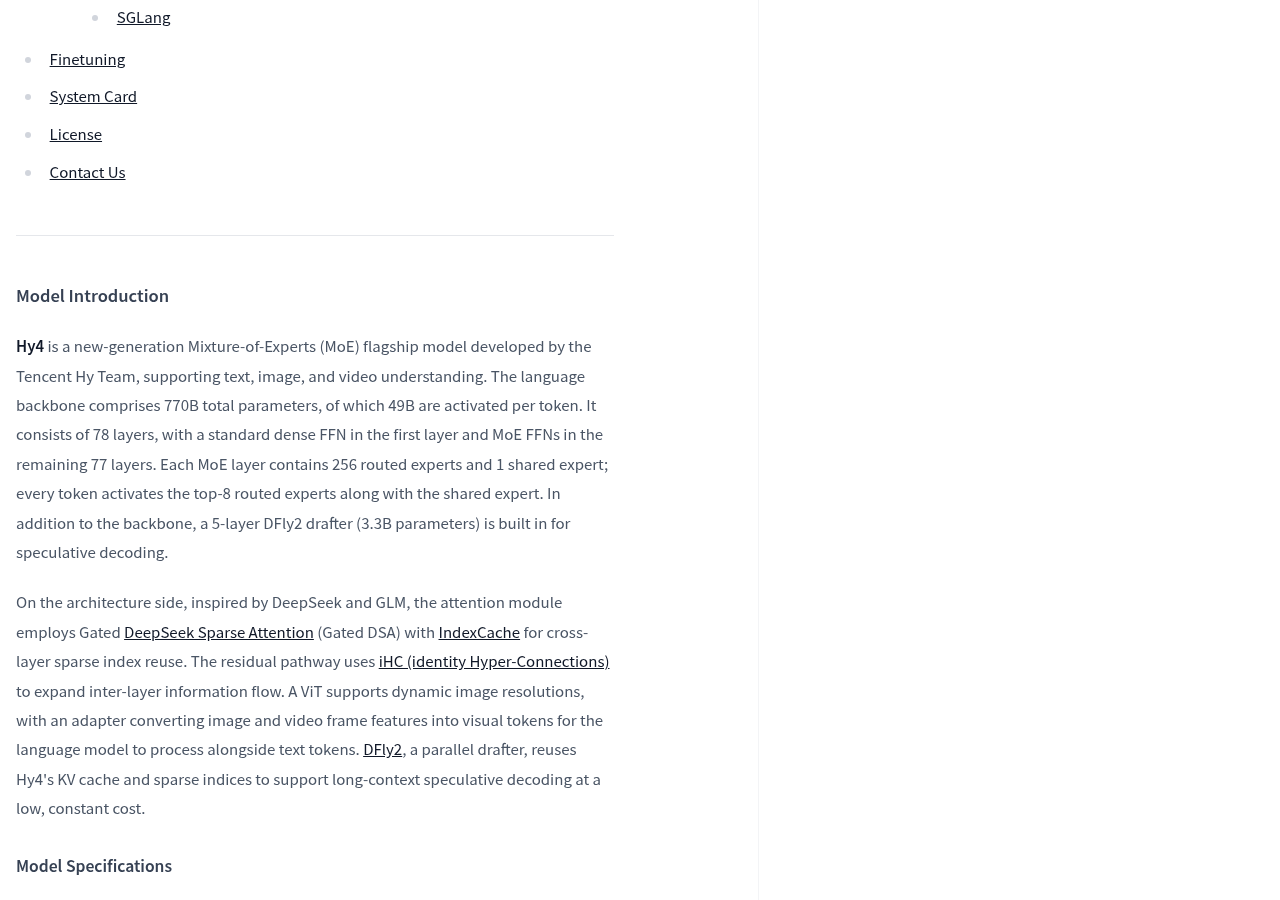
Tencent’s official model repository has a new name: tencent/Hy4. The official page states it supports text, image, and video understanding, with a total language backbone parameter of 770B and 49B of actual activation per token; The context length is 1M (1,048,576 tokens). Also released are the quantitative version of Hy4-FP8 and the pre-trained Hy4 base weight, distributed through Hugging Face, ModelScope, and GitCode.
Opening up weight does not mean everyone can run locally
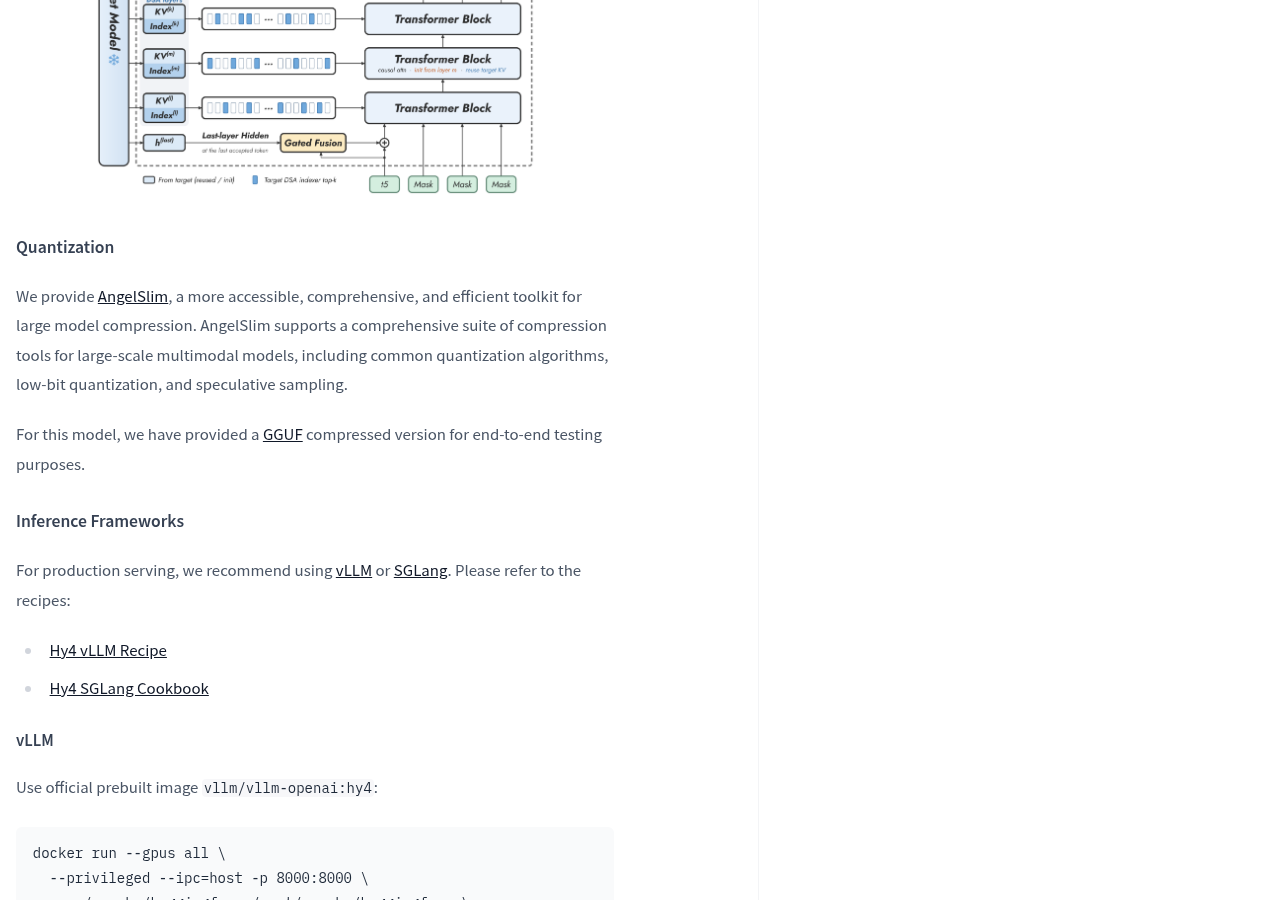
The official deployment method is either vLLM or SGLang service: the vLLM example image is written to --tensor-parallel-size 8, the SGLang example is --tp 8, both running 8 cards in parallel with the 774B parameter safetensors weights (BF16 / F32 tensor types). This means the official recommended usage is to place it on a multi-card machine as an OpenAI-compatible interface service, and the official call example base_url is http://127.0.0.1:8000/v1.
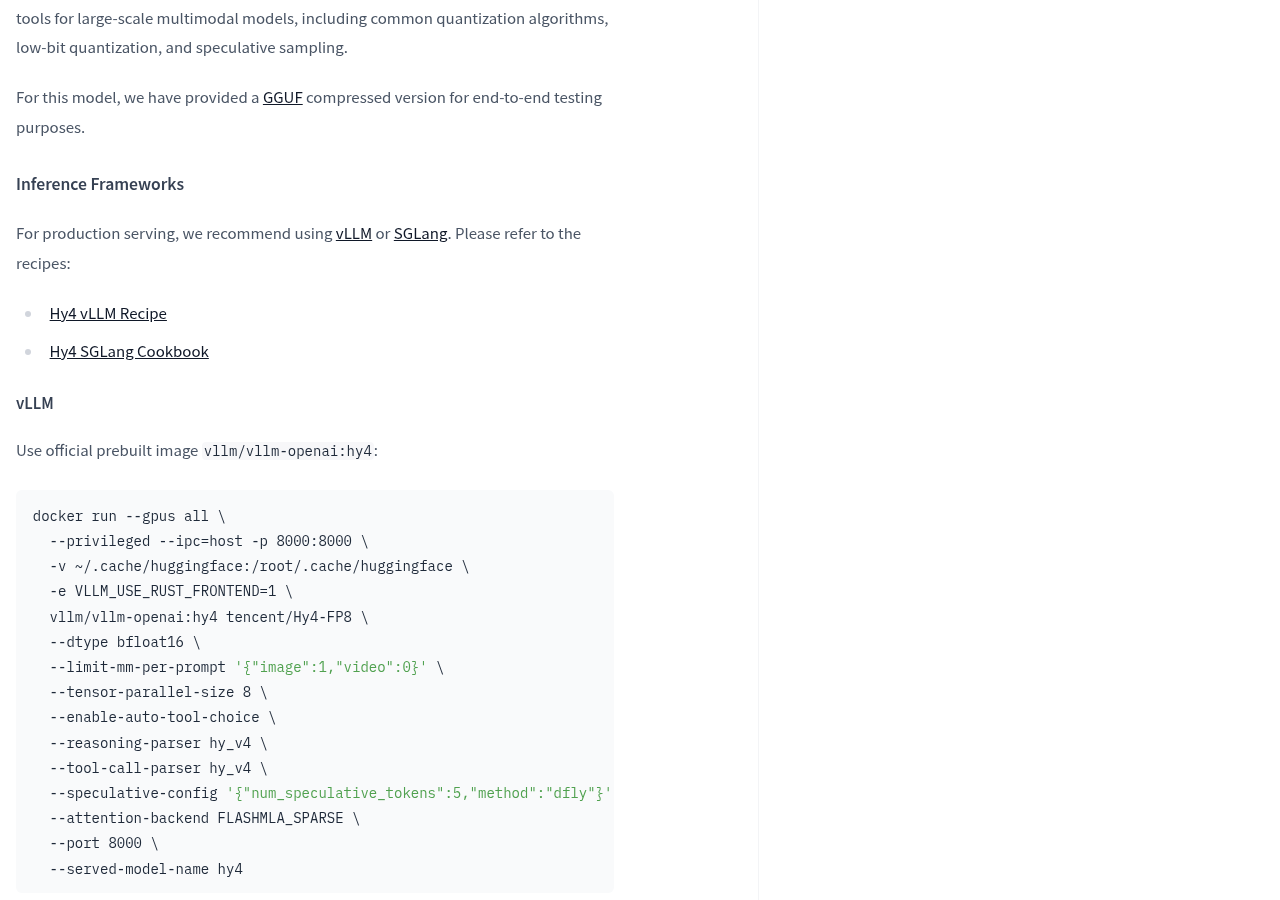
So what does “only 49B per token activated” mean? You can think of it as express warehousing: the warehouse has a total volume of 770 items, but each delivery only selects 8 zones from 256 zones plus 1 shared zone for shipment, resulting in an actual cargo volume of about 49B. The advantage is fewer people to move; the downside is the goods are still there—the warehouse itself takes up space. The video memory or memory needed to store these goods won’t disappear just because you move part of the goods each time. So readers who want to run on their own computers should first look at the warehouse size, not the volume per shipment.
Tip The official quantization section states: for end-to-end testing purposes, a compressed version of GGUF is provided, and it is recommended to use the AngelSlim toolchain for compression; The repository also lists AngelSlim/Hy4-GGUF. Weight opening, license, runtime, and hardware requirements are four separate matters—Hy4 uses the Tencent Hy License, with files stored in the repository LICENSE; Whether it runs locally depends on the VRAM, quantization format, and inference framework versions you have. These need to be verified separately and cannot be directly derived from the phrase “open weights.”
The two most noteworthy categories in the official results
According to the official numbers, in the Hy4 base knowledge category few-shot pre-training evaluation, SimpleQA scores are 57.2, Chinese-SimpleQA 83.9, SuperGPQA 62.7; math U-MATH 71.6, OCW Courses 66.7. For multimodal data, only Hy4 Base and Hy4 flash Base lines are reported: MMMU-Pro (10 options) 59.6, RealWorldQA 72.3, and CountBenchQA 90.6. The official table clearly indicates the highest value available for that row and does not indicate statistical significance.
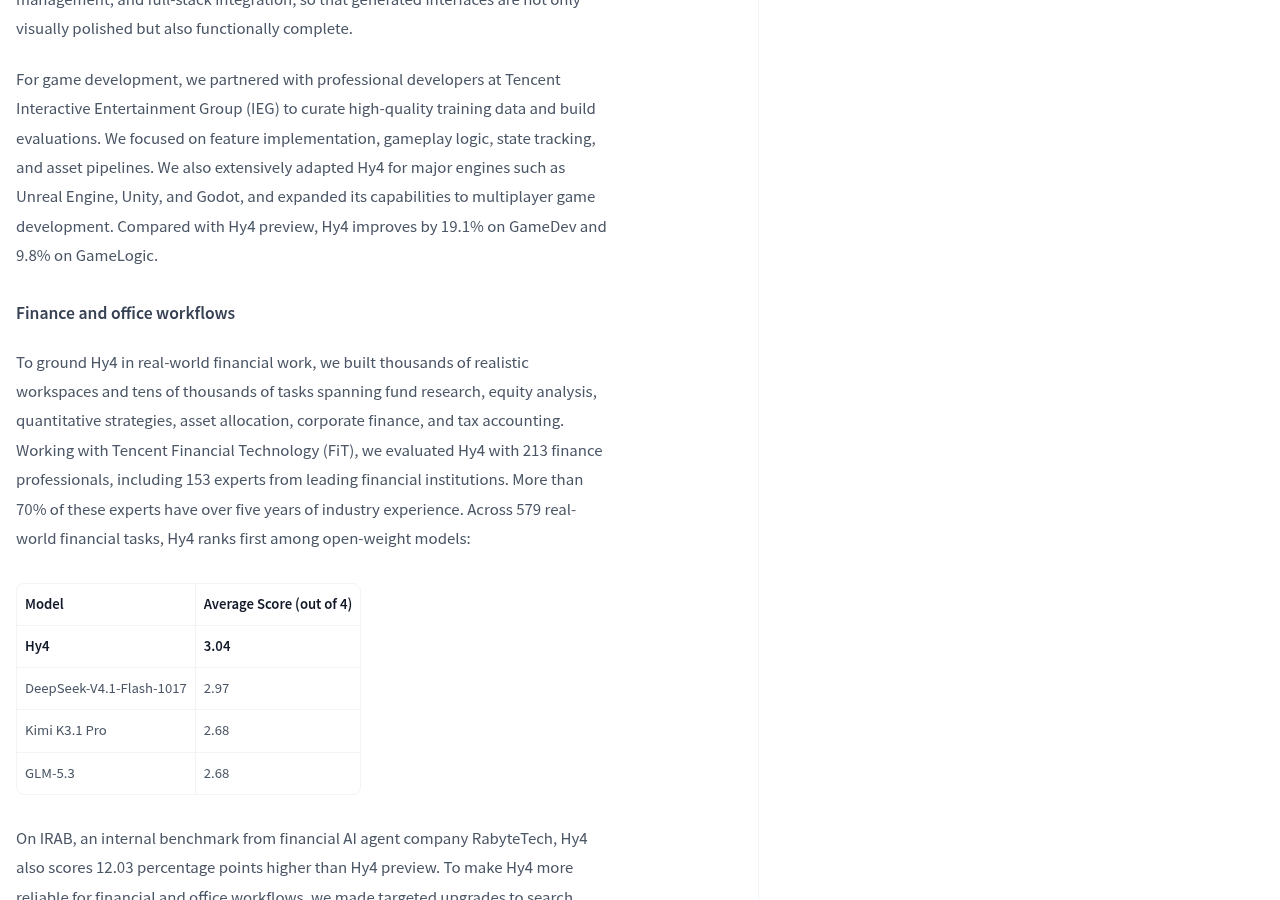
The official positioning is based on evaluation data, not independent verification: among 579 real financial tasks, 213 financial professionals participated, including 153 from leading financial institutions, with over 70% having more than five years of experience; Hy4 averaged 3.04 out of 4, with control models listed as DeepSeek-V4.1-Flash-1017 at 2.97, Kimi K3.1 Pro at 2.68, and GLM-5.3 at 2.68. The official statement places it first among open-weighted models. The same section also states that Hy4’s hallucination rate dropped from 15.76% in Hy4 preview to 5.45%, and inference errors dropped from 23.1% to 5.6%.
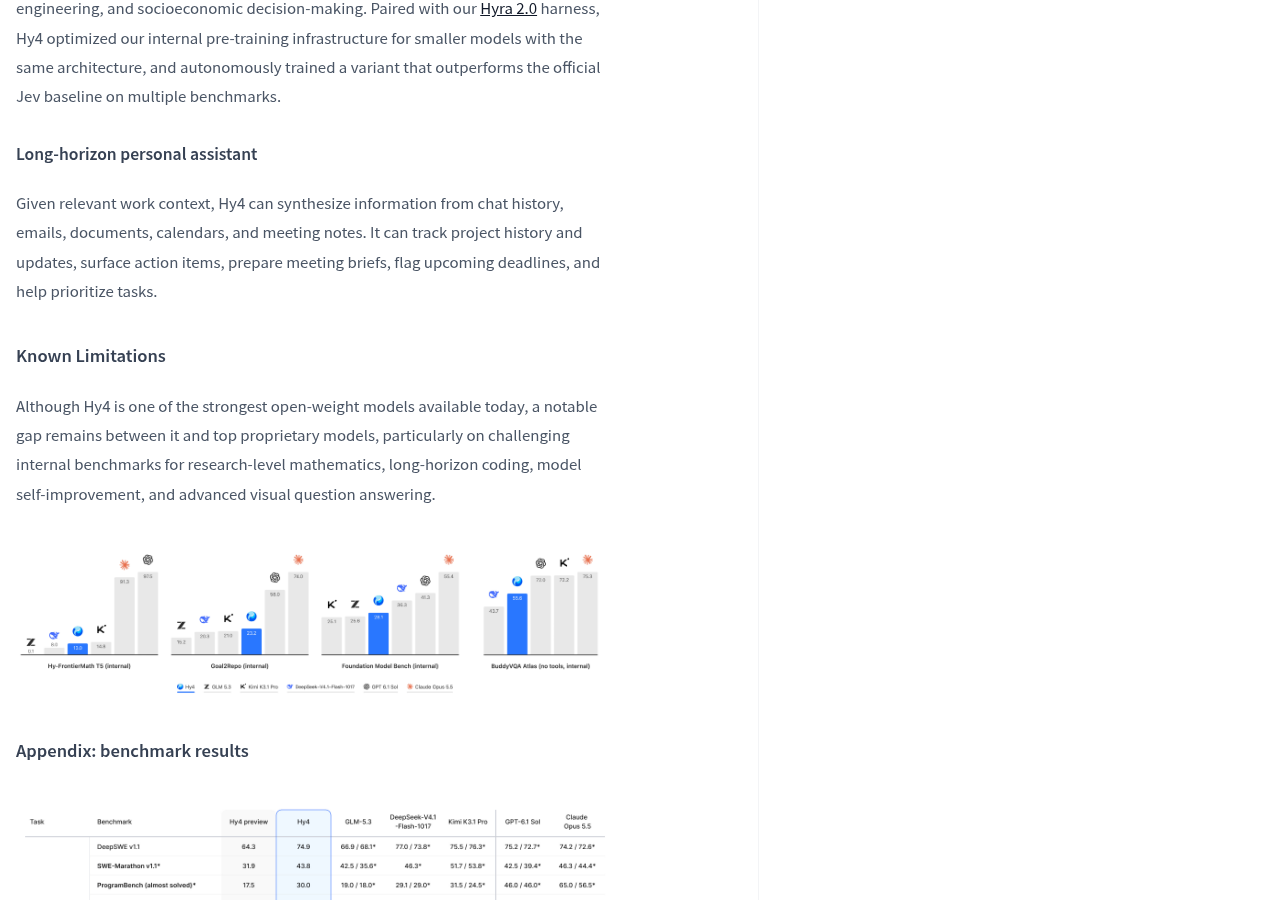
Warning The official Known Limitations section states very bluntly: although Hy4 is currently one of the strongest open-weighted models, it still lags significantly behind top-tier proprietary models in internal benchmarks such as research-grade mathematics, long-cycle coding, model self-improvement, and advanced visual Q&A. The model card also includes a disclaimer: The base model encountered a large amount of synthetic instruction data during mid-training and occasionally outputs answers not in the expected format, which may affect few-shot evaluation scores. These are all official statements and cannot be considered third-party reproduction conclusions.
How to judge whether it’s worth it
- If you only have consumer-grade graphics cards, first check whether the quantization routes of GGUF and AngelSlim can fit your machine’s memory range, rather than looking at total specs.
- If you need graph or video understanding or computer use workflows, Hy4’s multimodal training is the main incremental aspect of this preview and is worth testing.
- If your scenario is finance or office document collaboration, the official 579 task evaluation and hallucination rate data are the most relevant references to your needs, but the conclusion comes from the official internal evaluation.
- If your goal is research-grade mathematics or ultra-long cycle coding tasks, and the official team admits there is a gap with proprietary models, don’t treat it as the only solution.
The next step upon implementation is very specific: the weight address is View page: huggingface.co · Hy4, and in the same batch there are also View page: huggingface.co · Hy4-FP8 and View page: huggingface.co · Hy4-base ; The official reasoning recipe points to vLLM recipe and SGLang cookbook, and the system is stuck at hy.tencent.ai. The recommended verification order is: first confirm whether the version of the inference framework you have already supports the model, then check if the volume of the quant weights falls within the range your hardware can handle. Finally, run a familiar real task with the official recommended parameters temperature=0.9, top_p=1.0, reasoning_effort by default. Test three to five of your own problems instead of looking at public rankings.
Official information
Self-made software
Versions, changes and supported installers all come from the same public release records.
HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗Support HyphenTech
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Save the QR codeScan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

WeChat tips · Any amount welcome



Comments
Loading comments…