
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
If you want to run a local large model, it’s easiest to first look at the graphics card name and price: Is your budget enough for a new card? Is it possible to buy a large-memory Mac in one go? I prefer to reverse the order: which model file do you plan to run, how long the dialogue you want to keep, what kind of wait you can accept, and then decide which device to buy.
Qwen4 is listed here to prepare equipment for future models; This issue does not include local Qwen4 testing or compatibility verification; the actual basis is the four models shown in the video: Qwen3.8 27B, Qwen3.8 Flash-Next, Qwen3.5 9B, and 4B. Equipment and quotes are from this issue’s data. Prices are snapshots of selected JD.com SKUs as of October 30, 2026, including bare cards, complete devices, second-hand, and conditional discounts, and cannot be directly considered the current purchase price. Public performance records will specify the corresponding software and configurations. Devices not tested will not be tested individually.
First, ask if it fits well, then if it works quickly
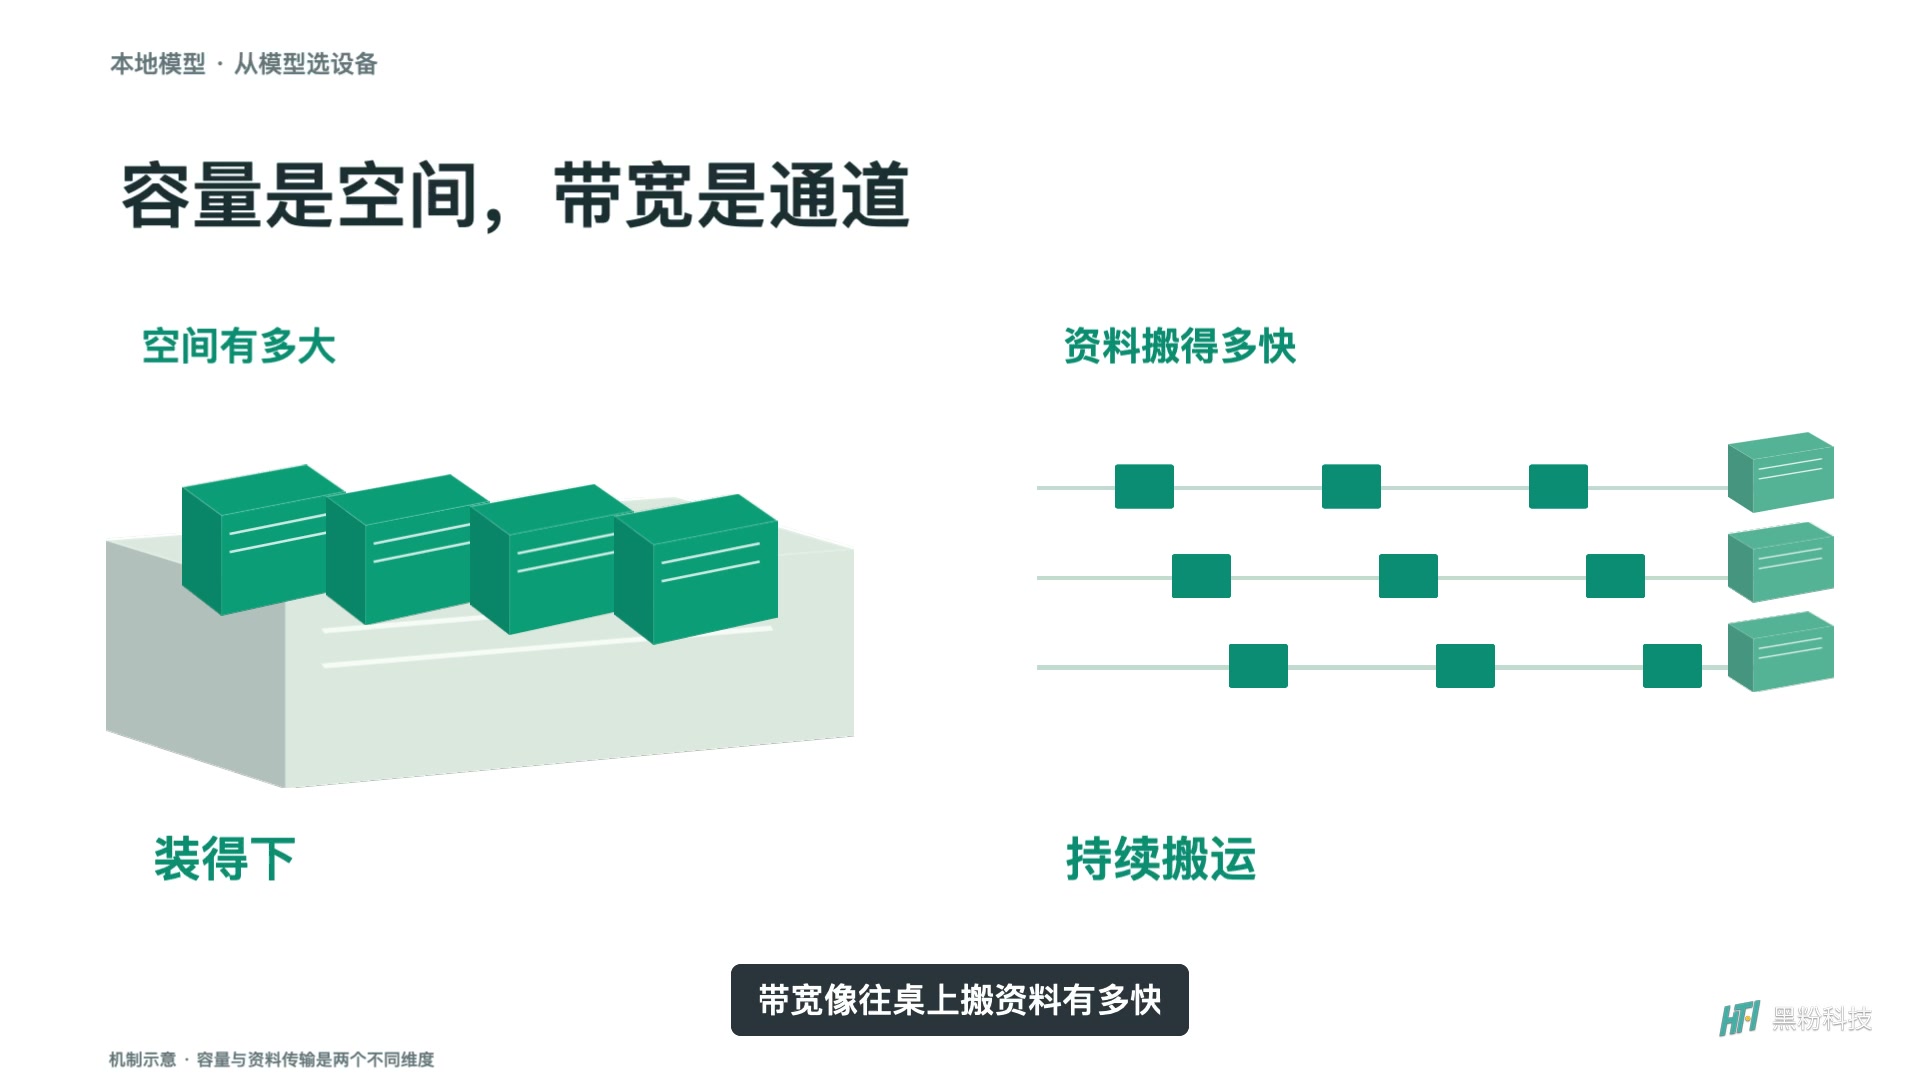
Memory capacity is like desktop area, determining whether a stack of documents can fit; Bandwidth is like the channel that brings data to the table, determining how fast it can be moved. Both cards are labeled 24GB, but that doesn’t mean the generation speed is the same. Conversely, even if a machine has very high bandwidth, it can’t just fill in weights and run buffers exceeding its capacity out of thin air.
Besides weight files, you also need to leave space for context caching, runtime, and other modules. Context caching can be understood as casual notes from the current conversation: the longer the chat, the more notes you keep. The same machine being able to start the model and maintaining the required conversation length over the long term are two usage conditions to check separately.
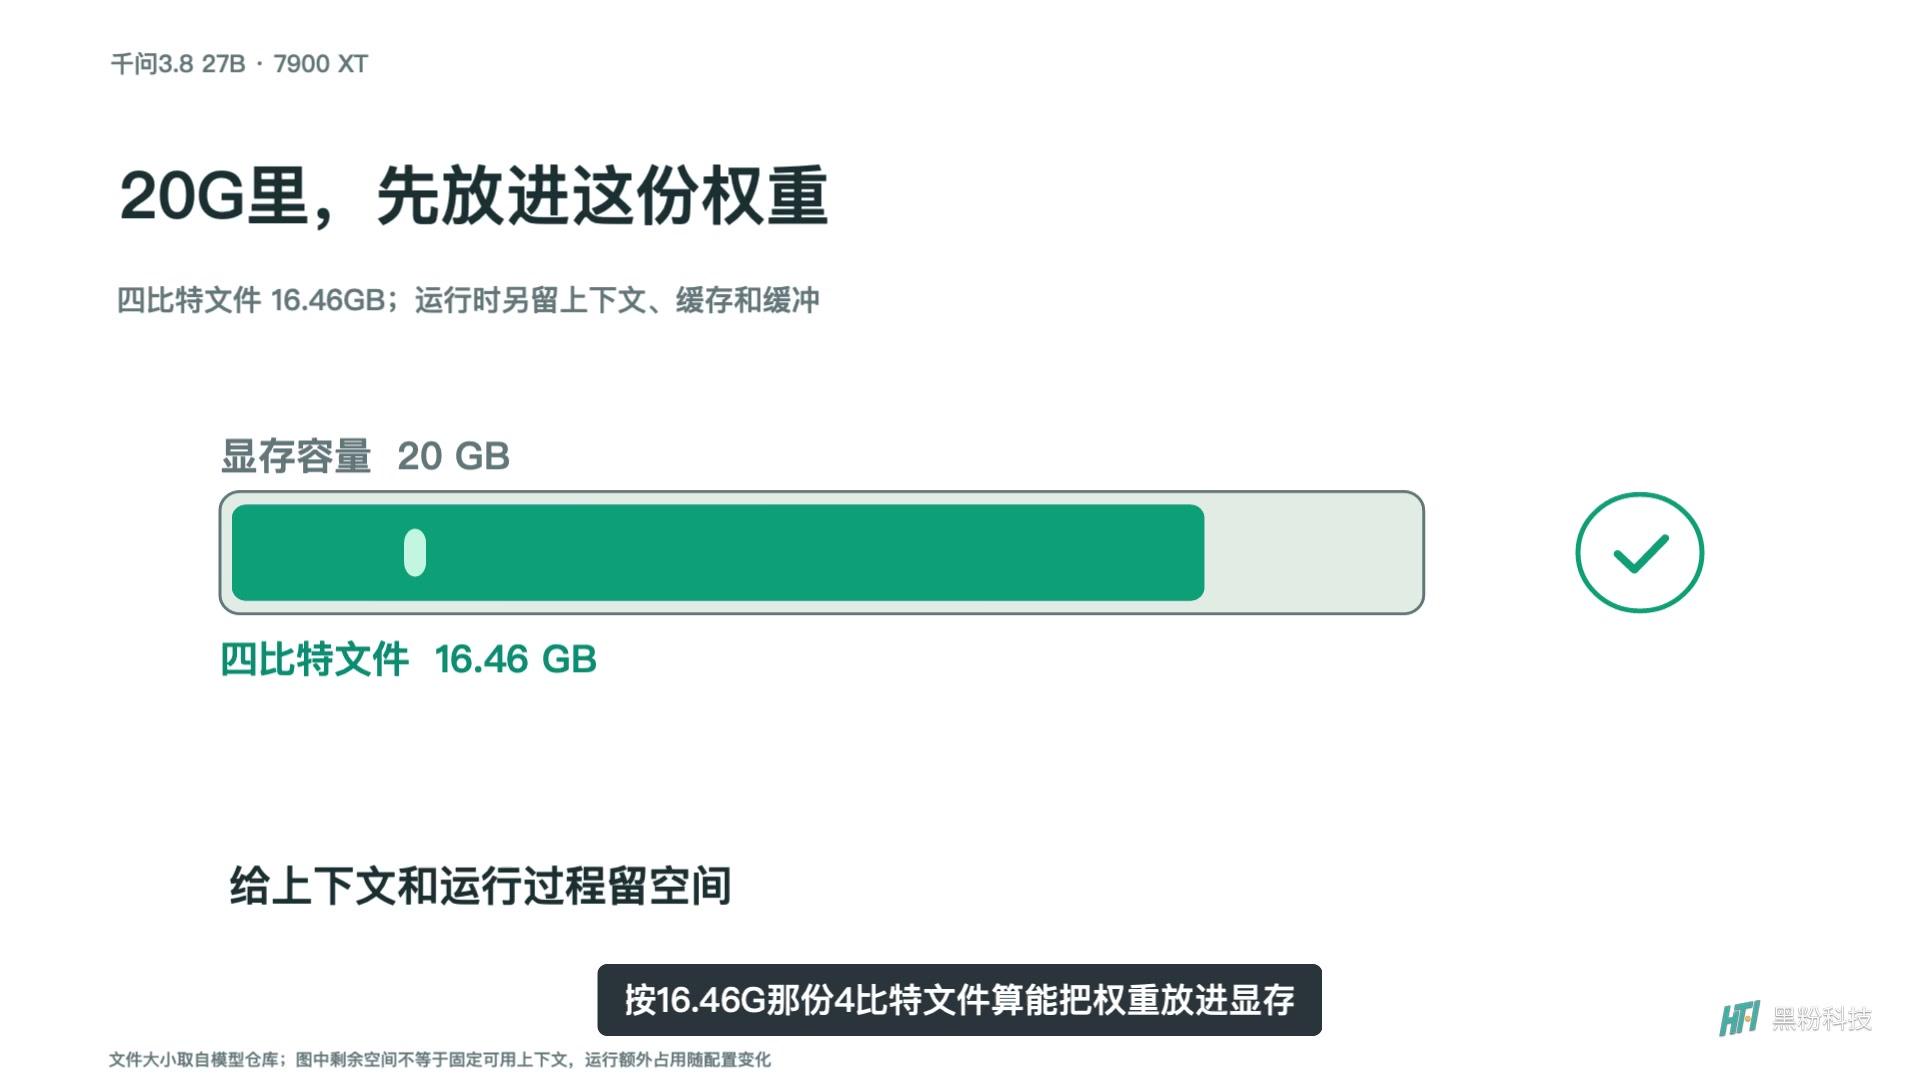
The video uses about 16.46GB of four-bit files to illustrate the 27B storage layout. This is just a quantization file, not “all 27B accounts for just this much.” Before purchasing, download or review the weight list you want to use, then check the engine, cache format, and context settings. Don’t just estimate your budget based on the model name.
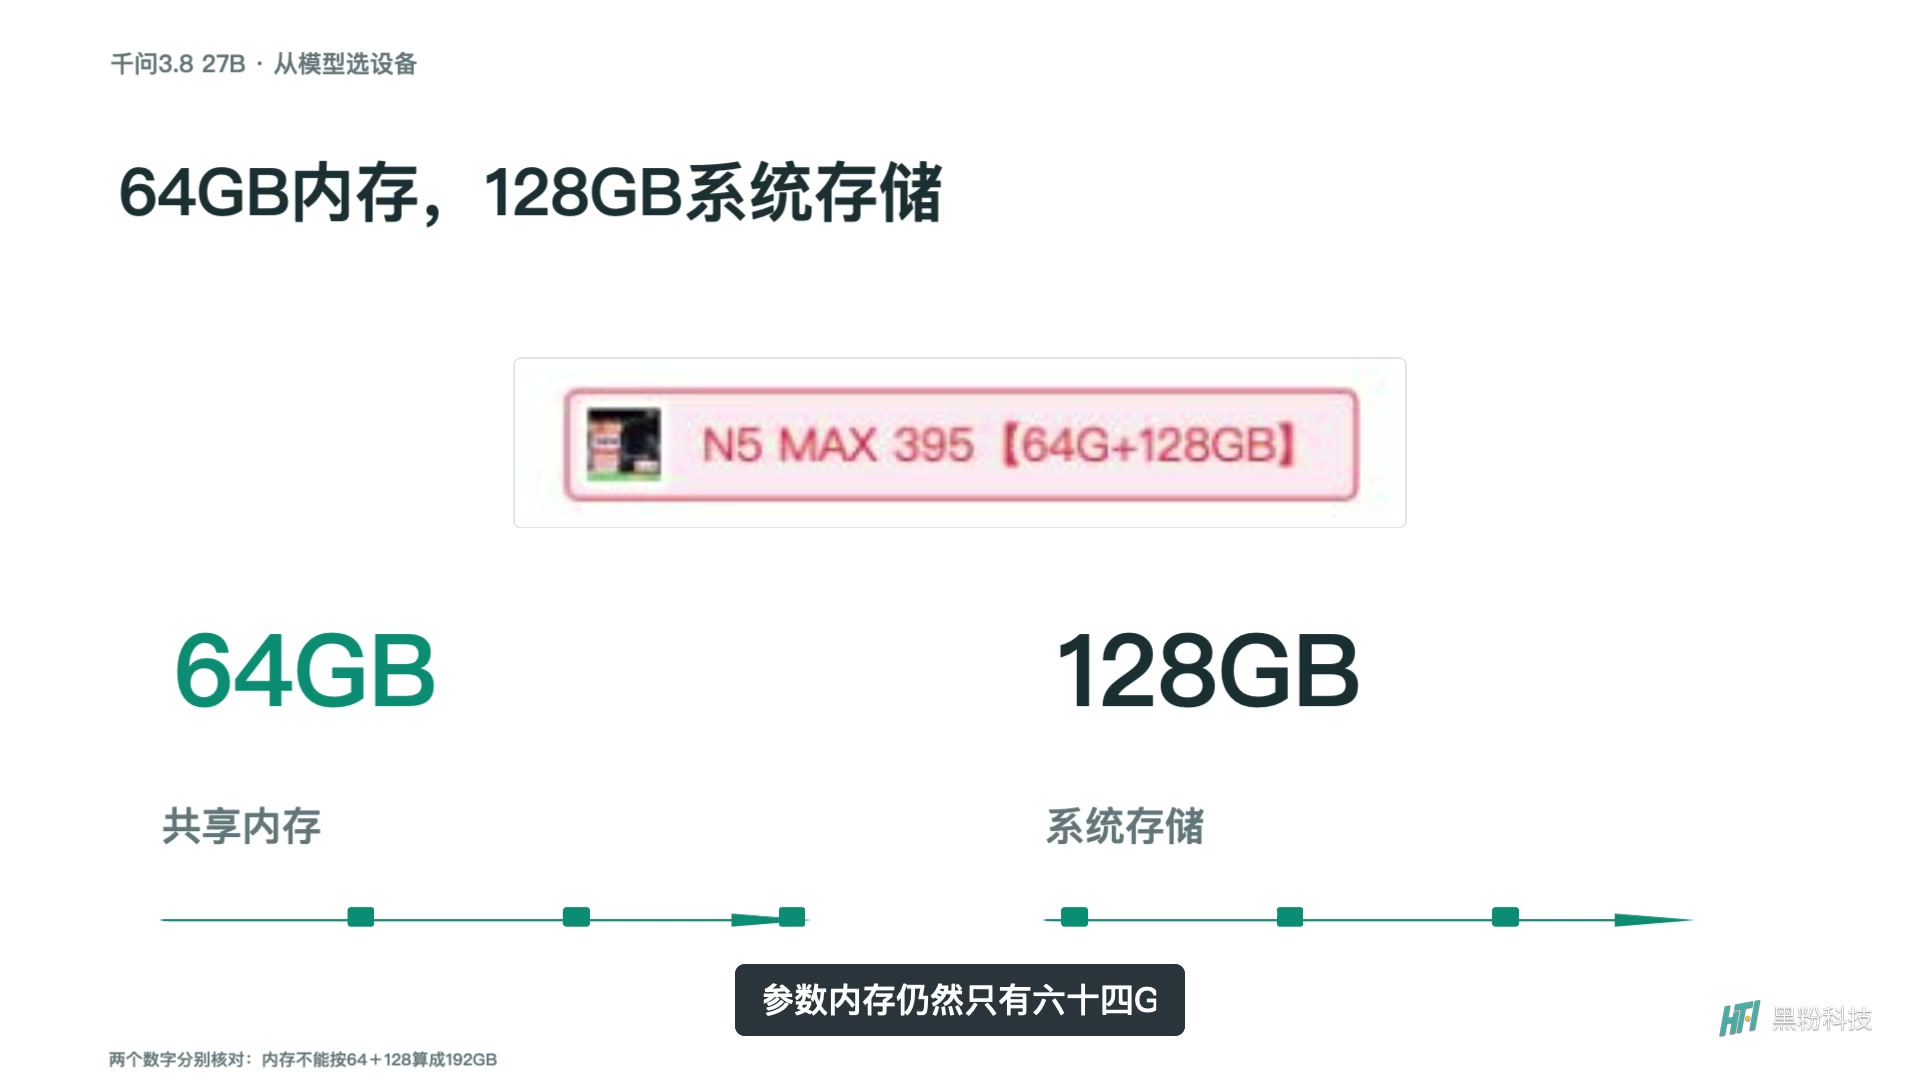
There’s another hidden trap in the product options: the N5 MAX shows “64G+128GB” in the video, but in reality, it’s 64GB of RAM and 128GB of system storage, not 192GB. The hard drive is responsible for long-term storage files, and the memory is for current operation. Even if the names are similar, they shouldn’t be combined. When choosing an SKU, check the parameter details—don’t just look at a line of text on the button.
Qwen 3.8 27B: 24GB old card, large memory whole machine, and new flagship—what can you get?
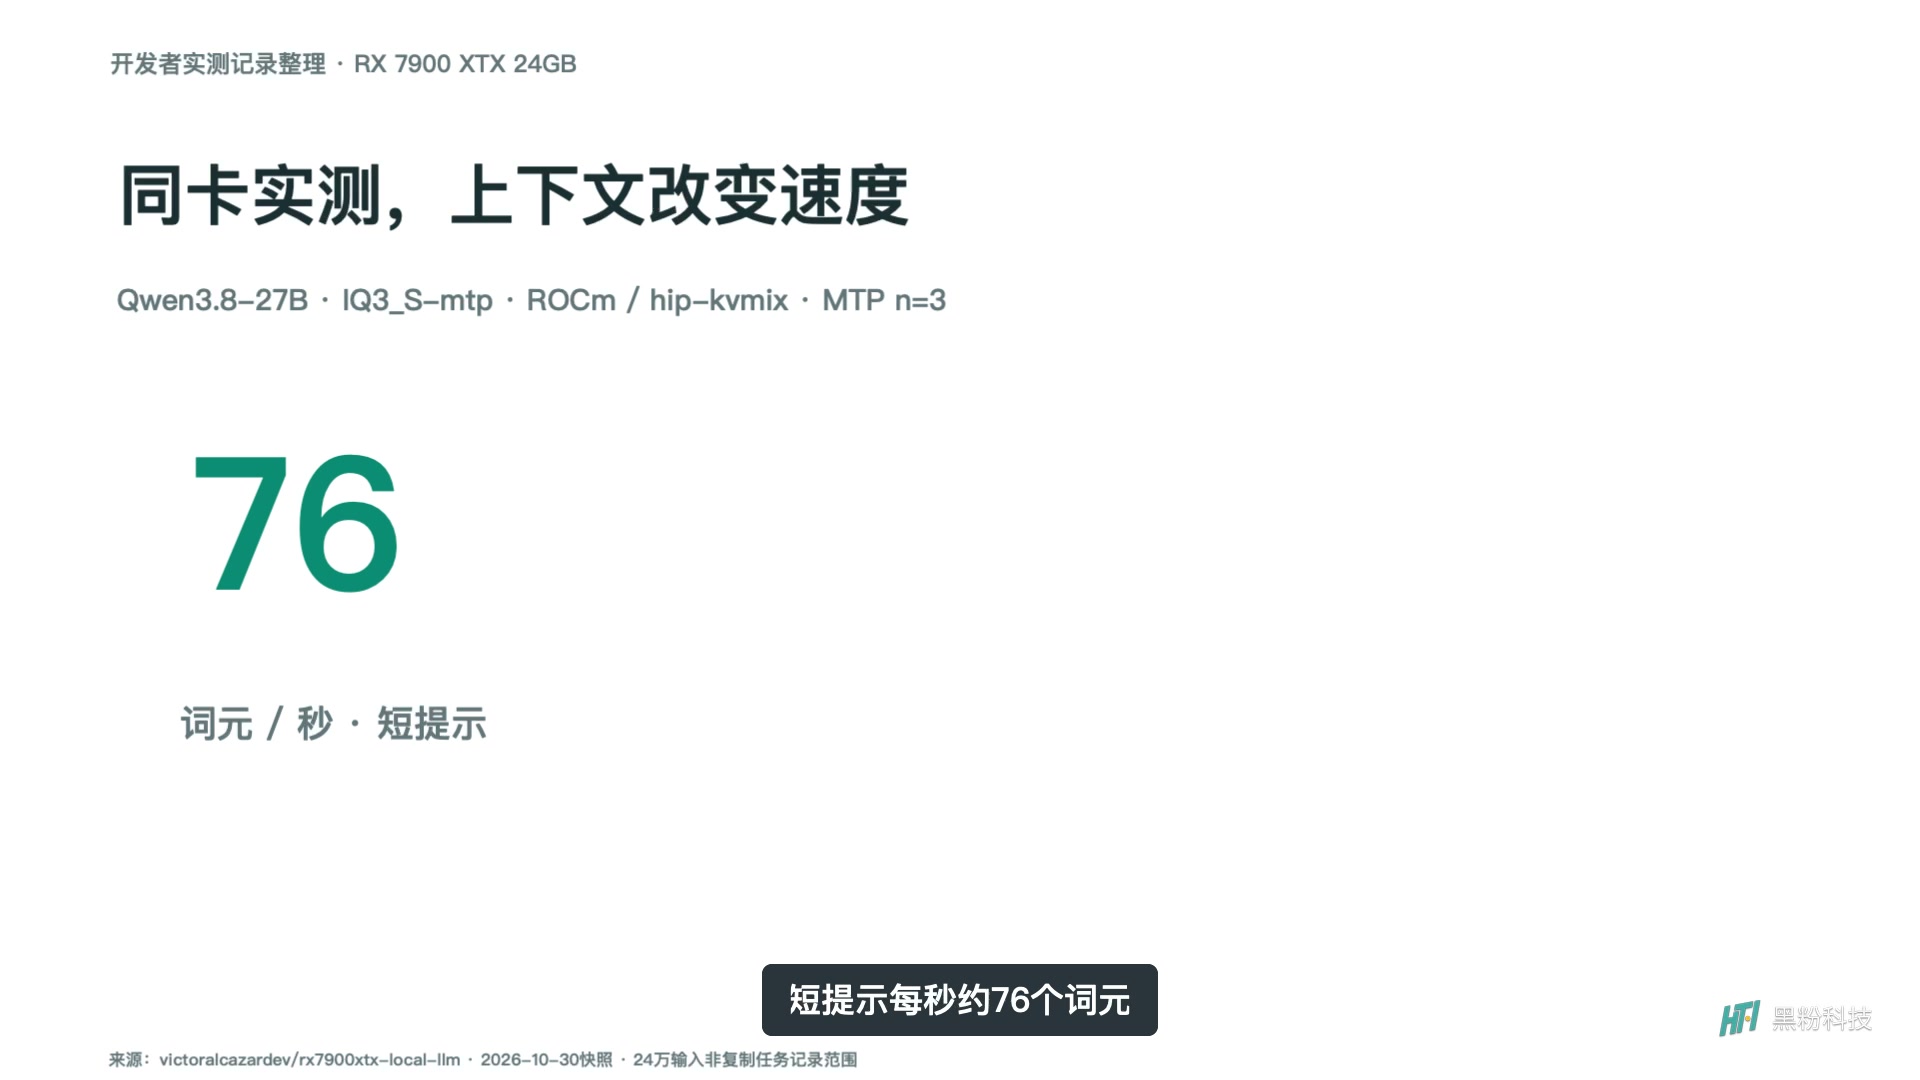
The 20GB 7900 XT and 24GB 7900 XTX are suitable for comparison based on existing consoles and budgets. The corresponding sample prices in the video are 5599 yuan and 6998 yuan, both priced as bare cards. The official specs of the 7900 XTX are 24GB of VRAM and a maximum bandwidth of 960GB/s; This is not equivalent to the test score of about 76 characters per second on the chip. The latter comes from developer records, bundled with a three-bit optimization package, ROCm backend, multi-word prediction, and short cue conditions.
Check AMD’s original specifications to confirm hardware specs; Check the corresponding developer records is the entry point to understand the performance results of that time. Separate these two types of evidence to avoid mistakenly converting nominal bandwidth to output speed when selecting a card.
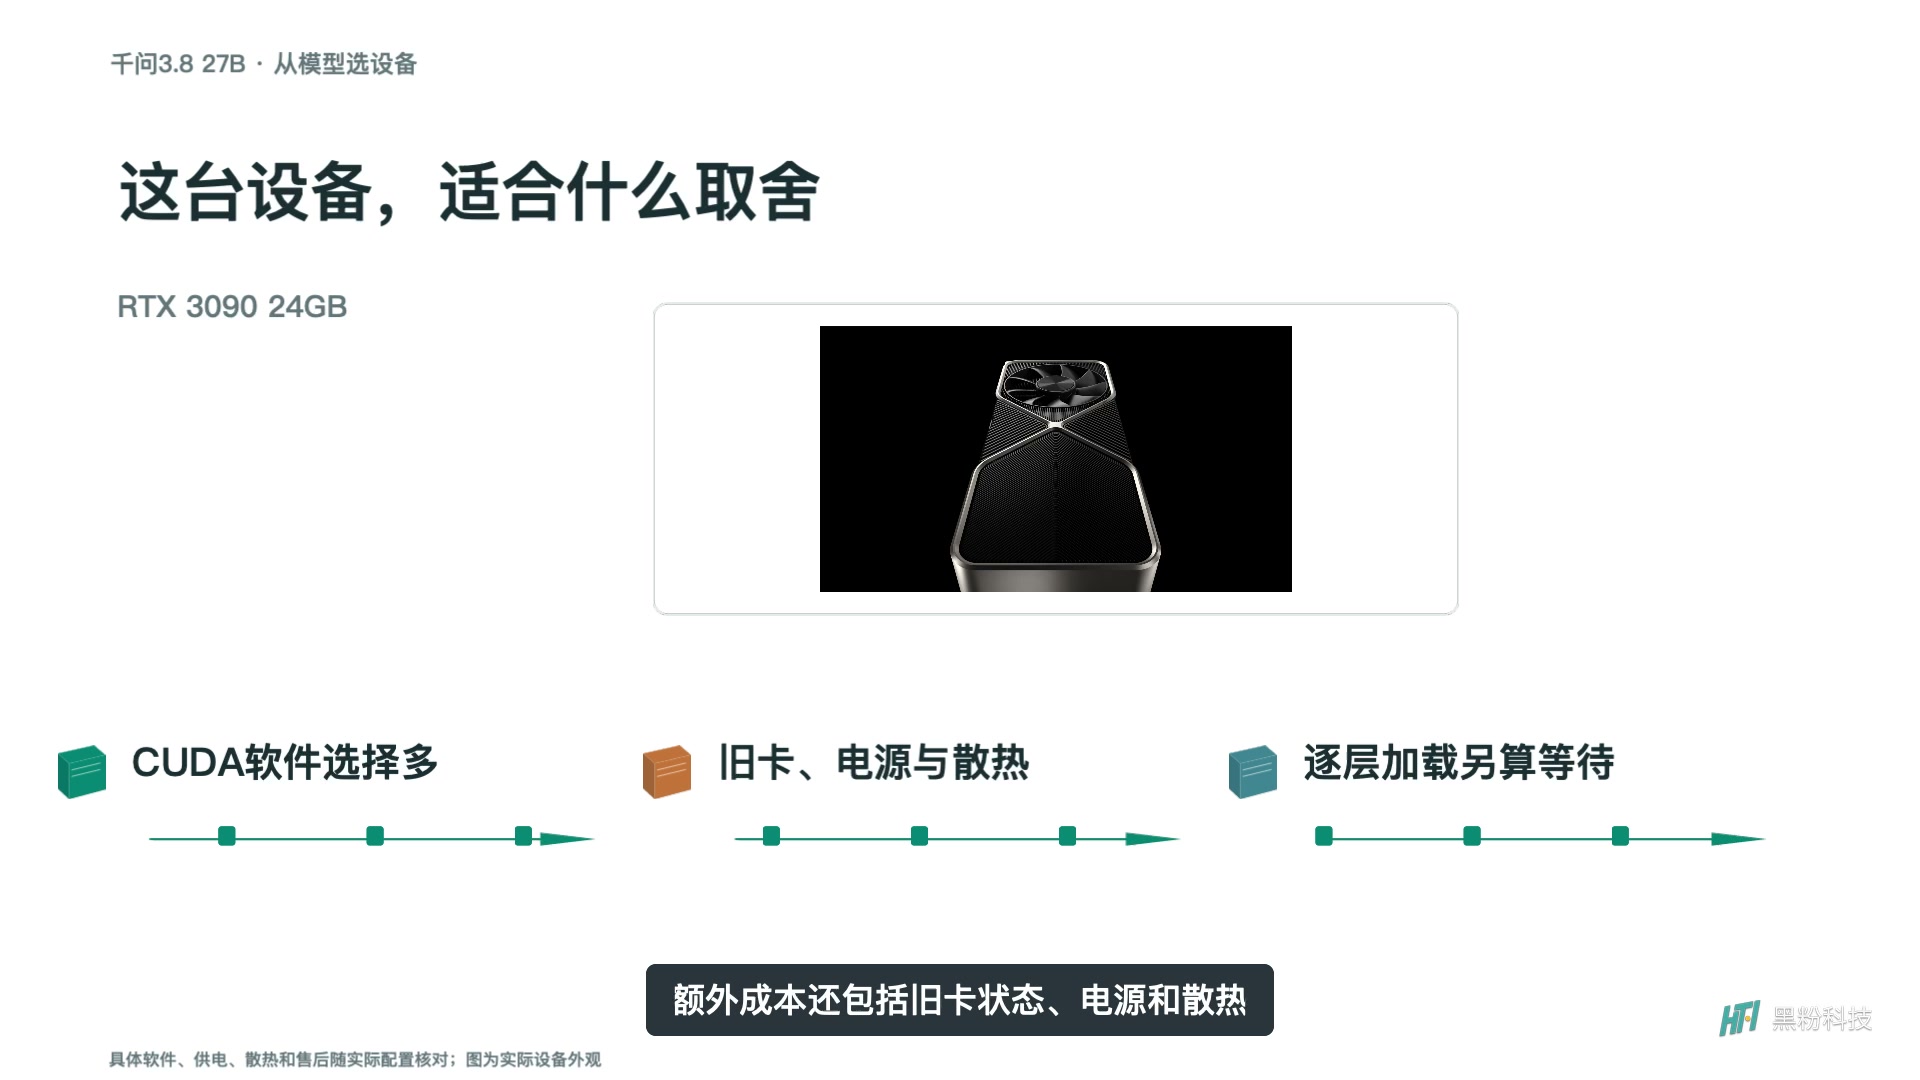
The 3090 is also 24GB, and one of its main attractions is the wide variety of CUDA software options, but the second-hand sample at 11,800 yuan isn’t naturally more cost-effective than the previous one. You have to calculate the condition of the old card, power supply, cooling, and after-sales service together. The 4090 and 5090 D v2 chips are still 24GB: upgraded computing power and bandwidth, but the model doesn’t increase in price year-over-year.
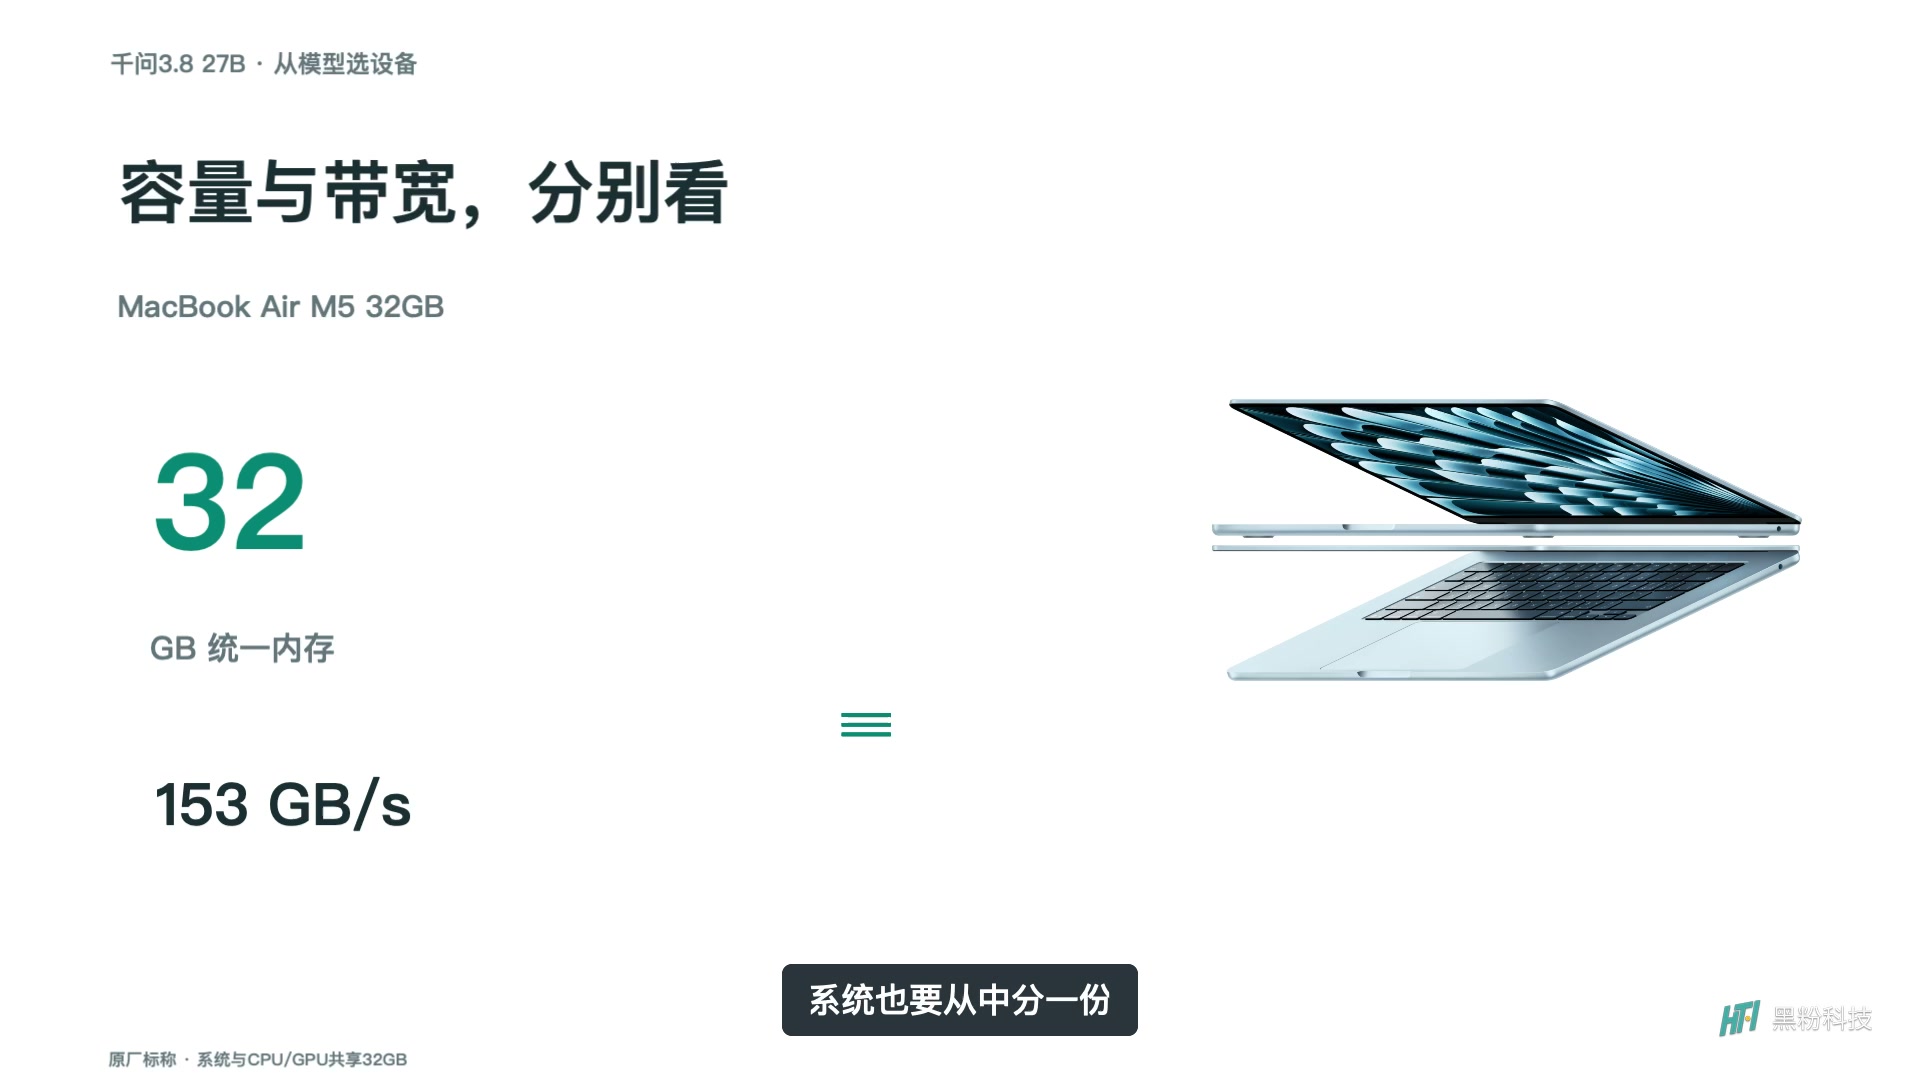
If you want to take it with you, the MacBook Air’s lightness, quietness, and unified memory are attractive; Unified memory is a pool shared by the system, processor, and graphics processor, not all reserved for the model. The 32GB Air and 64GB N5 MAX and 32GB R9700 memory have different trade-offs, so it’s not suitable to order just by ranking capacity.
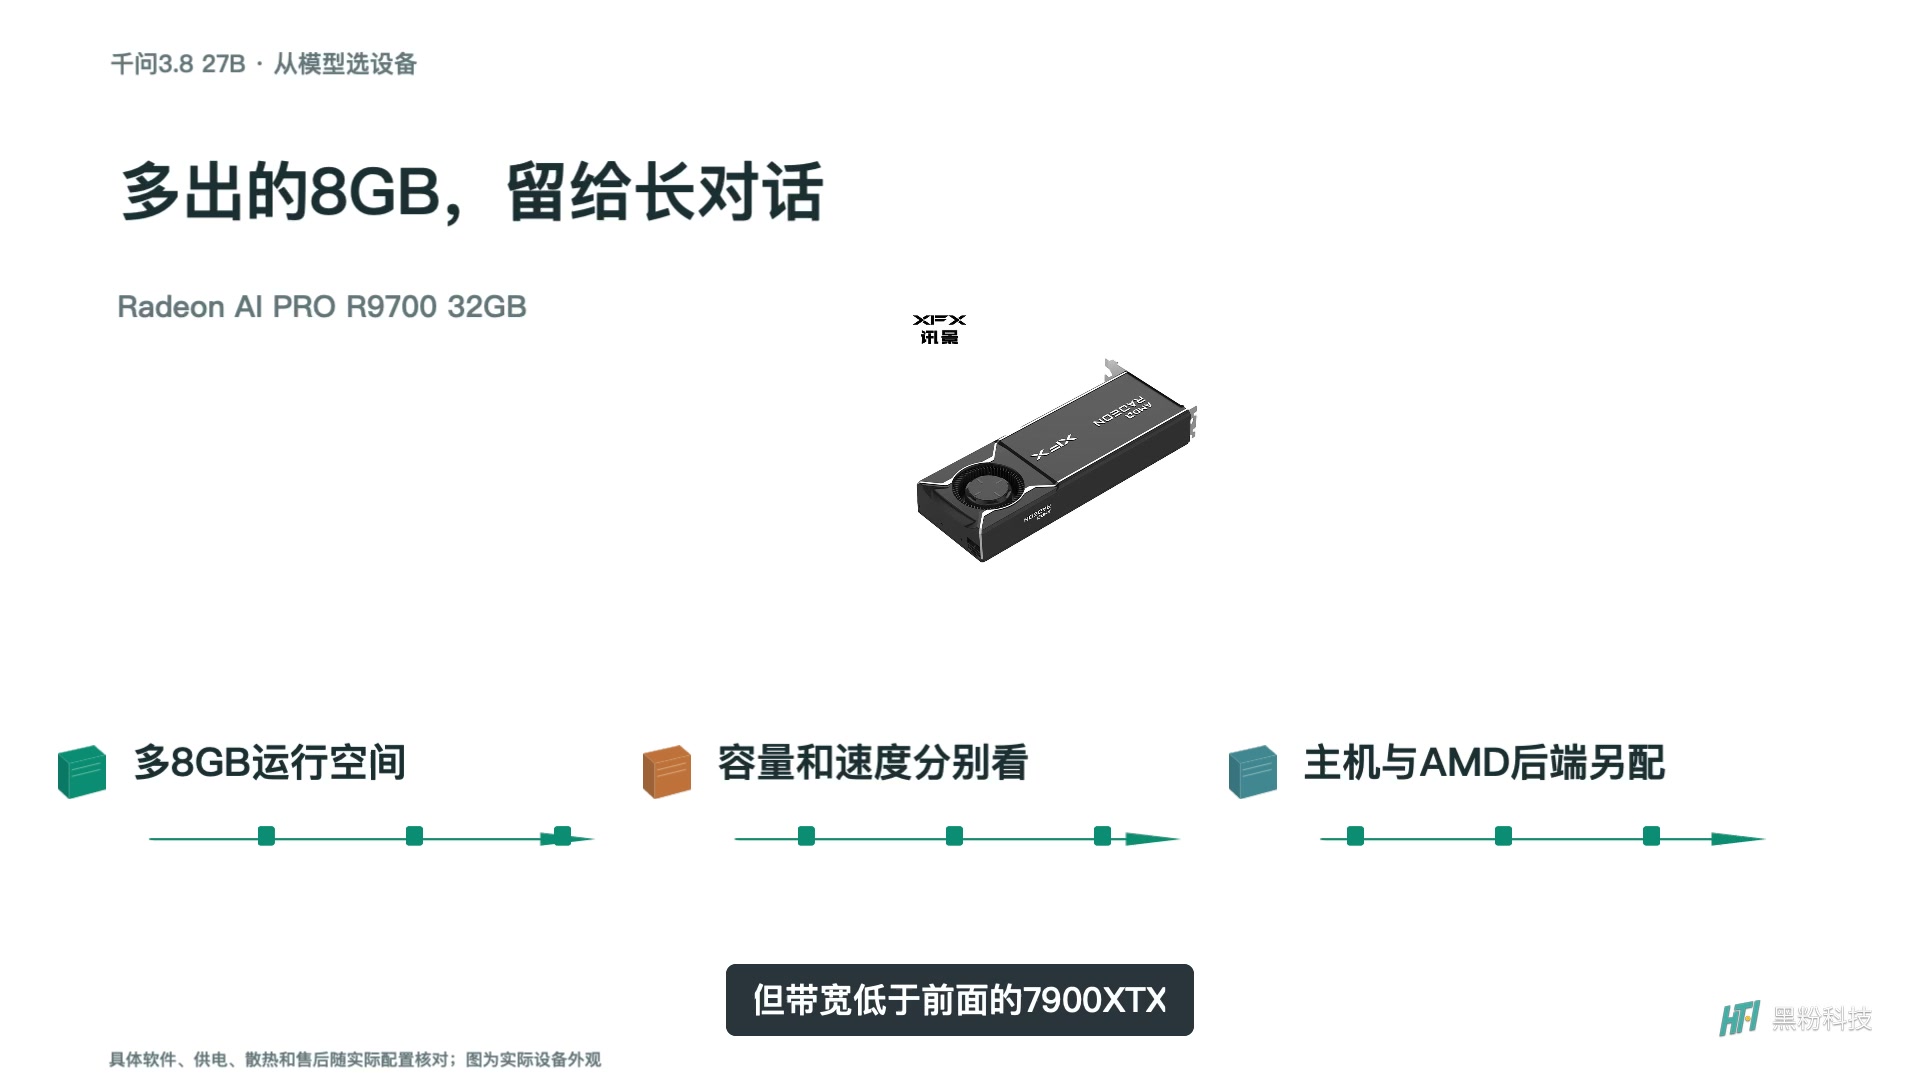
The R9700 offers 32GB of VRAM, but its bandwidth is lower than the chip’s 7900 XTX. This perfectly illustrates the problem: if the original GPU can’t fit it, a larger capacity can solve the problem; If it already can, the speed depends on the engine’s actual performance.
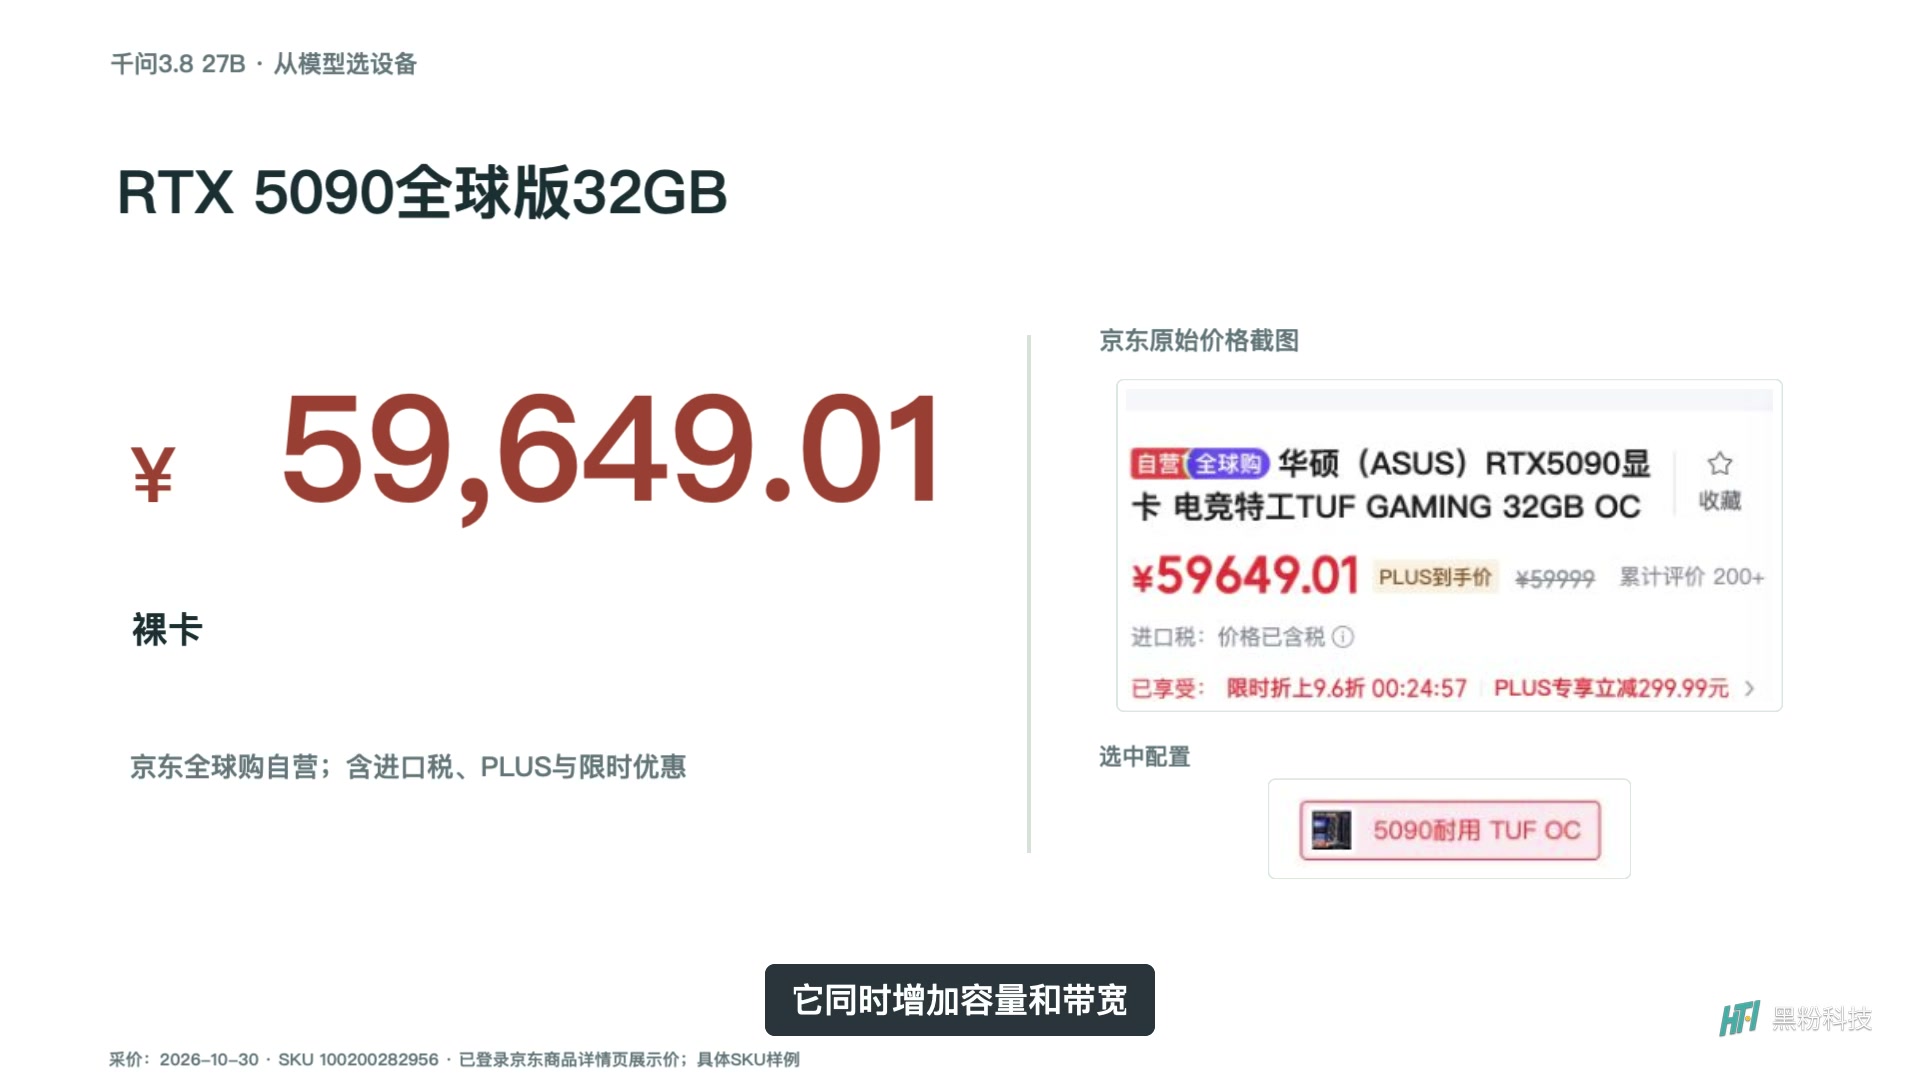
The global 5090’s 32GB does increase both capacity and bandwidth, but the long-context cases cited in the video perform differently under different engines, single-card, and dual-SIM conditions. For those who already have a 24GB card, I recommend first checking the target weight and software route before deciding exactly what the card replacement solves, rather than repeatedly paying for an updated number.
| Equipment/selected configuration | Capacity | Bandwidth and diameter | Snapshot prices and range |
|---|---|---|---|
| RX 7900 XT 20GB | 20GB of dedicated video memory | 800GB/s | 5,599 yuan · Bare card |
| RX 7900 XTX 24GB | 24GB of dedicated video memory | 960GB/s | 6,998 yuan · Bare card |
| RTX 3090 24GB | 24GB of dedicated video memory | 936GB/s | 11,800 yuan · Bare card |
| MacBook Air M5 32GB | 32GB of unified memory | 153GB/s | 13,673 yuan · Complete machine |
| Mingfan N5 MAX AI Max 395 64GB | 64GB of shared system memory | 273.056GB/s | 15,599 yuan · Complete machine |
| Radeon AI PRO R9700 32GB | 32GB dedicated VRAM | 640GB/s | 17,899 yuan · Bare card |
| RTX 4090 24GB | 24GB of dedicated video memory | 1008GB/s | 27,799 yuan · Bare card |
| YOGA Pro15 RTX Spark 128GB | 128GB of unified memory | Not verified/configured according to the configuration | 41,284 yuan · Complete machine |
| RTX 5090 D v2 24GB | 24GB of dedicated video memory | 1344GB/s | 44,892 yuan · Bare card |
| RTX 5090 Global Edition 32GB | 32GB dedicated VRAM | 1792GB/s | 59,649 yuan · Bare card |
Snapshot of selected SKUs dated 2026-10-30; Performance depends on the specific weights and engines mentioned in the main text.
Flash-Next: Small video memory can run, provided the entire set is written
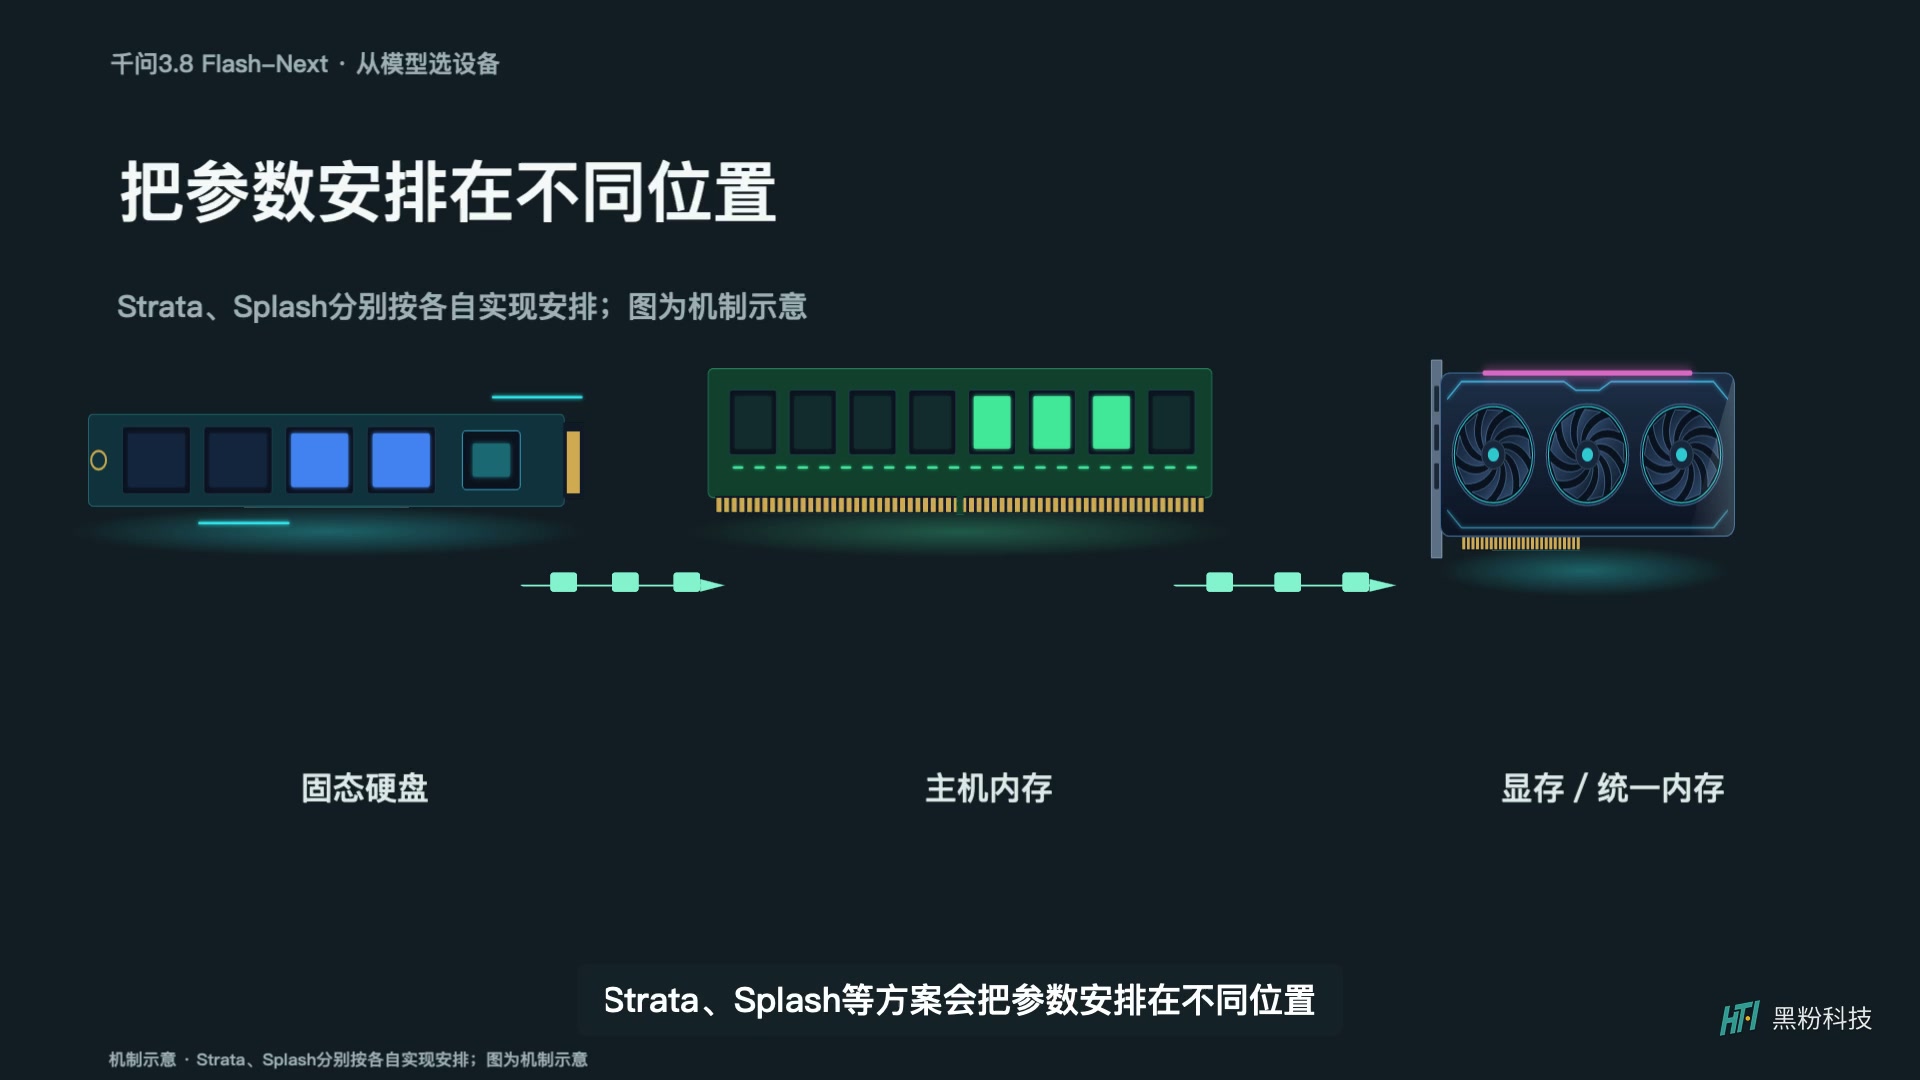
The standard four-bit file size for Flash-Next in this issue is about 94~111GB. Seeing this scale, don’t rush to mistake the “small video memory can run” record as a contradiction: some solutions distribute parameters across the graphics card, host memory, or even hard drive. It’s like frequently flipping data on a desk and less frequently left in a cabinet; the desk can be smaller, but the cost of moving back and forth cannot be ignored.
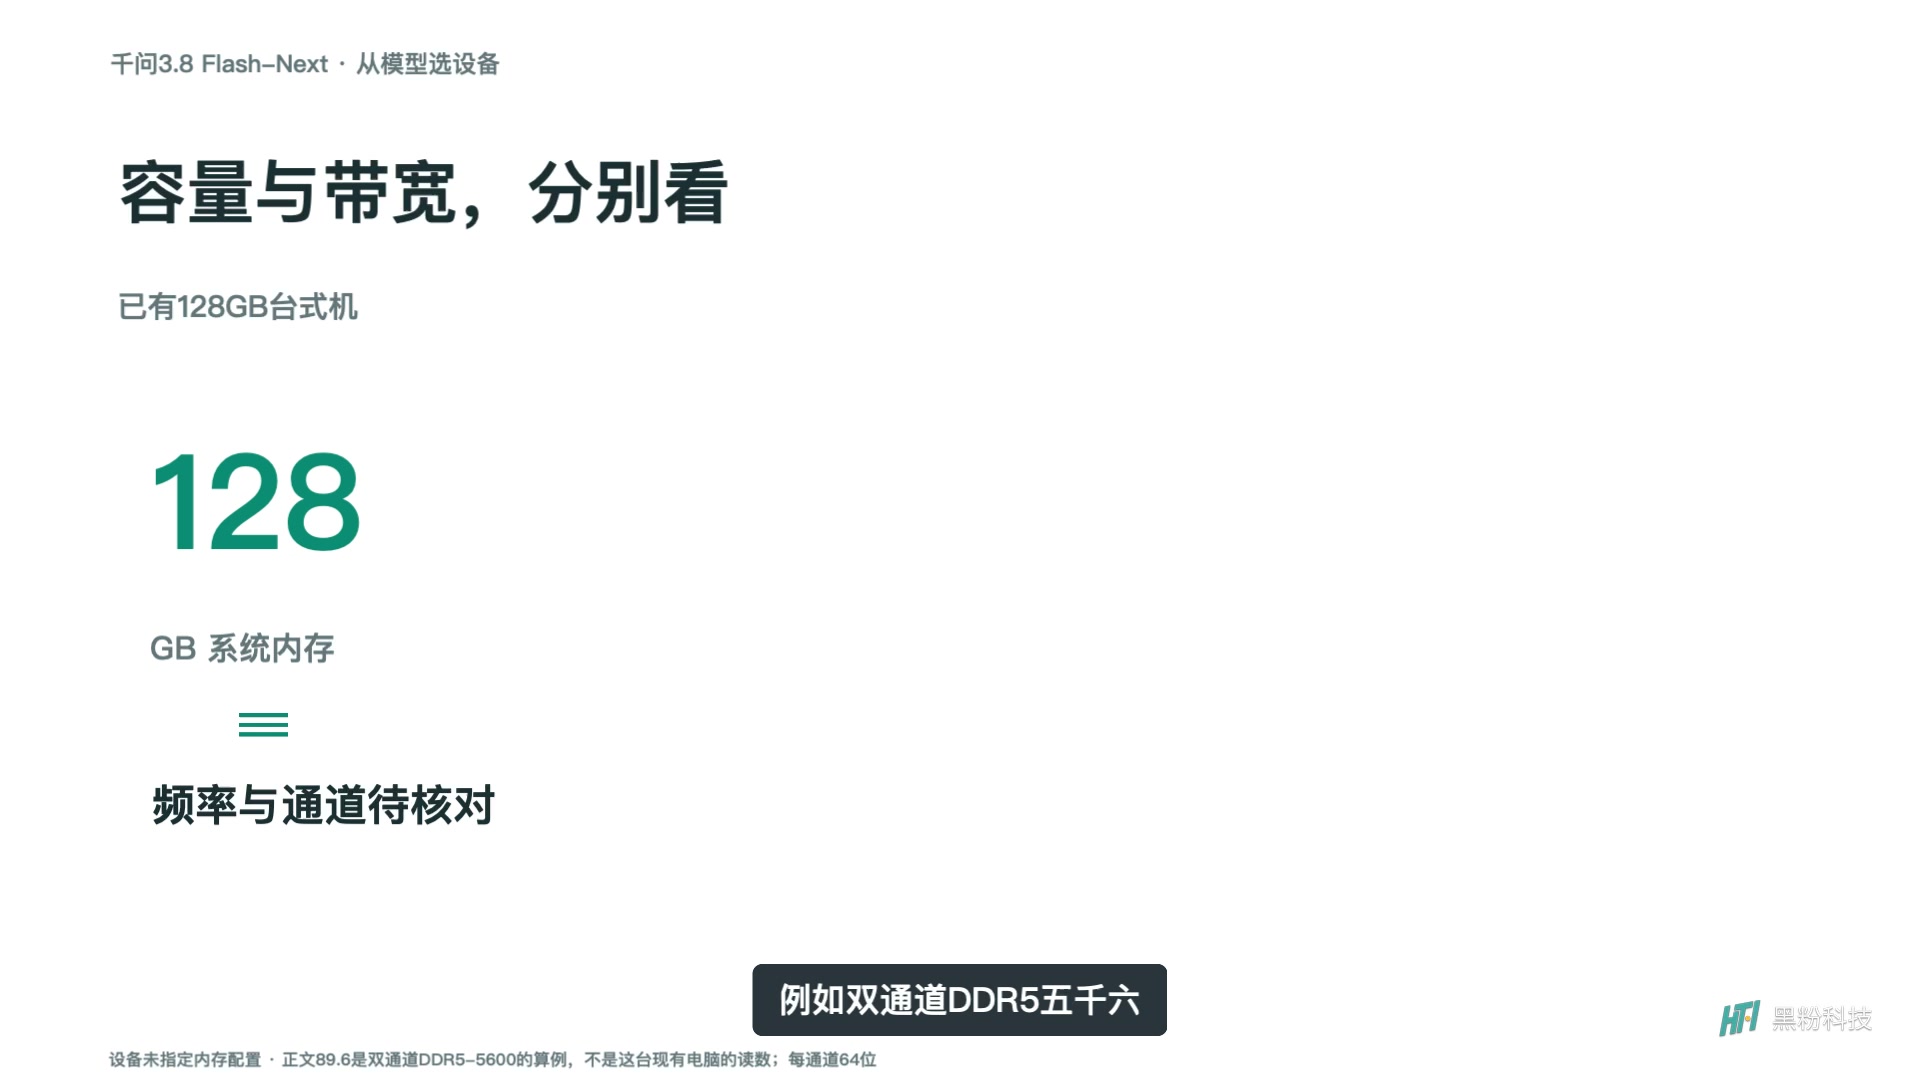
If you already have a 128GB memory desktop, try it with your existing device; the cost of adding new hardware can be zero. This doesn’t mean a whole PC is free; Nor does it mean DDR4 and DDR5 hosts of the same capacity will have the same speed. If you already have a 64GB M5 Pro, you can first study matching Splash quantization and draft models, without having to slaughter your old device first.
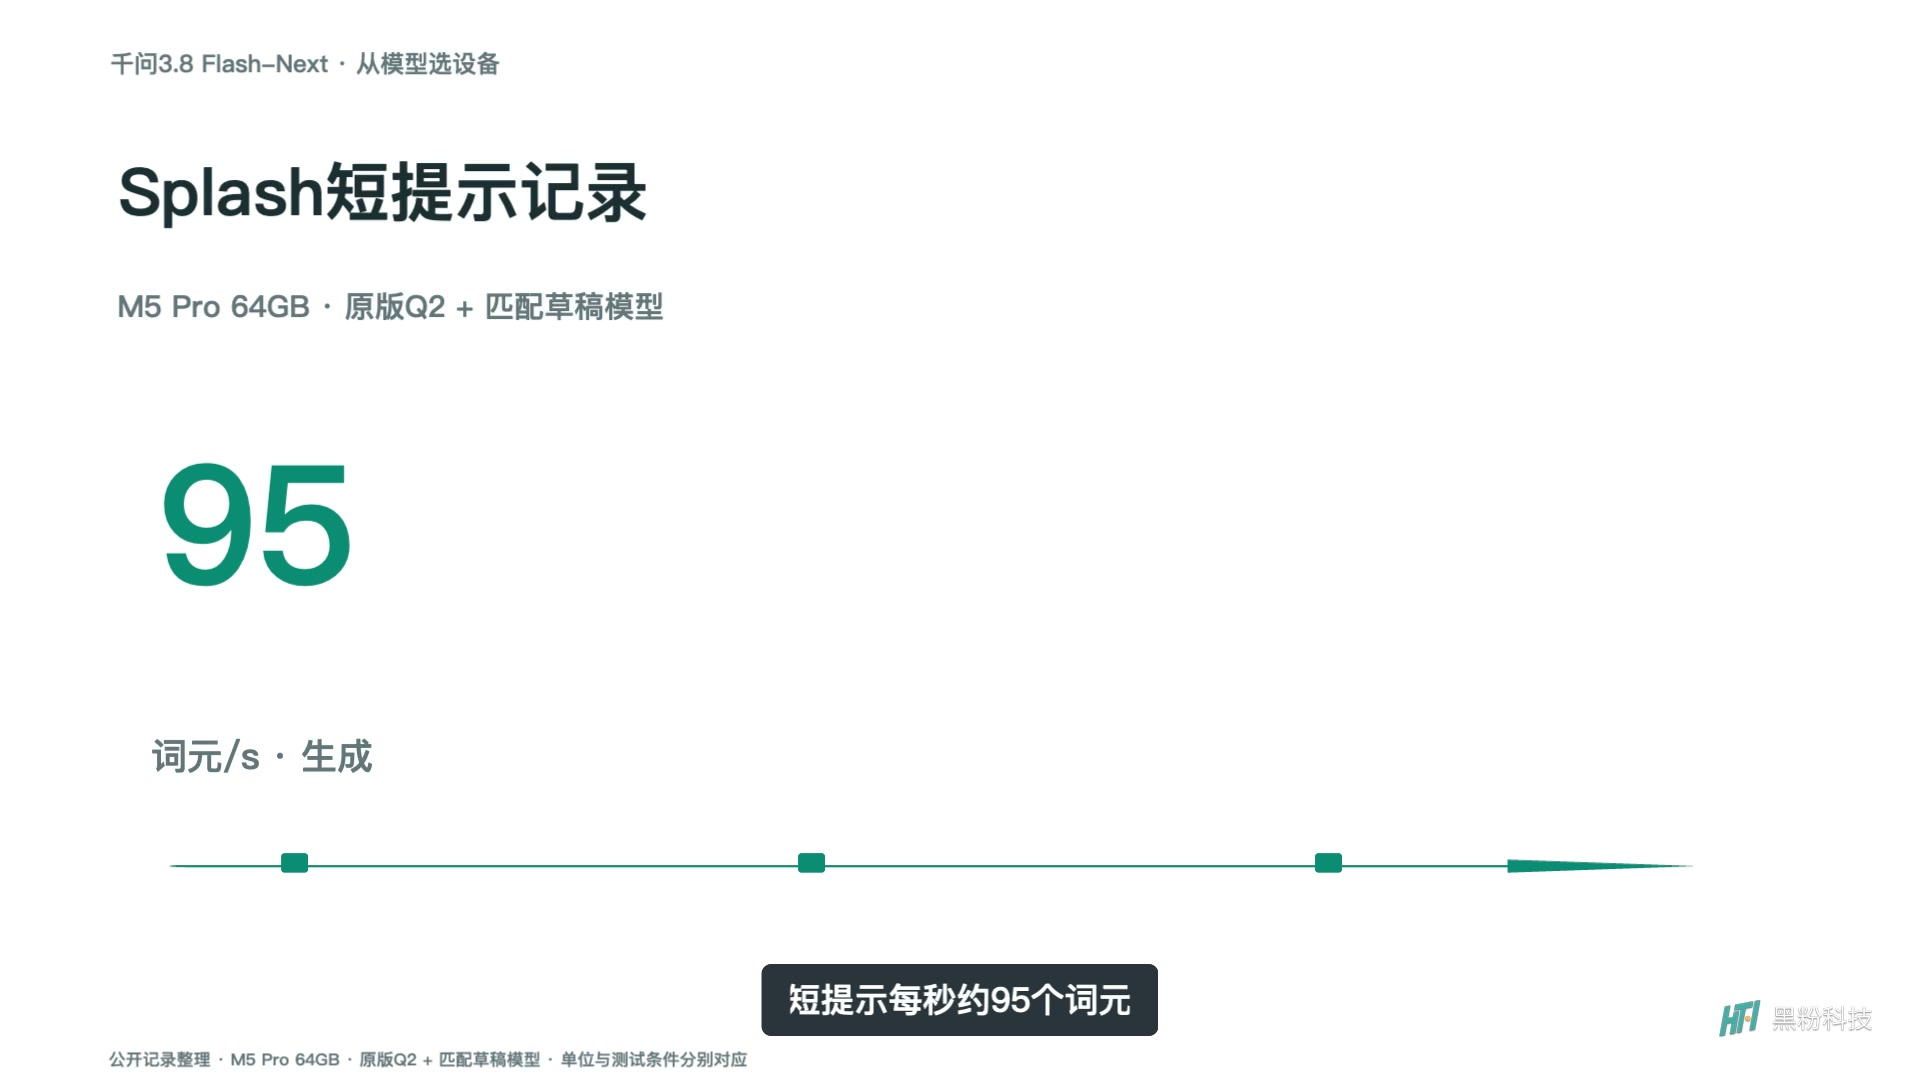
Splash in the video is about 95 words per second, which is a short prompt record for developers under the corresponding M5 Pro, Q2 package, and draft model conditions. The draft model can be understood as first writing a candidate answer, then having it checked by the main model, saving some word-by-word generation waiting; It is not the same optimization as reducing weight accuracy. Deployment entry points and currently supported formats can be found in Splash project description.
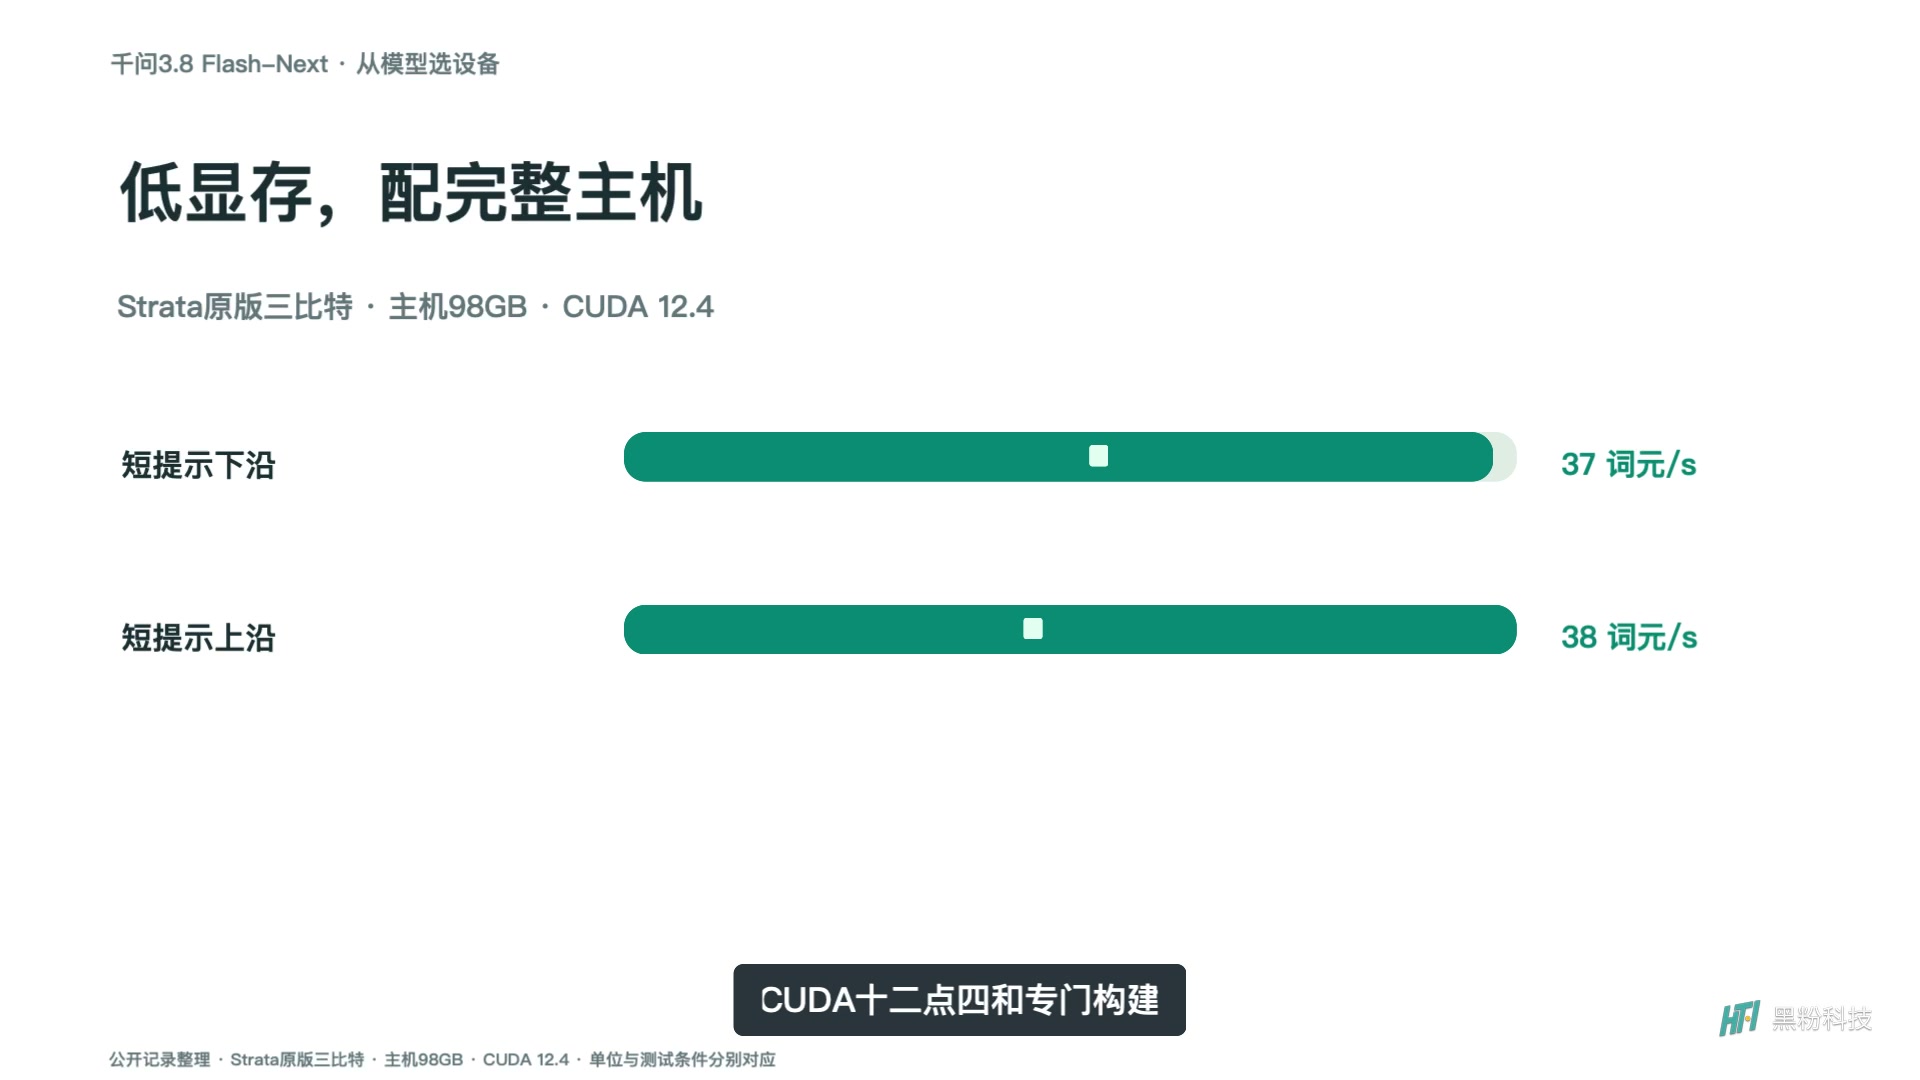
The P40 bare card sample at 1850 yuan is eye-catching, but the Strata test in the video also includes about 98GB of main memory, a CUDA environment, and a dedicated build. The 3060 route also requires 64GB of RAM and NVMe hard drive on the cost sheet; you can’t expect to replicate the full set of results just by buying a 12GB graphics card.
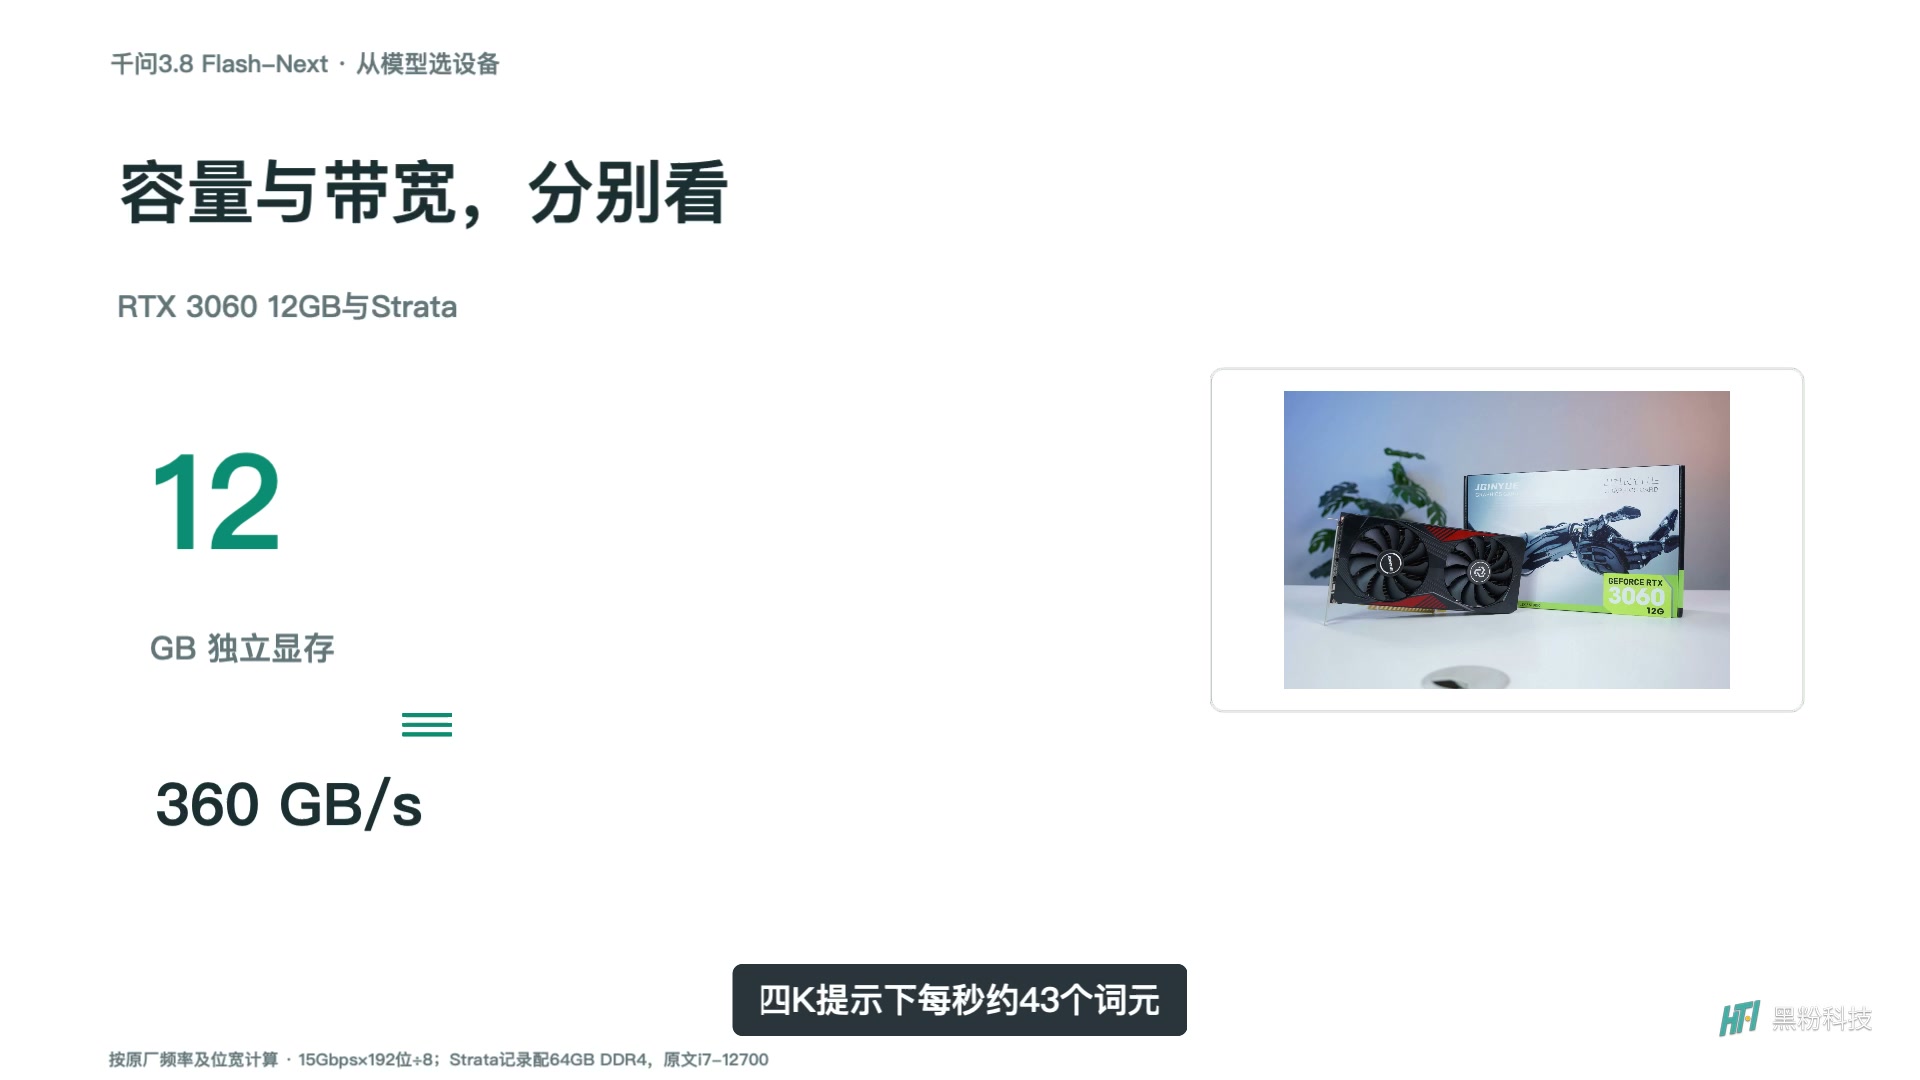
On the same 3060 main unit, the Q2 and 3-bit package records cited in the chip show a noticeable speed difference. Therefore, when looking at a chart showing “how many words per second,” at least the card, memory, quantization packet, prompt length, and initial time are all recorded simultaneously. If you want to replicate it, first check the Strata project and its test record entry; don’t just copy the result numbers.
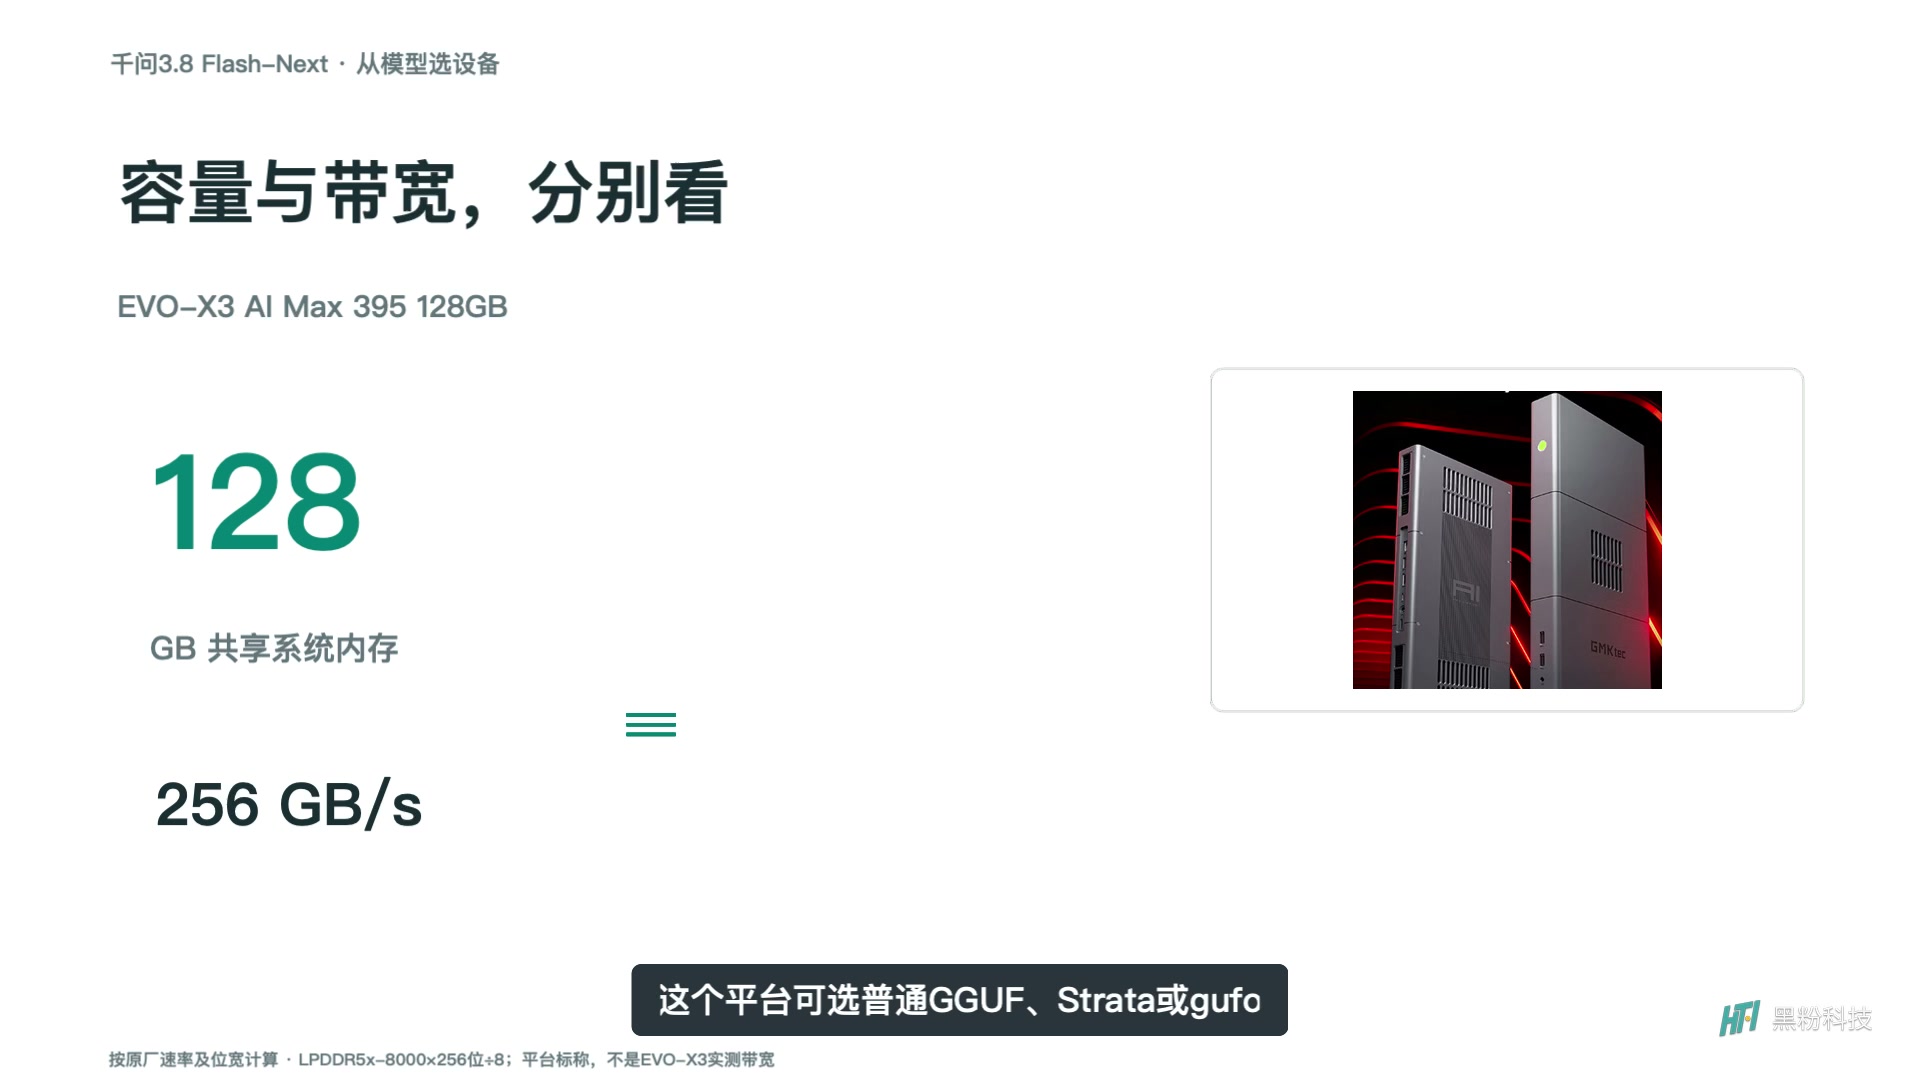
If you don’t want to assemble a host or deal with old cards, the 128GB shared memory offers another solution. Both the EVO-X3 and ProArt Chuang 13 use the AI Max 395 platform, and the desktop and laptop price differences include portability, sustained power consumption, cooling, and overall system design. Even with the same processor name, you can’t skip the specific SKU verification.
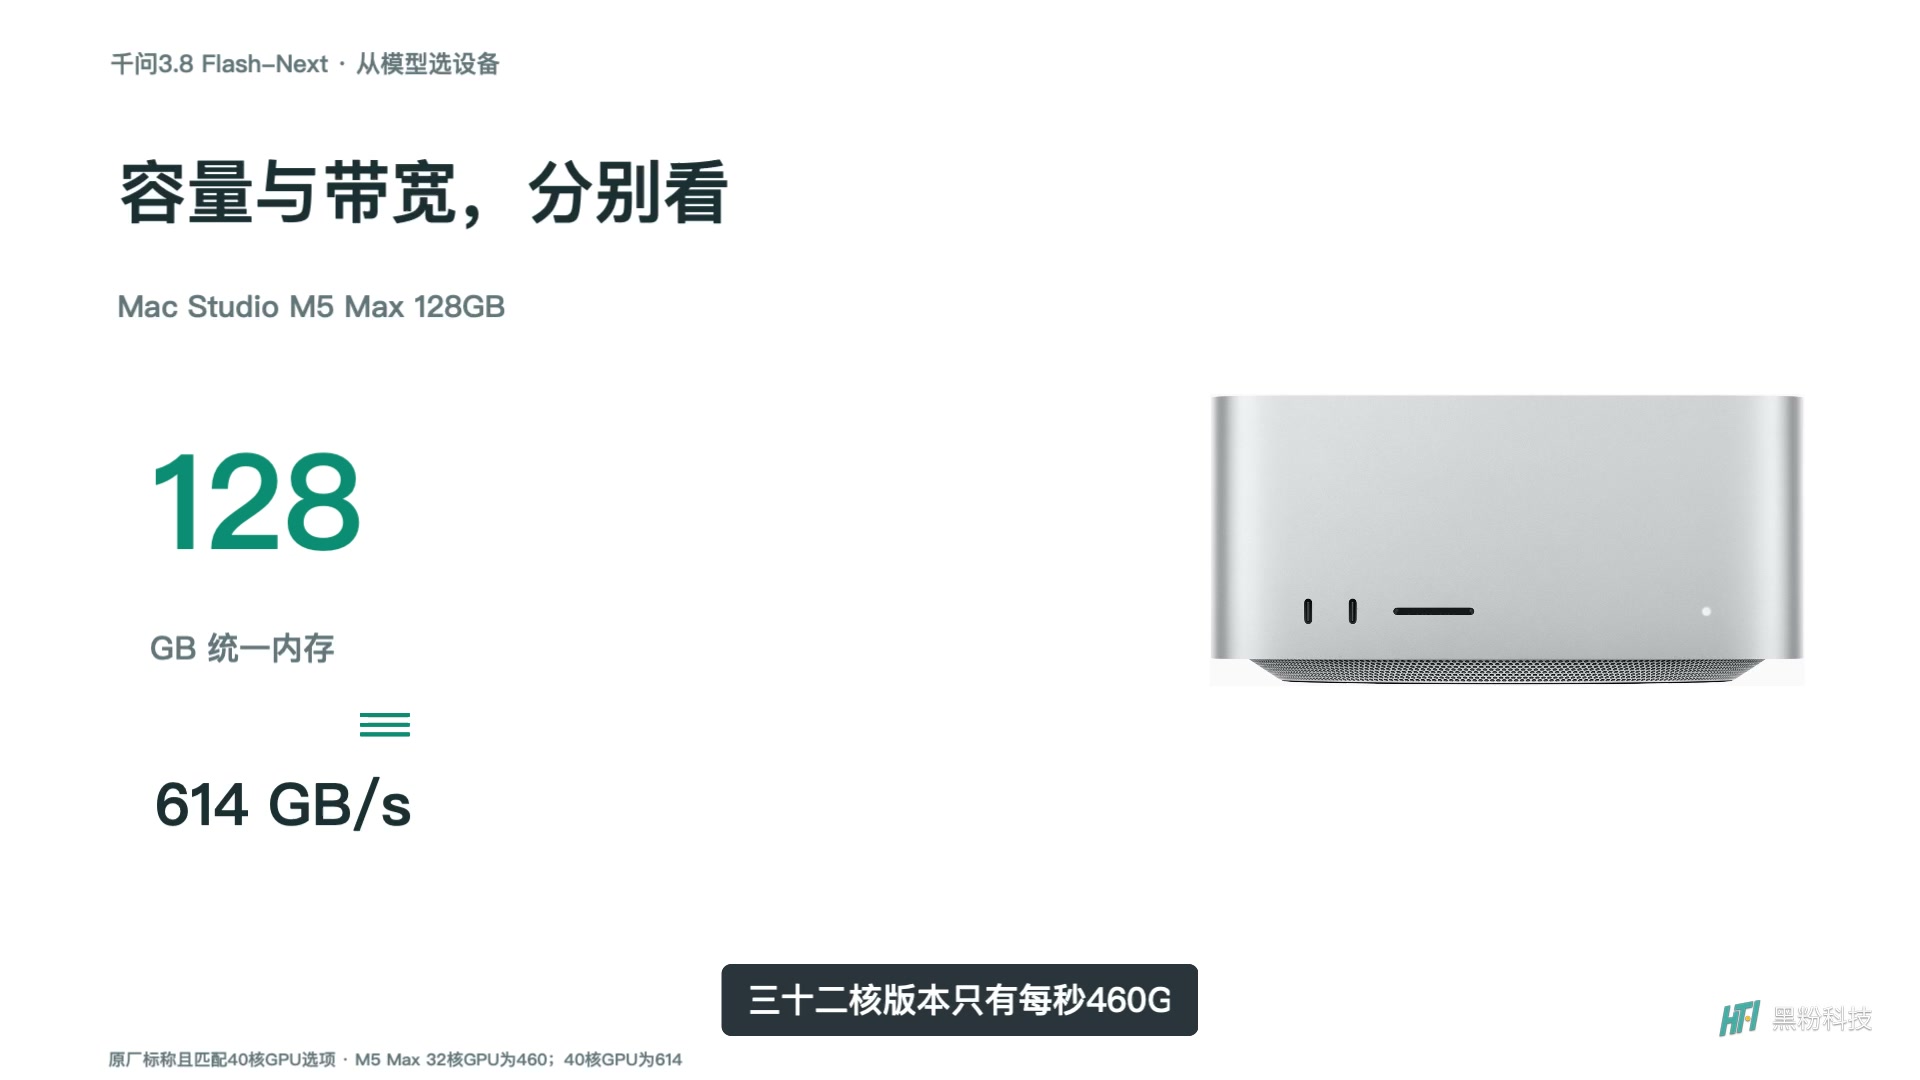
Mac Studio and MacBook Pro also depend on the specific M5 Max tier. The 40-core GPU version is rated at 614GB/s, while the 32-core version is on a different level; Recognizing only “M5 Max” can easily confuse different configurations. Capacity is usually decided at purchase, and future upgrade options should be considered in advance.
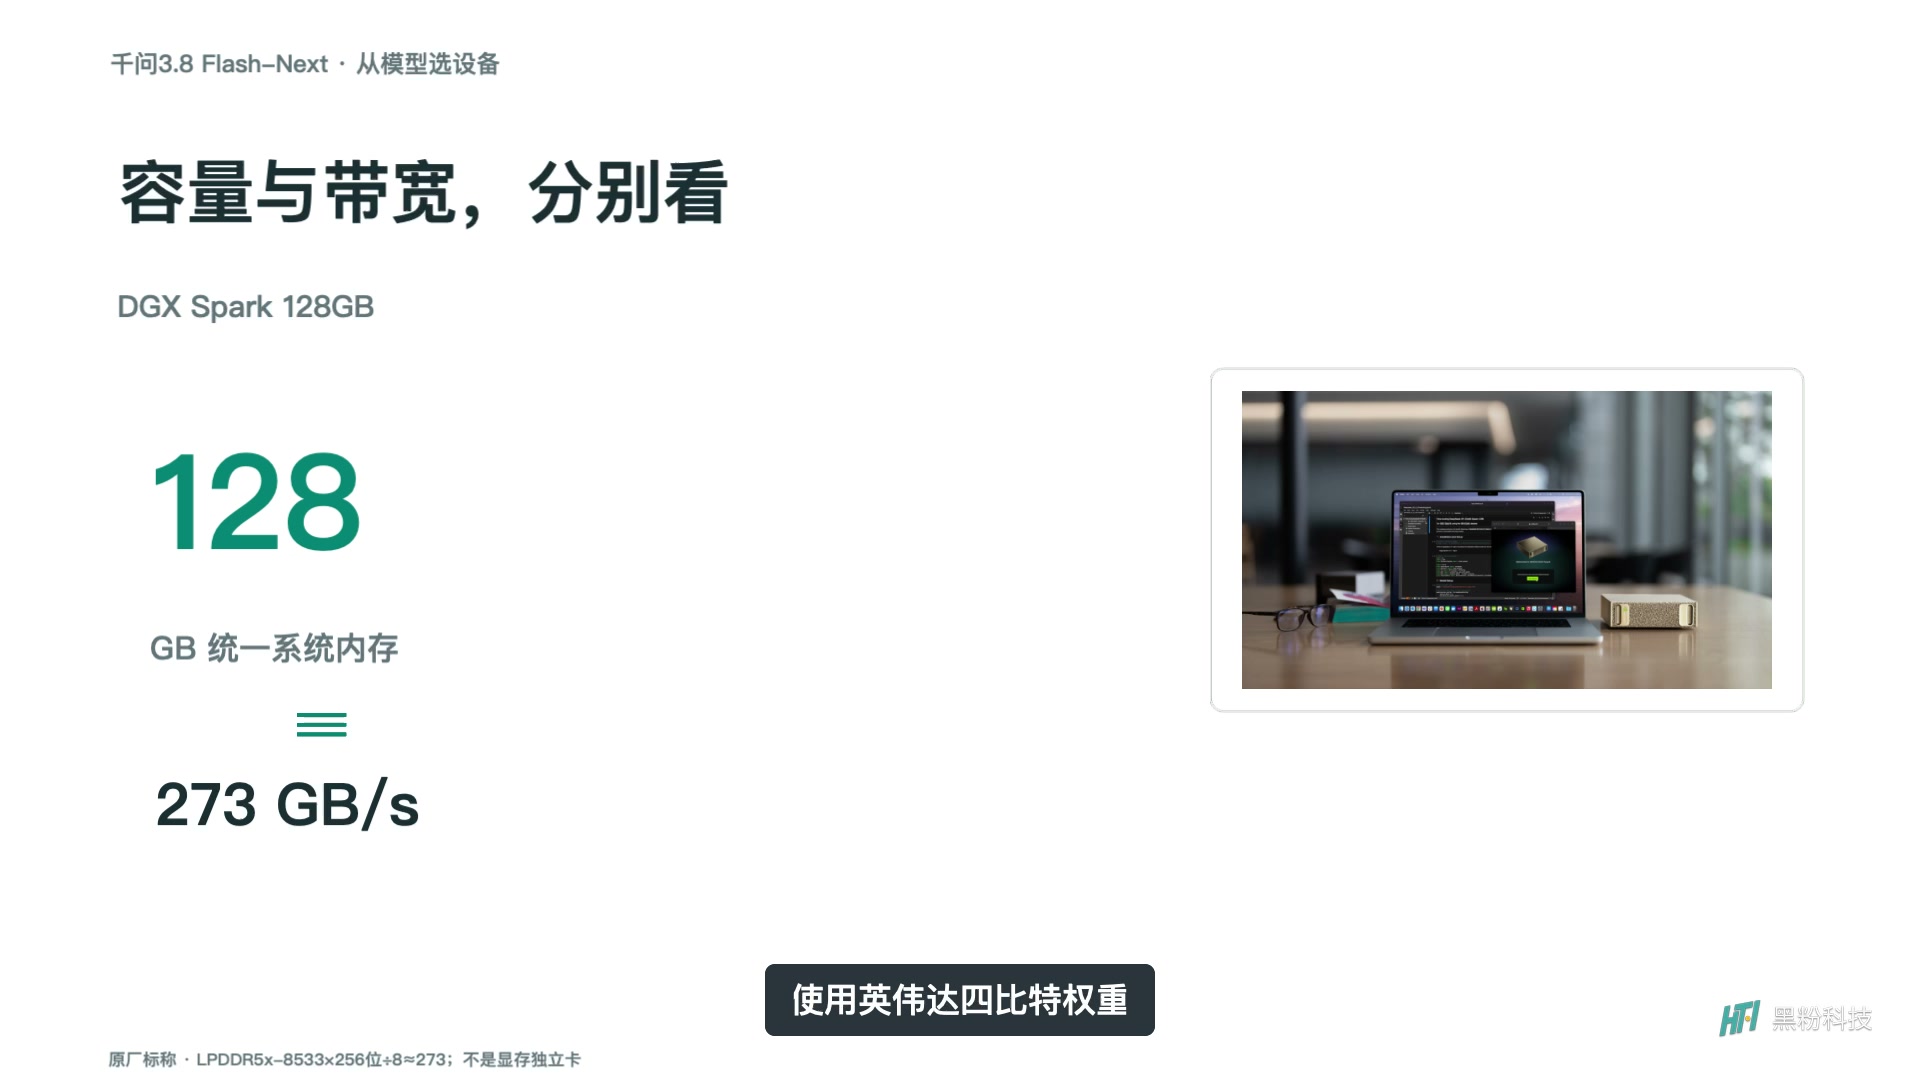
Whole machines like DGX Spark still have value in development environments and existing deployment solutions, but dedicated vLLM routes in the film include weights, mappings, and patch conditions. More expensive builds don’t automatically erase maintenance work; What you buy is a complete route that can consistently complete your tasks.
| Equipment/selected configuration | Capacity | Bandwidth and diameter | Snapshot prices and range |
|---|---|---|---|
| There is already a 128GB desktop | 128GB of system memory | Not verified/configured according to the configuration | 0 yuan · Additional costs for existing equipment |
| There is already the M5 Pro 64GB and Splash | 64GB of unified memory | 307GB/s | 0 yuan · Additional costs for existing equipment |
| Tesla P40 24GB with Strata | 24GB of dedicated video memory | 346GB/s | 1,850 yuan · Bare card |
| RTX 3060 12GB with Strata | 12GB dedicated video memory | 360GB/s | 2,319 yuan · Bare card |
| RTX 5060 Ti 16GB with Strata | 16GB of dedicated video memory | 448GB/s | 7,452 yuan · Bare card |
| EVO-X3 AI Max 395 128GB | 128GB shared system memory | 256GB/s | 21,599 yuan · Complete machine |
| ProArt Creation 13 AI Max 395 128GB | 128GB shared system memory | 256GB/s | 23,499 yuan · Complete machine |
| Mac Studio M5 Max 128GB | 128GB of unified memory | 614GB/s | 40,040 yuan · Complete machine |
| MacBook Pro M5 Max 128GB | 128GB of unified memory | 614GB/s | 51,732 yuan · Complete machine |
| DGX Spark 128GB | 128GB of unified system memory | 273GB/s | 52,734 yuan · Complete machine |
“Existing devices” are charged as additional hardware fees; The bare card route also requires host memory, storage, power supply, and cooling.
Quantization, cropping, draft acceleration, and layered loading—don’t mix them up with ‘super optimization’
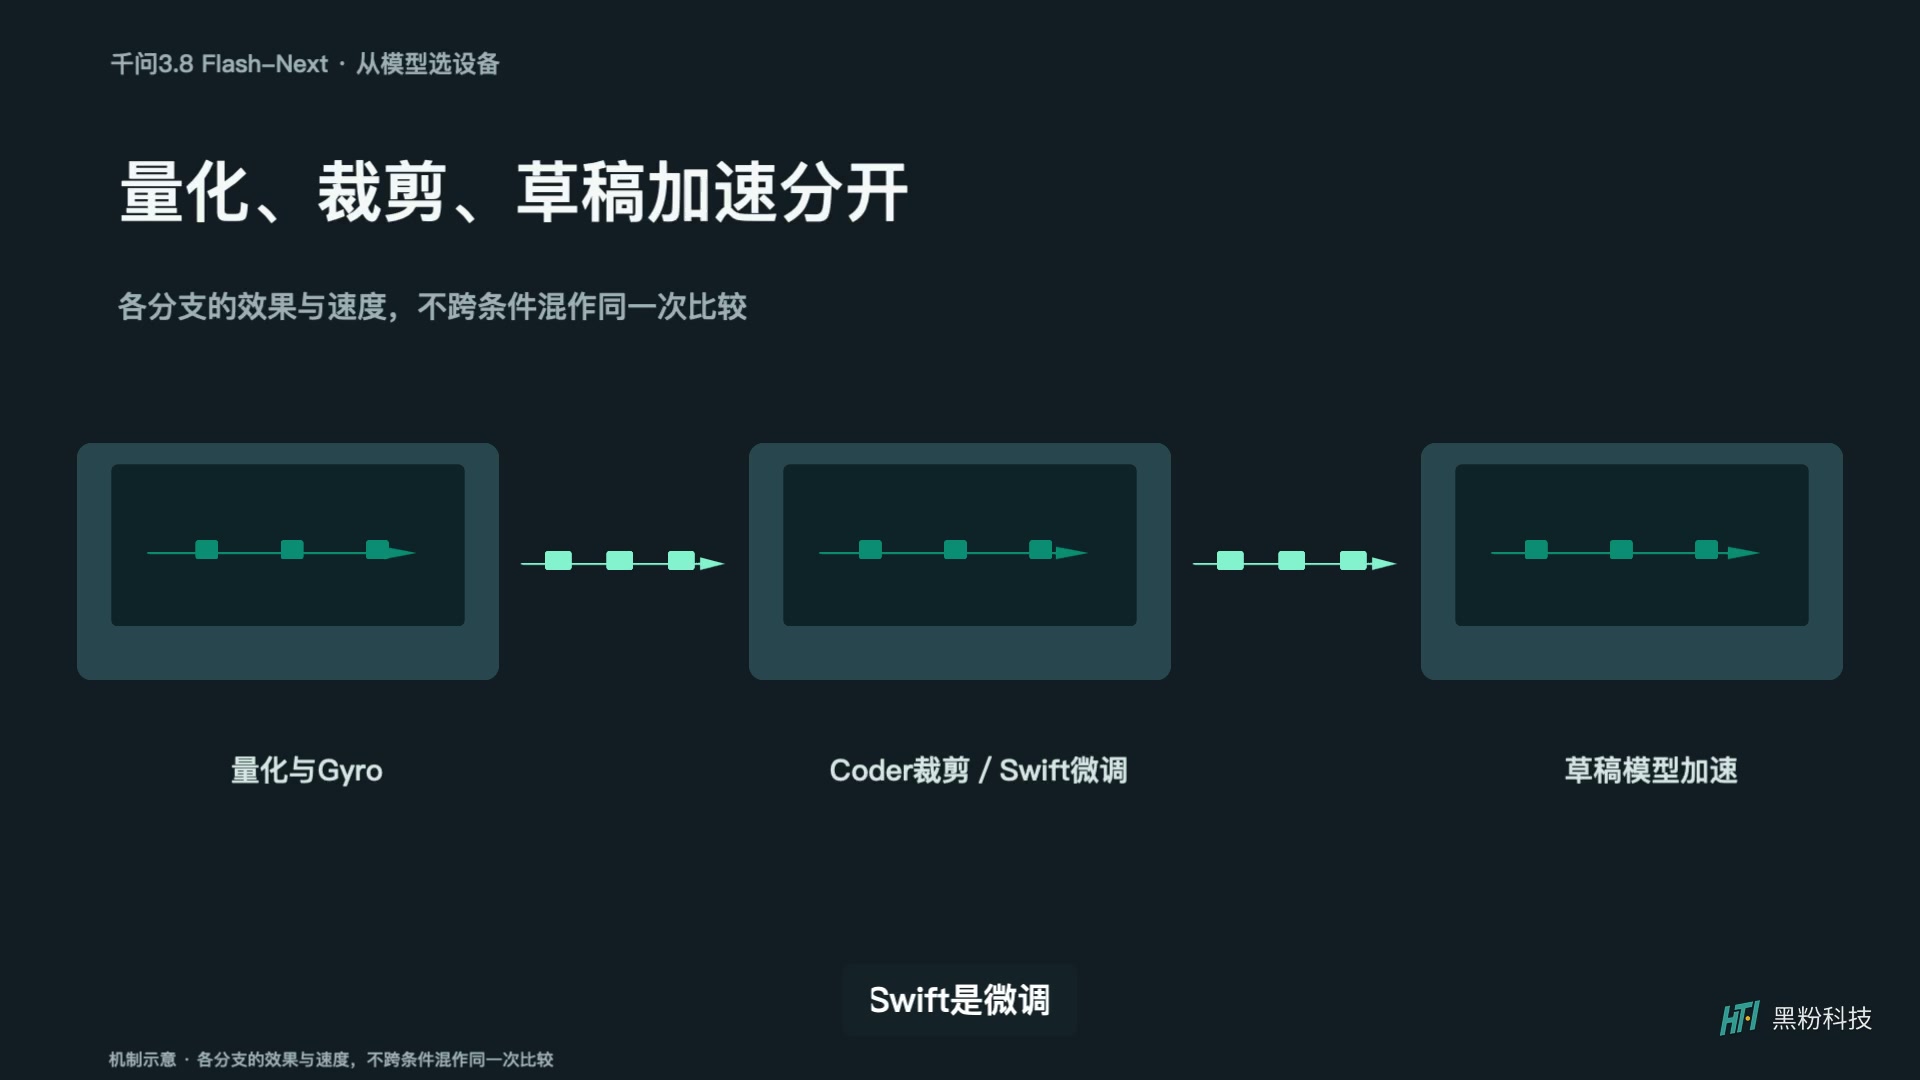
Quantization mainly changes how many bits are used to represent parameters; Clipping changes which parts are retained; Draft acceleration involves guessing and then checking during generation. The film also specifically distinguishes between code-oriented Coder branches and original quantization that retains all experts. Daily Chinese, long texts, and general Q&A cannot be directly copied from the choices in code tasks.
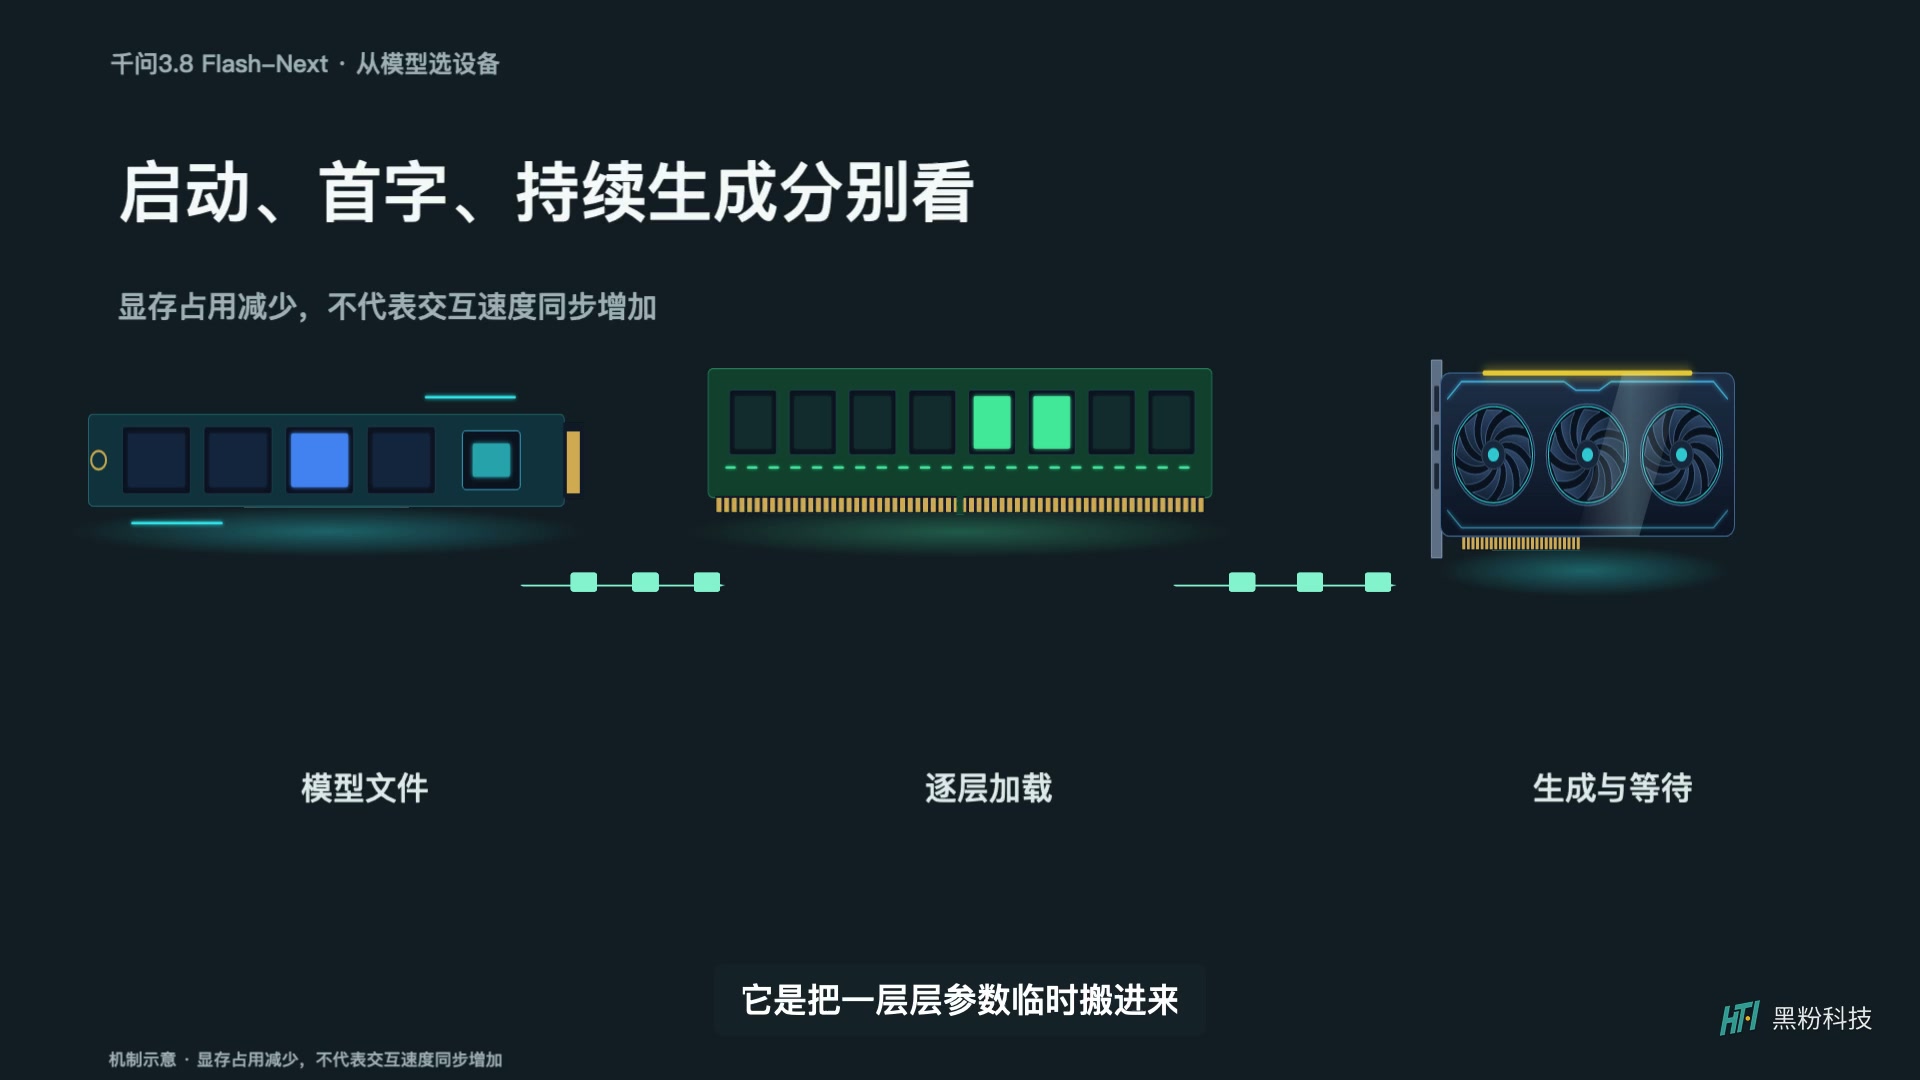
Layered loading is another arrangement: bring in the currently needed layer, then replace it with the next. It has the potential to lower the VRAM threshold, but the cost may come at the cost of hard drive capacity, data transfer, and waiting. The low-memory memory records of AirLLM on the chip are suitable for explaining the “bootable” route; you can’t just look at the memory numbers to infer smooth chats.
This is also the recommended acceptance order: first confirm the model can load, then check how long the first word will take, and finally see if continuous generation and long dialogues are still usable. Recording these three items separately is closer to the experience after buying it than just capturing a peak speed.
No matter how low the budget is, just shrink the model first, not necessarily switch computers first
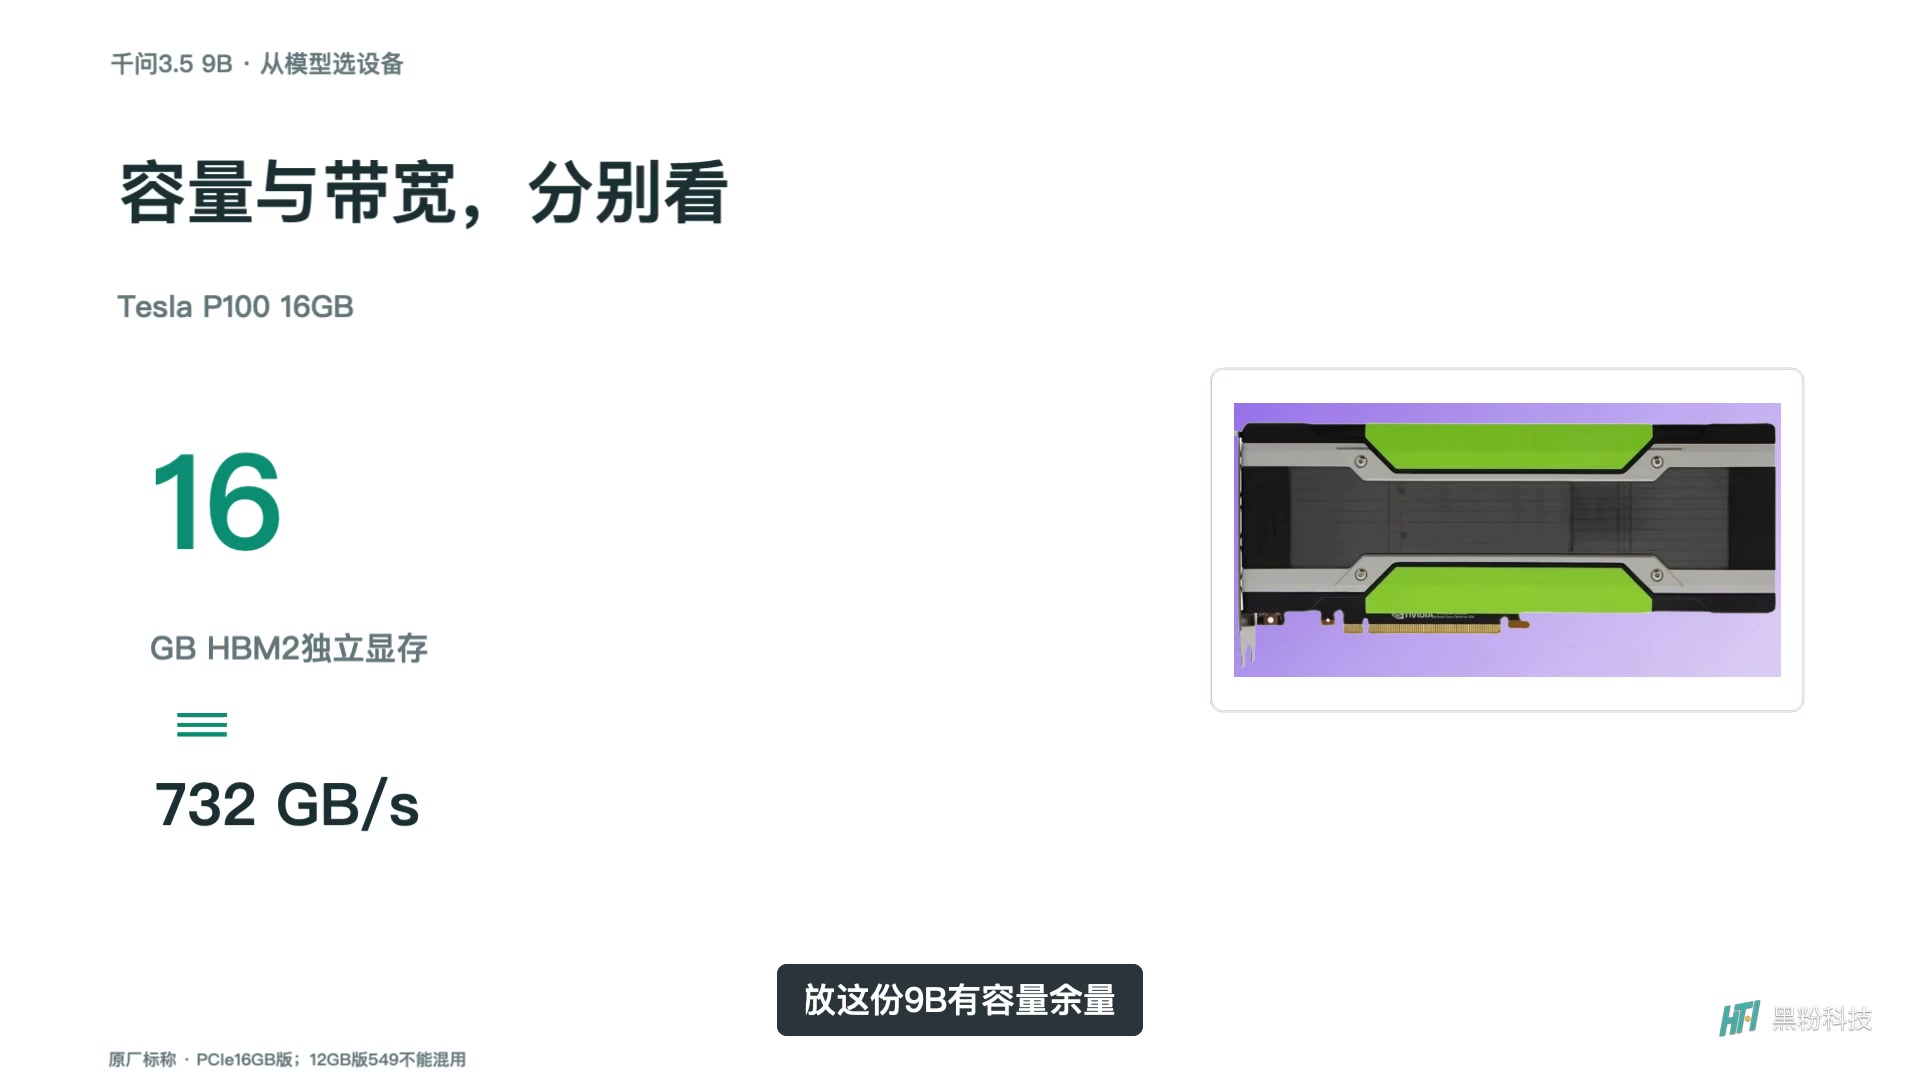
This issue’s Qwen 3.5 9B quad-bit files are about 5.68GB, and 4B is about 2.74GB, approaching the range that more existing devices can try. The P100 sample costs 638 yuan and has 16GB of VRAM, but you still have to handle the driver, power supply, and cooling of retired computing cards yourself. Cheap card prices are not suitable for replacing the overall system cost, nor are they suitable for skipping old hardware status checks.
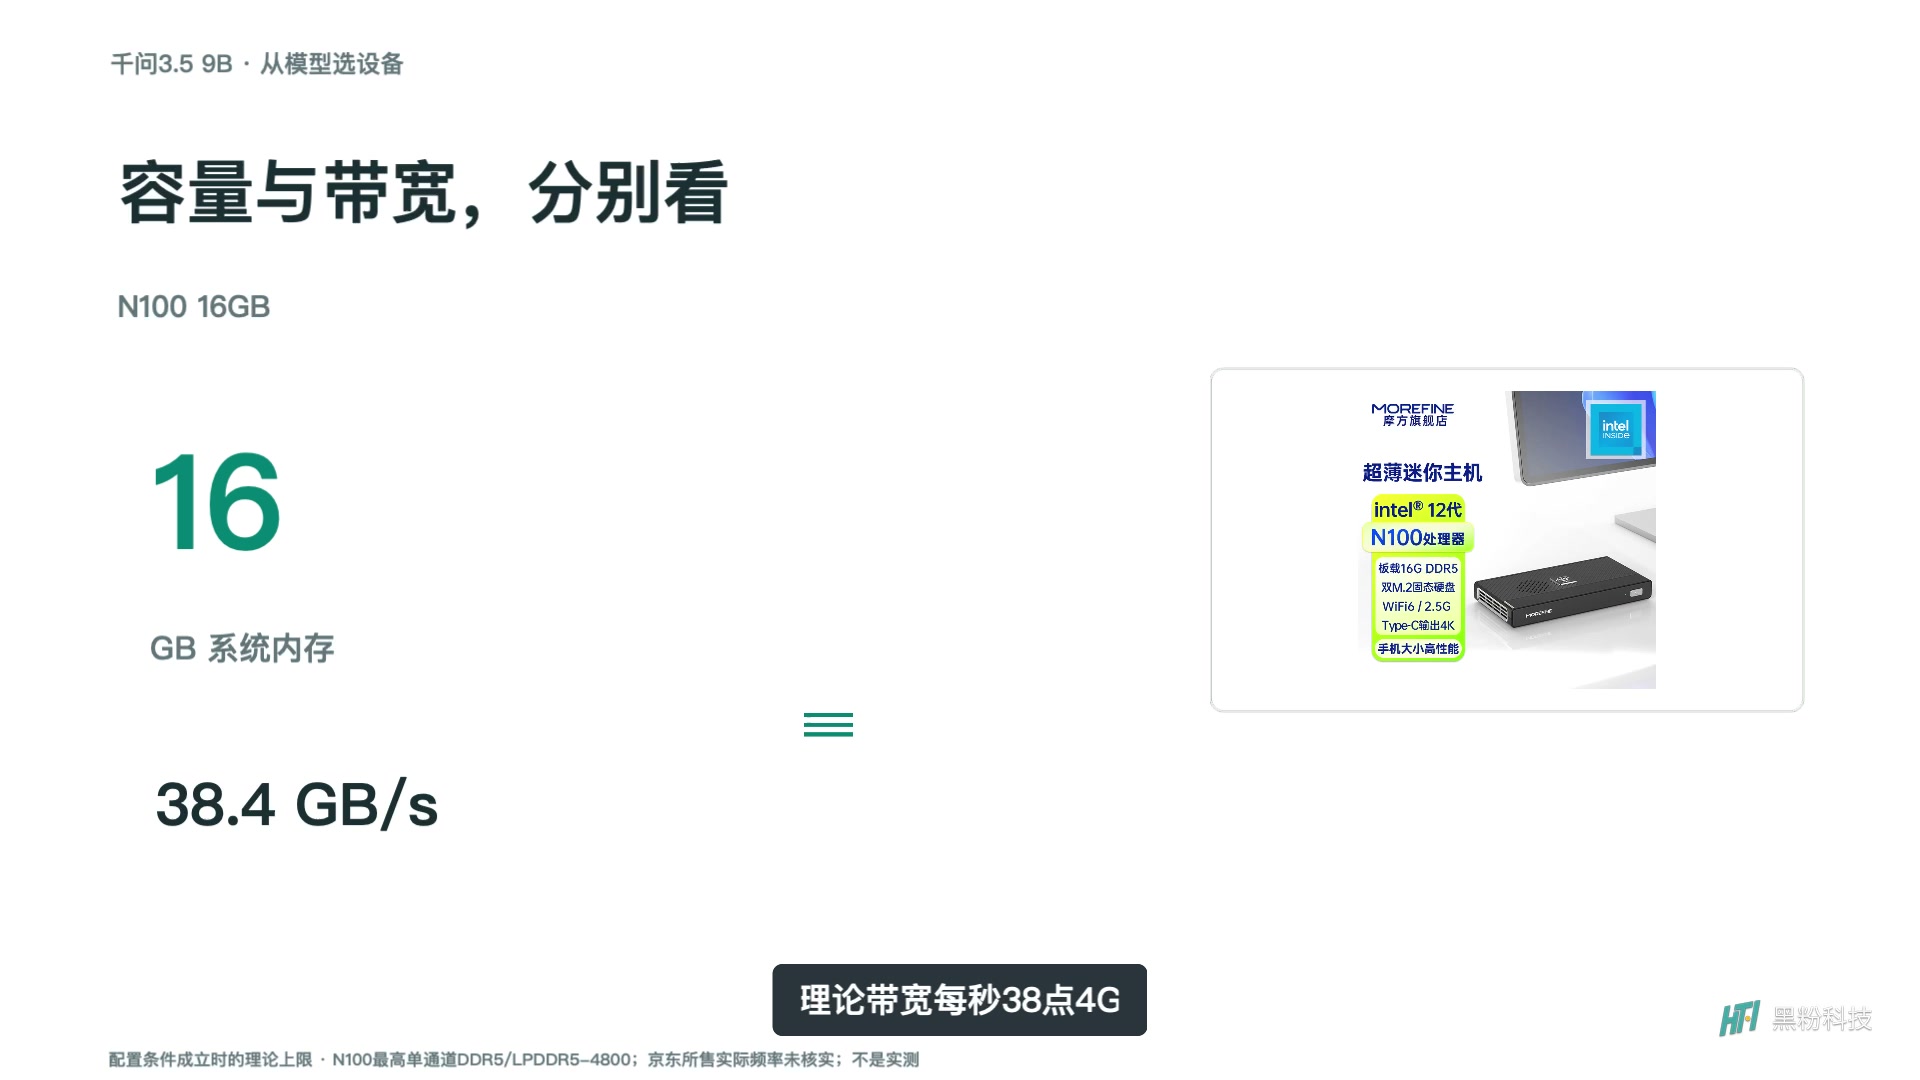
The price of the N100 compact PC is easier to calculate, but memory channels and actual frequency affect the experience. If you’ve been waiting too long for 9B, try 4B first—maybe it’s closer to the ‘use it first’ goal than just increasing your budget.
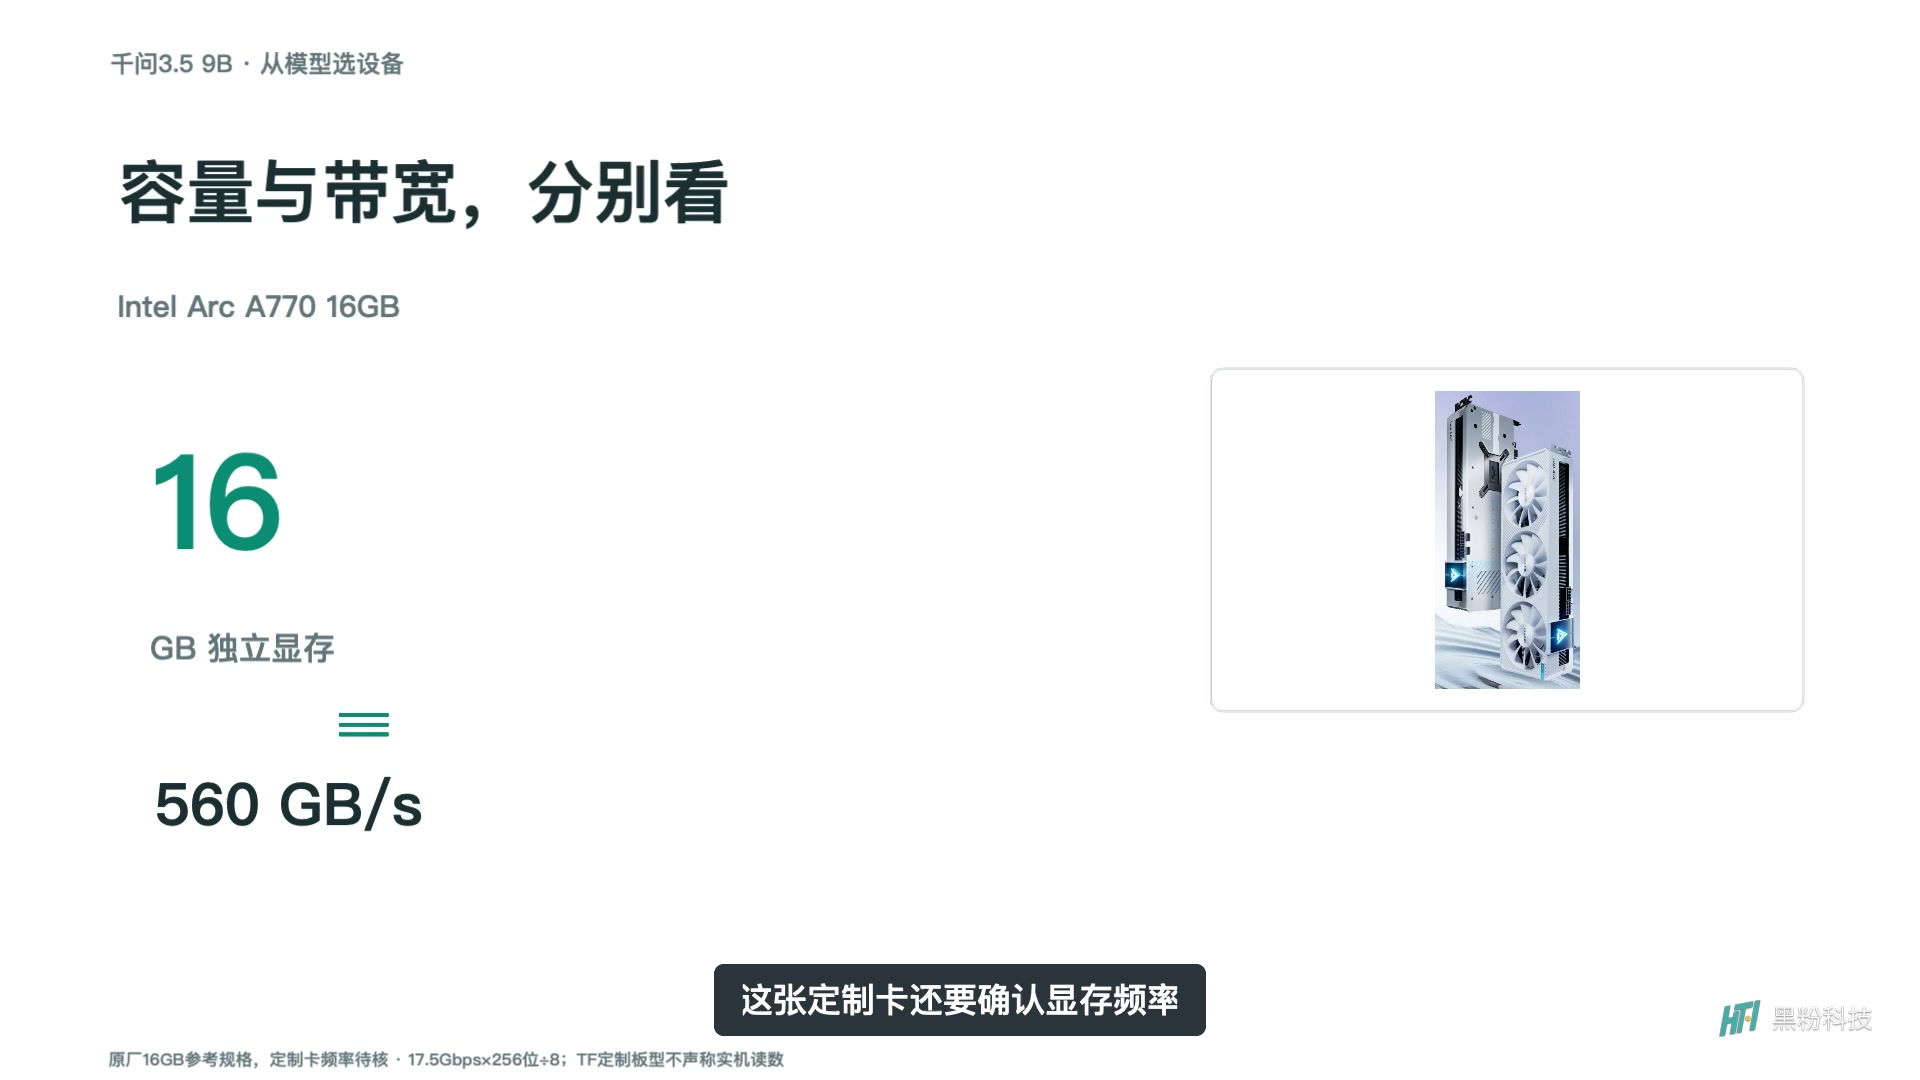
Intel Arc B580, A770, and different generations of graphics cards each have their own capacity and software adaptation preferences. First, confirm the specific backend architecture and model supported by your chosen backend, then look at VRAM, bandwidth, and pricing. You can’t use the results of one platform to guarantee another.
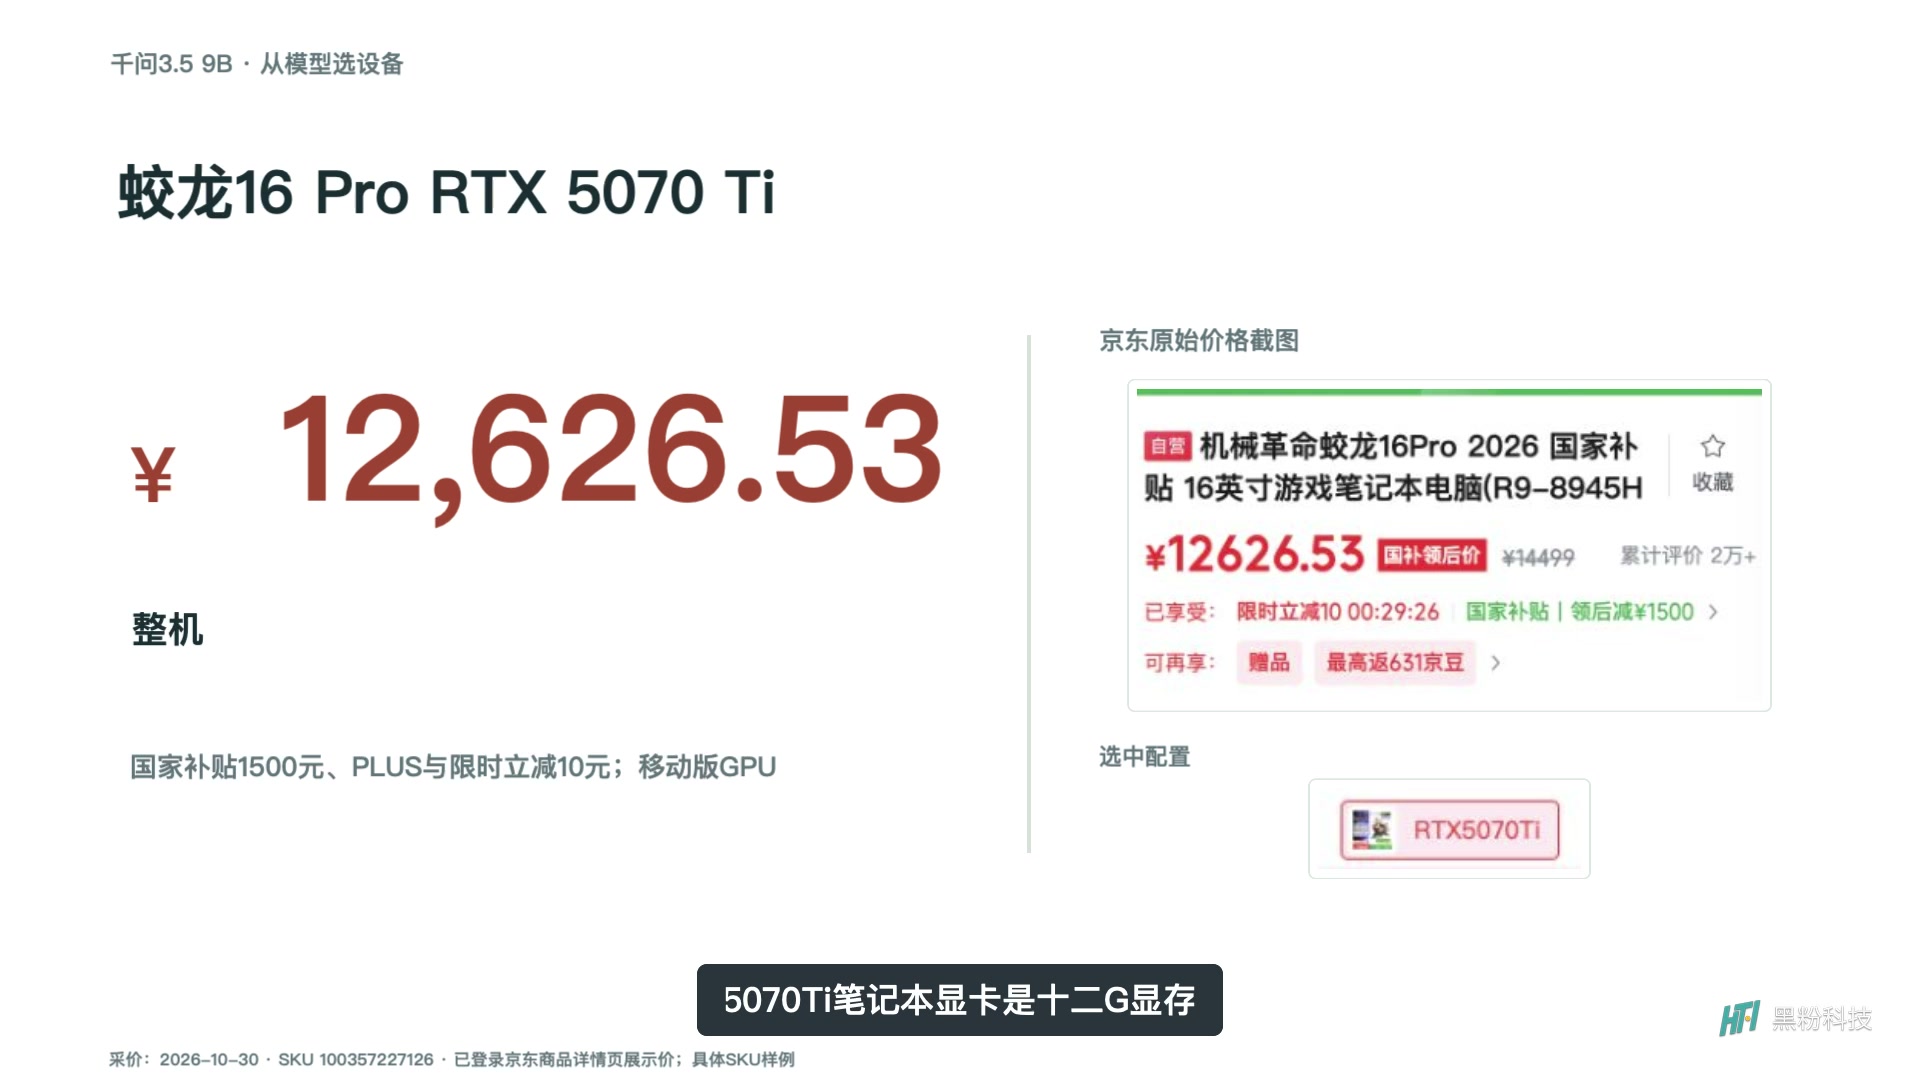
Laptops especially tend to combine two capacities: 32GB of main memory plus 12GB dedicated VRAM, not 44GB of RAM at the same speed. The Jiaolong 16 Pro’s routing in the chip also includes plug-in power, fan, and continuous load; For thin and light Arm laptops, you need to confirm whether the software is actually calling the CPU, GPU, or NPU.
| Equipment/selected configuration | Capacity | Bandwidth and diameter | Snapshot prices and range |
|---|---|---|---|
| Tesla P100 16GB | 16GB of HBM2 dedicated video memory | 732GB/s | 638 yuan · Bare card |
| N100 16GB | 16GB of system memory | 38.4GB/s | 2,069 yuan · Complete machine |
| Intel Arc B580 12GB | 12GB dedicated video memory | 456GB/s | 3,199 yuan · Bare card |
| Intel Arc A770 16GB | 16GB of dedicated video memory | 560GB/s | 3,369 yuan · Bare card |
| RTX 4060 Ti 16GB | 16GB of dedicated video memory | 288GB/s | 4,599 yuan · Bare card |
| HP Zhan 66 H255 16GB | 16GB of system memory | Not verified/configured according to the configuration | 4,811 yuan · Complete machine |
| RX 9070 XT 16GB | 16GB of dedicated video memory | 640GB/s | 7,506 yuan · Bare card |
| ASUS Zenbook 14 Air X2 Elite 32GB | 32GB of shared system memory | 152GB/s | 11,424 yuan · Complete machine |
| Jiaolong 16 Pro RTX 5070 Ti | 12GB dedicated video memory; and an additional 32GB system memory | 672GB/s | 12,627 yuan · Complete machine |
| MI50 32GB is a supplementary candidate | 32GB of HBM2 dedicated video memory | 1000GB/s | Accurate quotation not obtained · Accurate price not found |
For old cards and third-party custom boards, condition, frequency, warranty, drive, and heat dissipation should be separately verified; Candidates without accurate quotations will not be remanufactured at price.
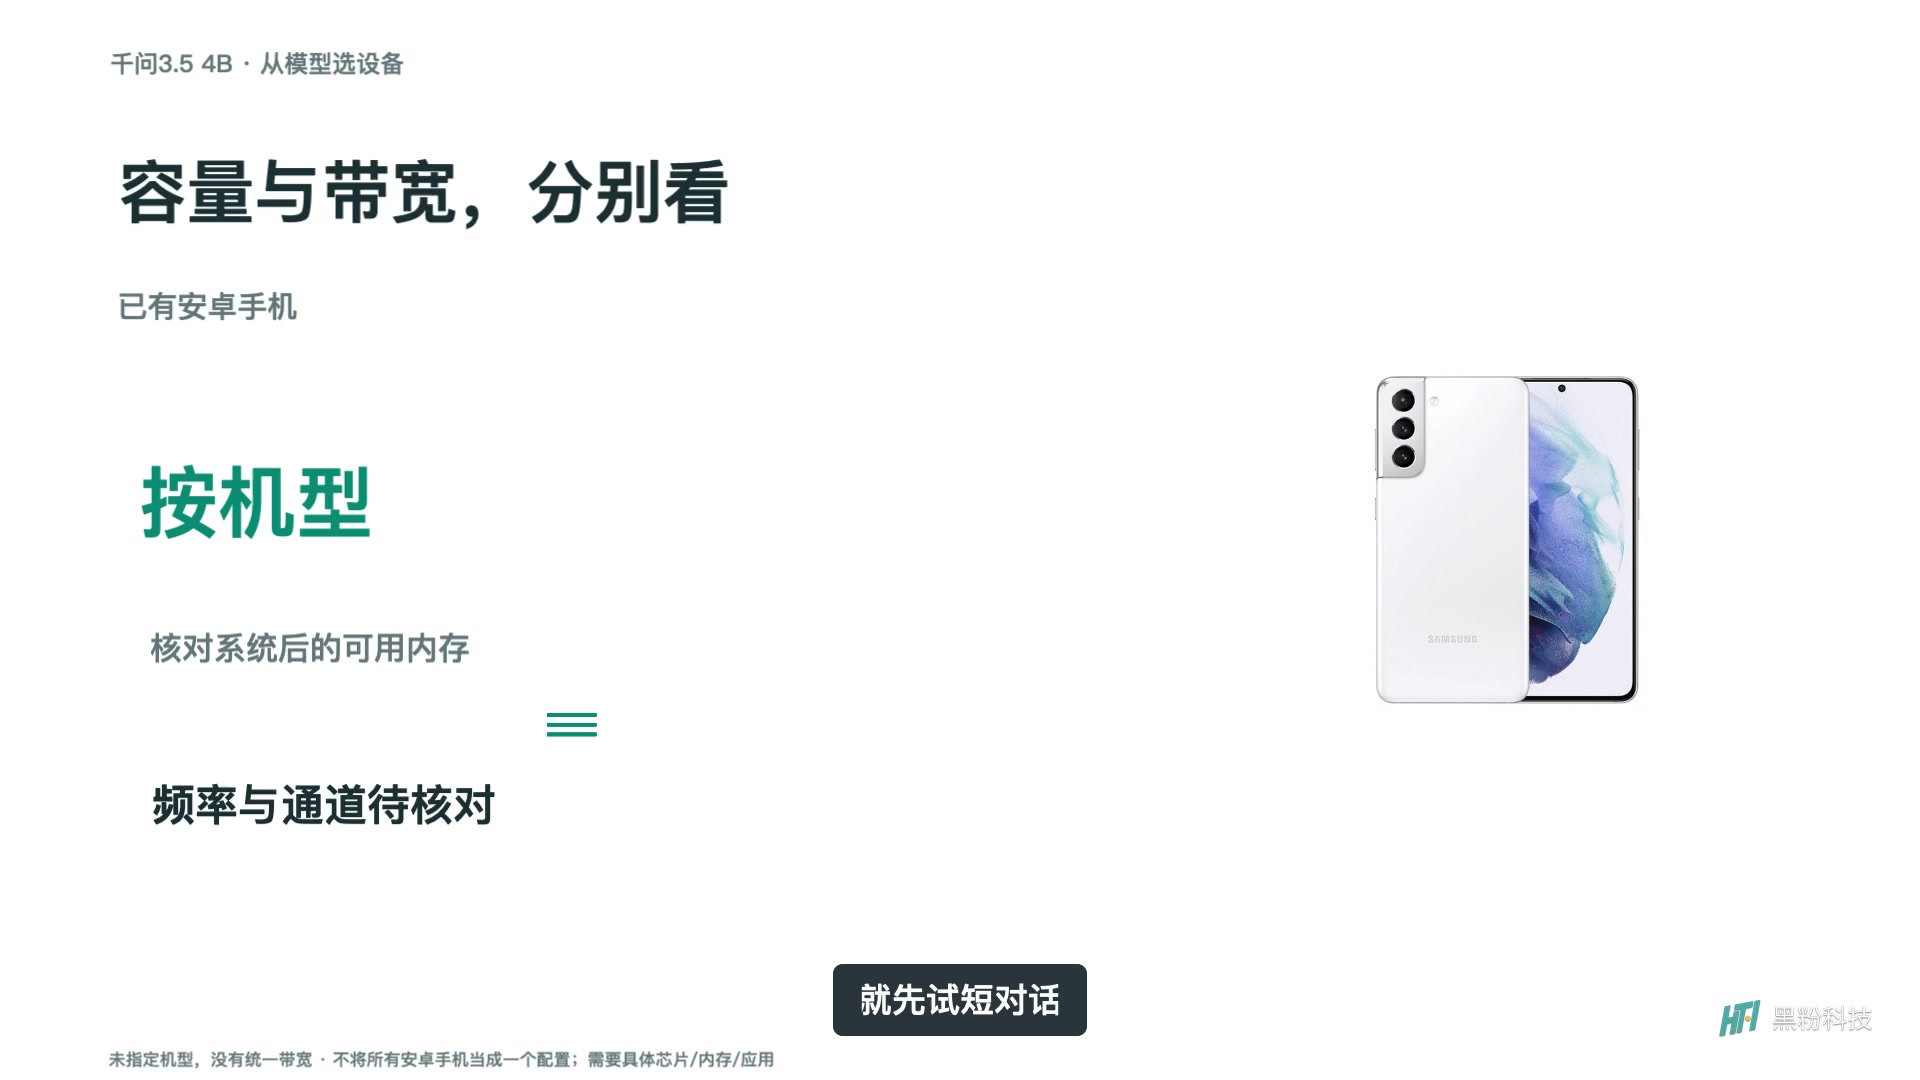
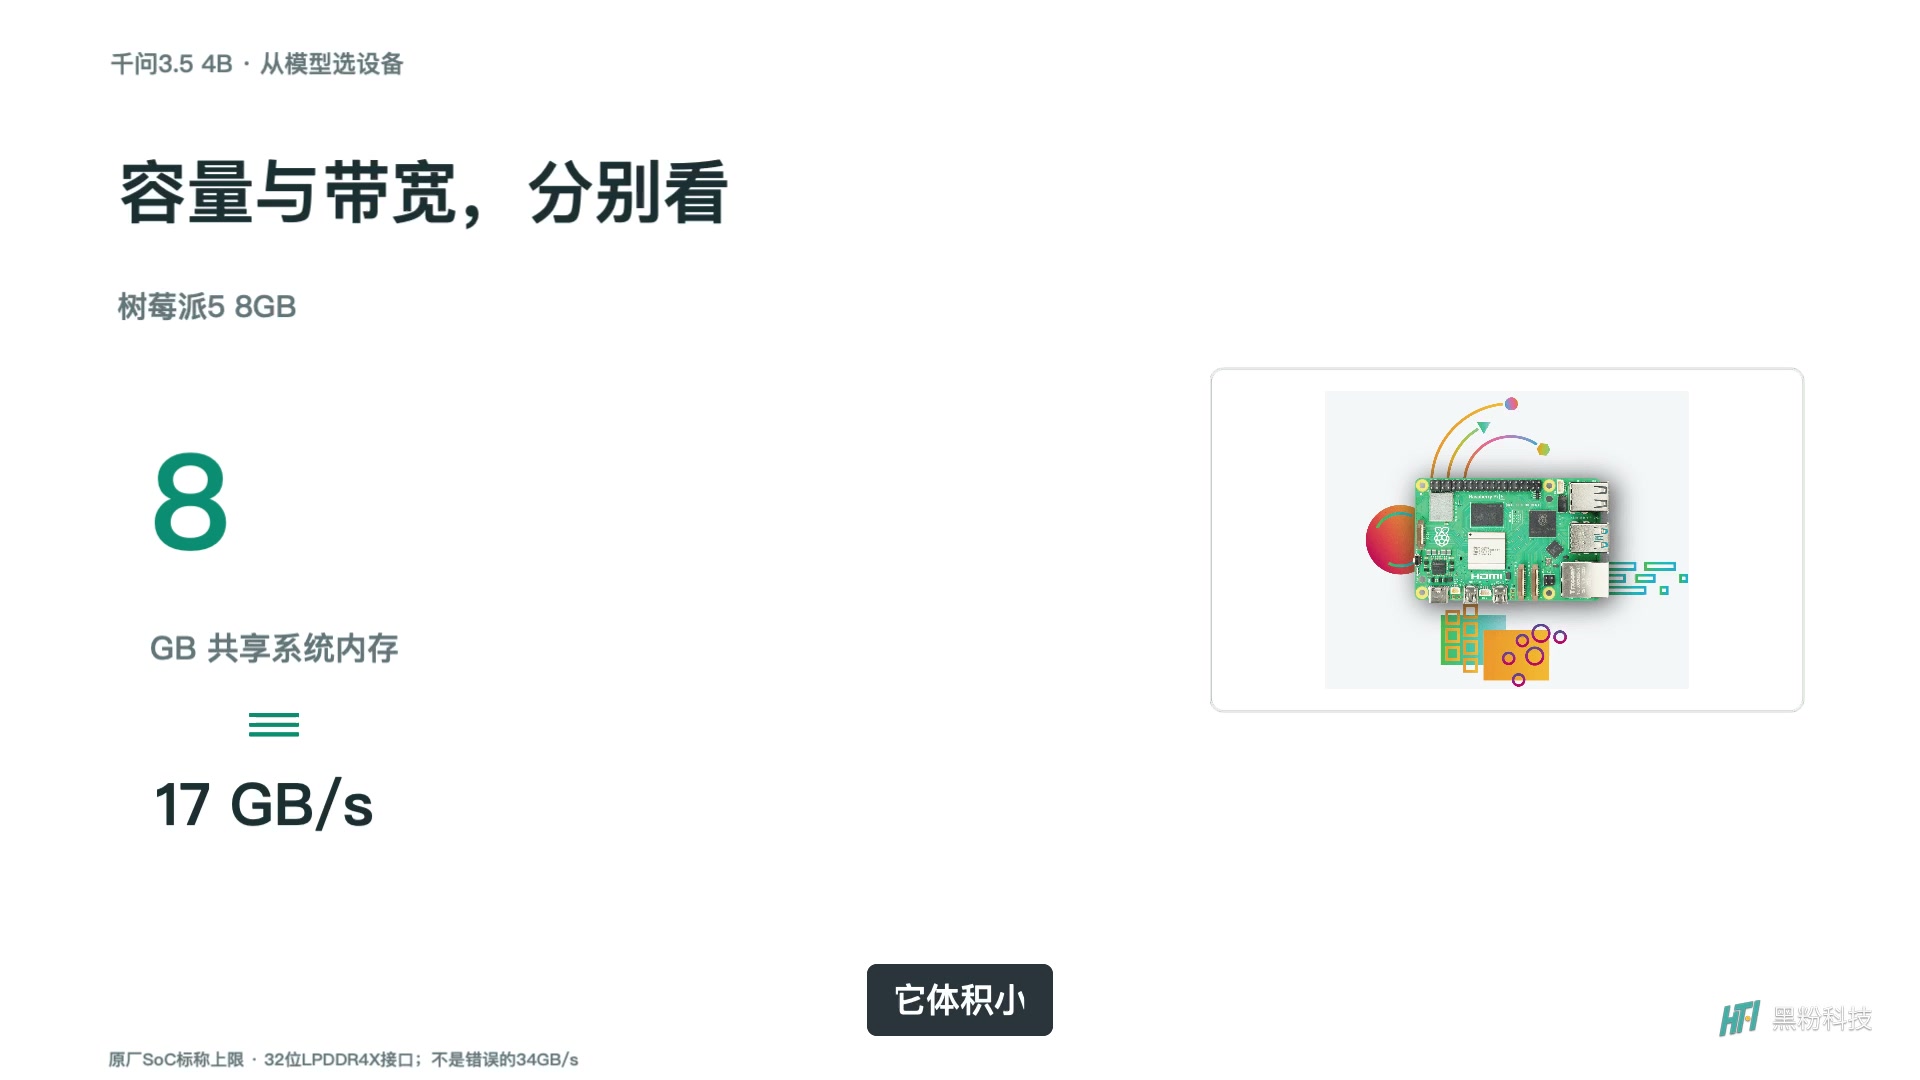
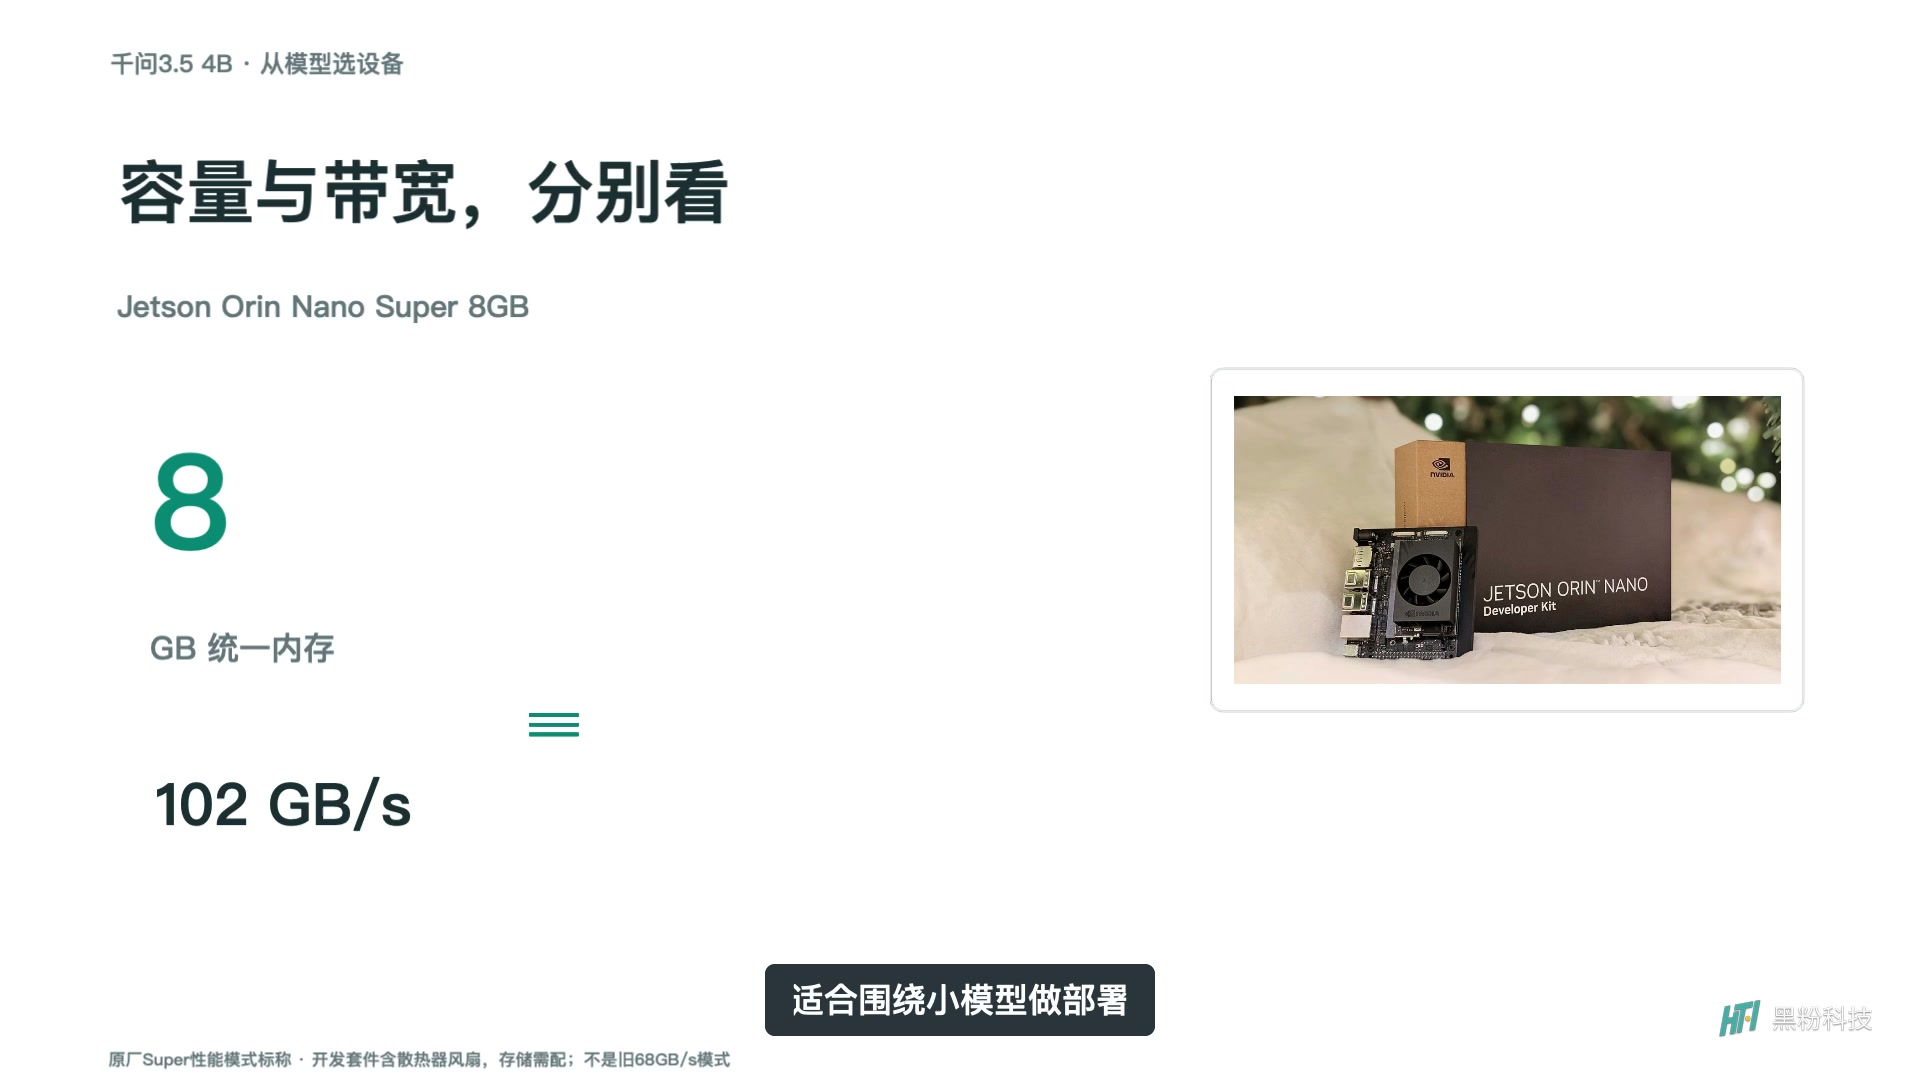
If you already have an Android phone, you can first try short conversations with compatible apps and suitable small models; Raspberry Pi and Jetson are suitable for learning, edge deployment, and project purposes. The power package price of the former does not include all storage and chassis, while the latter requires choosing the right software and performance mode. Buying a development board from scratch for experience chat may not be more suitable than using an existing computer first.
| Equipment/selected configuration | Capacity | Bandwidth and diameter | Snapshot prices and range |
|---|---|---|---|
| Android phones are already available | According to the specific model | Not verified/configured according to the configuration | 0 yuan · Additional costs for existing equipment |
| Raspberry Pi 5 8GB | 8GB shared system memory | 17GB/s | 1,839 yuan · Development board power package |
| Jetson Orin Nano Super 8GB | 8GB of unified memory | 102GB/s | 3,969 yuan · Development kit |
Mobile phones are charged based on additional costs for existing devices; Development board packages and supporting scope are subject to the snapshot records.
Before placing an order, write out the configuration instructions in full
First, write the exact file name and quantized version of the target model, then specify the engine used, required context, and an acceptable wait. Next, check the overall system memory, video memory, hard drive, power supply, cooling, and platform support, and finally use the current product page to confirm SKUs and final prices. If you can borrow or already have equipment, try out your real task first.
If the main needs are just short conversations and light tasks, and the small model can be completed, there’s no need to buy a new computer for a larger specification. If you really want to run a larger model long-term, then see if the dedicated deployment plan can be replicated and whether maintenance is willing to take responsibility. What really needs to be compared is the cost of the entire available solution, not the name of a single graphics card. Personal opinion, for reference only.
Self-made software
Versions, changes and supported installers all come from the same public release records.
HyphenAssistant
Continue your computer’s DeepSeek Harness session from a phone browser. The service, computer and network must stay online; model costs follow your existing setup.
View public downloads and updates ↗LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗ScreenLex
Turn subtitles from your own films and shows into an English vocabulary library, entirely offline.
View public downloads and updates ↗HyphenScreen
Screen recording and editing with a Resolve-style timeline, automatic redaction and pre-export checks.
View public downloads and updates ↗Support HyphenTech
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Save the QR codeScan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

WeChat tips · Any amount welcome



Comments
Loading comments…