
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
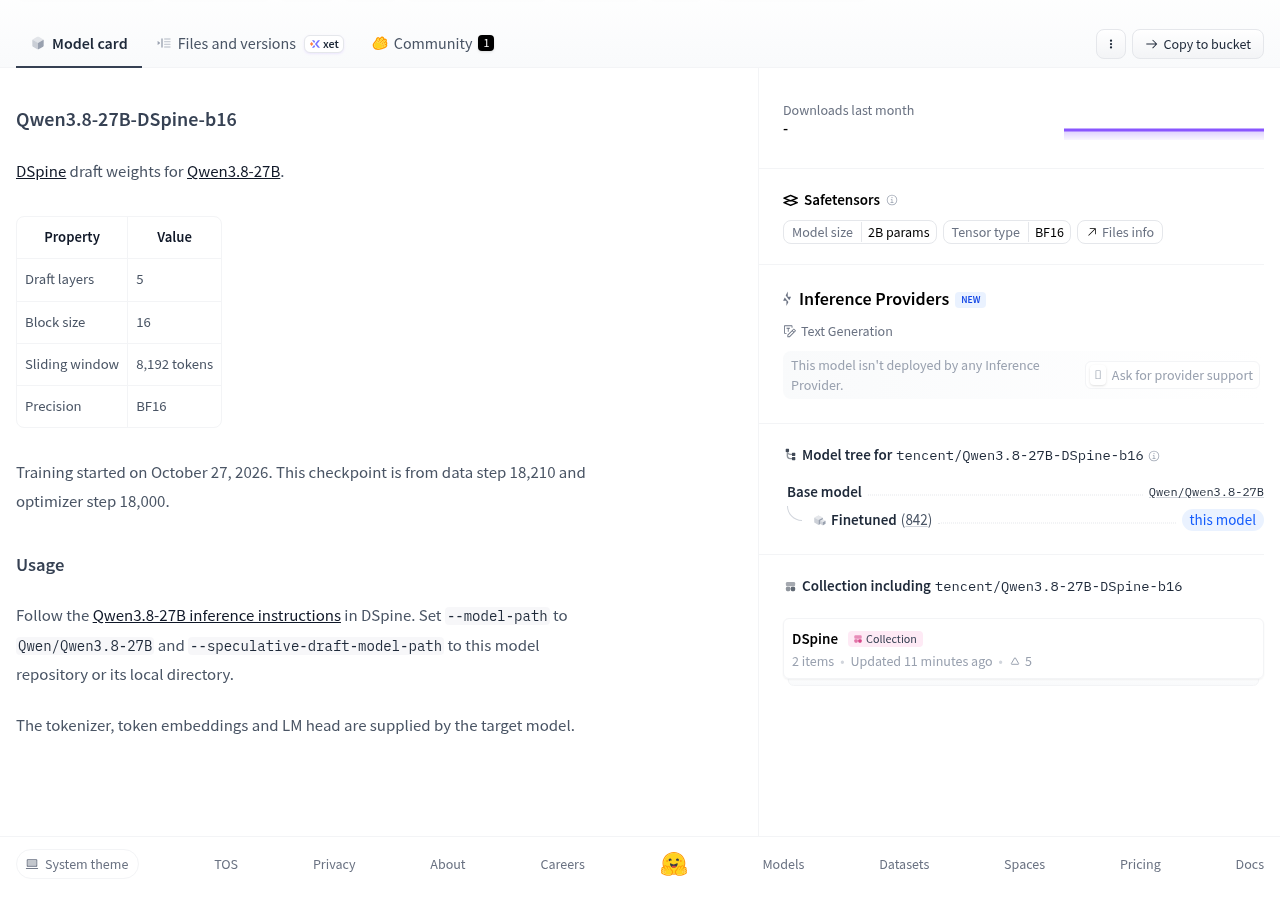
When you see Qwen3.8-27B-DSpine-b16 under Tencent accounts, don’t treat it as a small model that can chat independently after downloading. The official model card lists it as the DSpine draft weight for Qwen3.8-27B, and the instructions also require specifying both the target model and the draft model. It’s more suitable for those who are already preparing to use the target model and want to further research supporting reasoning workflows.
The page is marked with two billion parameters, so why need another model?
The model size bar on the page is marked as 2B, which means two billion parameters. But this number describes the current model scale of the repository and cannot be used as the scale of the entire running scheme. The official statement clearly states that the segmentation, lexical embedding, and language model output headers are provided by the target model.
These dependencies can be understood through express parcel pickup: the word splitter breaks down inputs into system-processable numbers, such as organizing express information into verifiable pickup records; Word embedding converts numbers into representations used by model calculations, such as finding corresponding locations based on records; Output headers then map internal calculation results back to candidate terms, like remapping locations to packages that can be delivered to recipients. This is just an analogy of functional relationships. The fact that affects usage choice here is: these components need to be provided by the target model, and the current warehouse does not come with a complete set.
Therefore, those looking for an independent chat model should not add it to their download list just by looking at 2 billion parameters. For those already researching Qwen 3.8-27B inference, this draft weight is worth further reviewing; What needs to be verified is whether the entire set of coordination works, not just how large the draft file is.
The entry point is a supporting reasoning process, not a ready-made chat service
Official usage points to Qwen3.8-27B in DSpine Inference explanation: Set the target model path to Qwen/Qwen3.8-27B, and set the draft model path to the current repository or its local directory. In other words, the configuration must clearly distinguish between two roles; you cannot directly fill the draft repository into the target model’s location, assuming the deployment is complete.
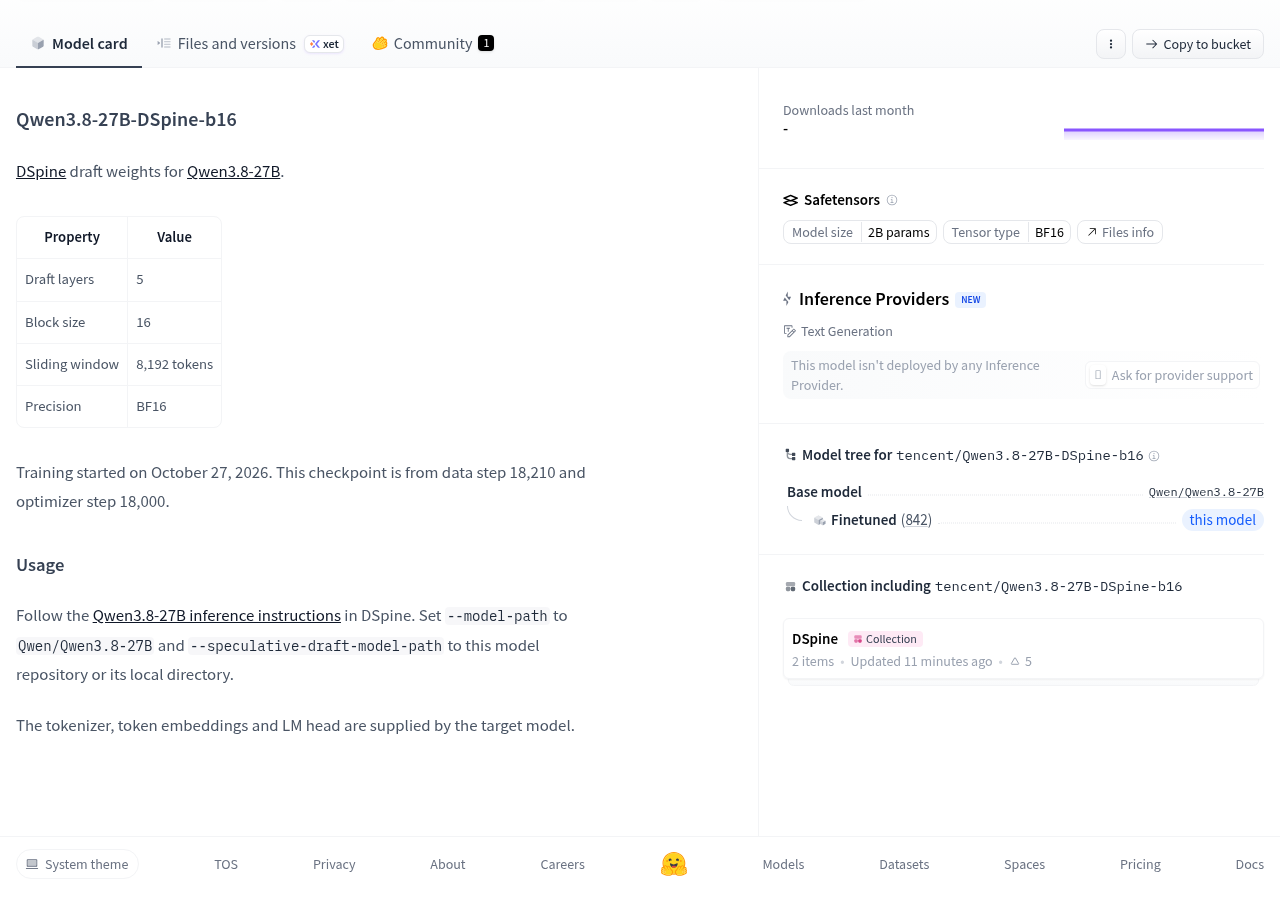
The name B16 should not be confused with precision. The model card lists block size 16 and precision BF16; They are different configuration items. The official page does not provide acceleration scores for this draft weight, memory requirements, or specific device adaptation results, so it cannot be used to determine whether a regular computer is usable, nor can it guarantee that replacing it will be faster.
If you want to experience it directly through an online portal without deploying, the page also does not provide a ready-made answer: during data collection, the managed inference area clearly shows that no inference service provider has deployed this model. This describes the service status listed on the page and does not mean that services must not exist on other channels.
What is worth doing now is to verify the entire chain rather than rushing to download
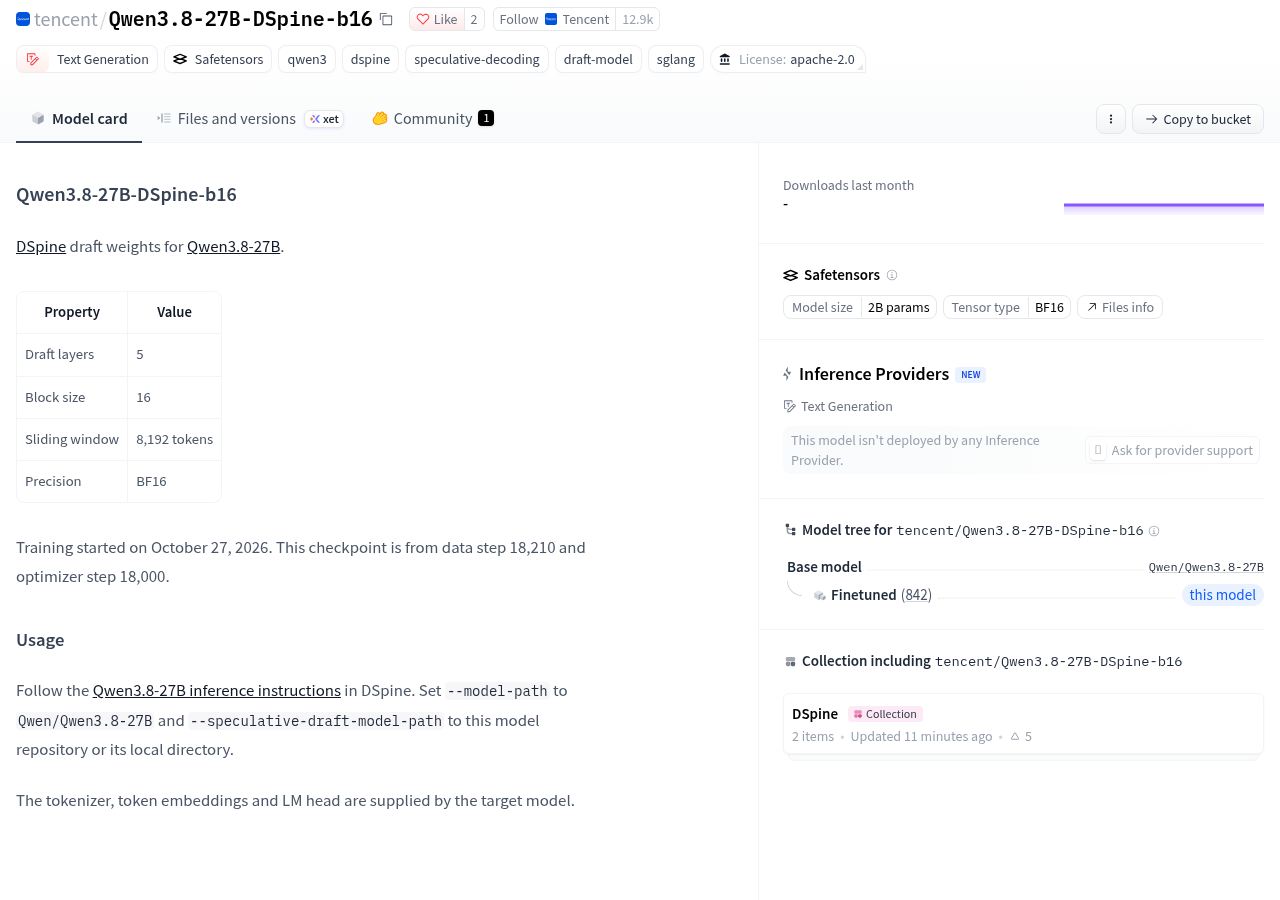
What can be confirmed is that a model card has appeared under the Tencent account, explaining the purpose, configuration, and supporting entry points for draft weights. The page also states that training will start on October 27, 2026, but this is the training date, not the release date. The materials do not specify an official release date, nor do they provide a file list or actual download verification, so the appearance of the model card cannot be directly written as the weight verified and downloadable.
- Just want to chat directly: first choose a target model with a complete usage point, and don’t treat this draft weight as an independent substitute.
- Preparation for research supporting reasoning: From the usage instructions of the model card into DSpine, continue verifying the loading methods, runtime support, and hardware requirements between the target model and the draft model.
- Prepare for download or use in the project: separately confirm whether the weight files are actually obtainable, as well as the licenses for the target model, draft weight, and runtime code; Existing materials do not provide a complete license conclusion.
- Prepare to decide if it’s worth adopting: After successful loading, use your actual task to record output, time consumption, and resource usage, then decide whether to keep this setup; Currently, there are no official performance scores available for reference.
Next, you can check the official model card and usage instructions. After confirming the target model, draft weights, runtime environment, and permissions item by item, proceed to deployment. For those who only need an immediately usable chat portal, this repository is not currently the preferred choice; For those studying the target model inference process, it is a supporting resource that needs further verification.
Official information
Self-made software
Versions, changes and supported installers all come from the same public release records.
HyphenAssistant
Continue your computer’s DeepSeek Harness session from a phone browser. The service, computer and network must stay online; model costs follow your existing setup.
View public downloads and updates ↗LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗ScreenLex
Turn subtitles from your own films and shows into an English vocabulary library, entirely offline.
View public downloads and updates ↗HyphenScreen
Screen recording and editing with a Resolve-style timeline, automatic redaction and pre-export checks.
View public downloads and updates ↗Support HyphenTech
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Save the QR codeScan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

WeChat tips · Any amount welcome



Comments
Loading comments…