
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
The chat assistant remembers your preferences—the challenge isn’t just “saving” it, but deciding which information is worth keeping, how to write accurately, and how to update old records when new information appears. Tencent Hunyuan’s Hy-Memory-30B-A3B specifically handles this “writing to long-term memory” path.
It’s not a complete chat model, but rather a ‘writer’ within the memory system.
The official definition of Hy-Memory-30B-A3B is a compact long-term memory writing model, with about 3B activation parameters. It can replace the general large models originally responsible for writing within Mem0, MemOS, and Hy-Memory, covering chat, work, and programming scenarios.
You can think of the external memory framework as a courier warehouse: dialogue is for packages that keep coming in, the memory library is the shelf, and the writing model determines which packages should be stored, how to write labels, and whether to replace or supplement the same item after a new version. The Hy-Memory-30B-A3B handles this step, not the entire process of searching, answering, and applying alone.
The 30B in the name corresponds to the parameter scale listed on the model page, and in practice, about 3B parameters are activated per input process. It is more like a warehouse with many shelves, each time only the relevant area is mobilized; This shows that the model adopts a sparse activation approach but cannot directly output speed, memory usage, or runtime on a computer.
What do official results say?
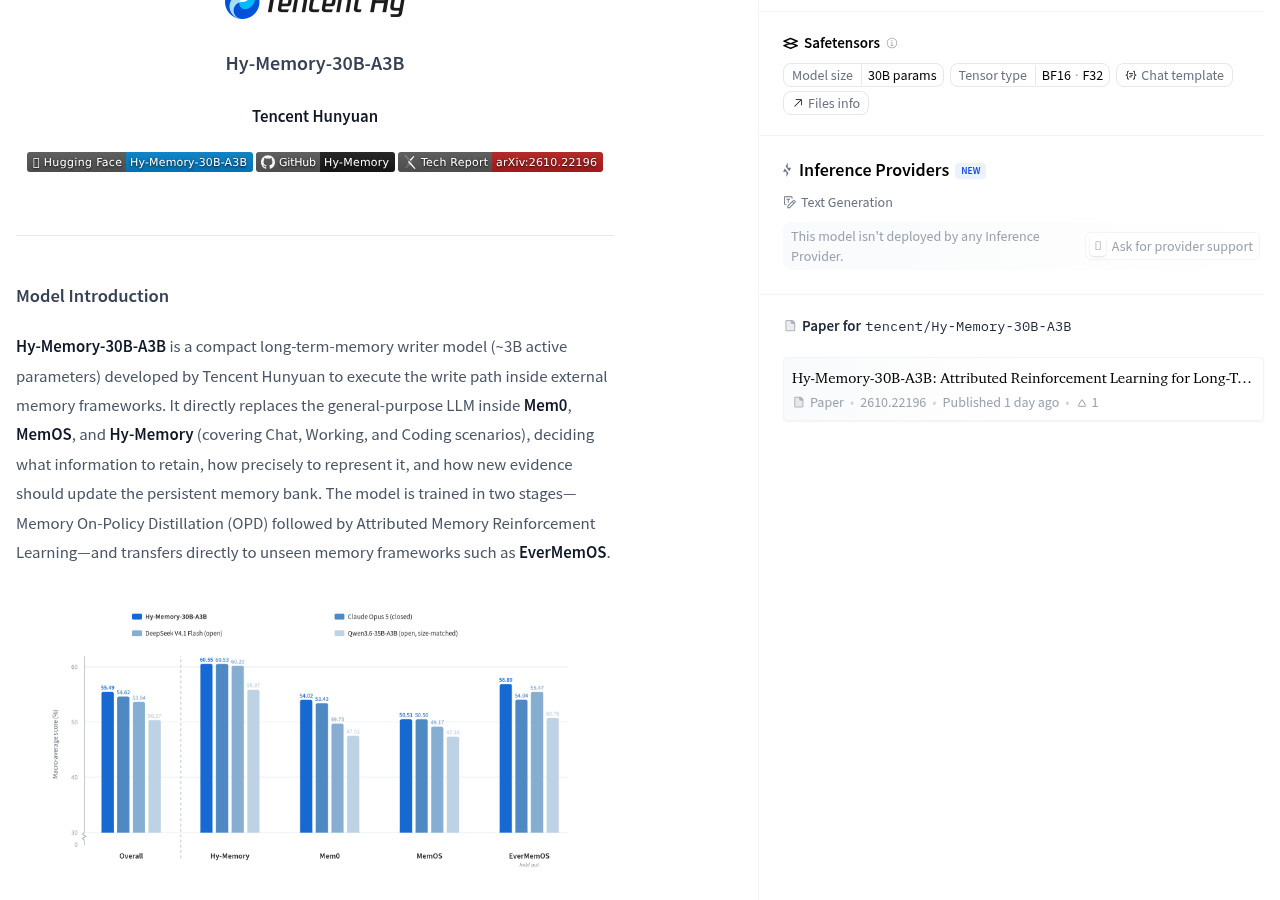
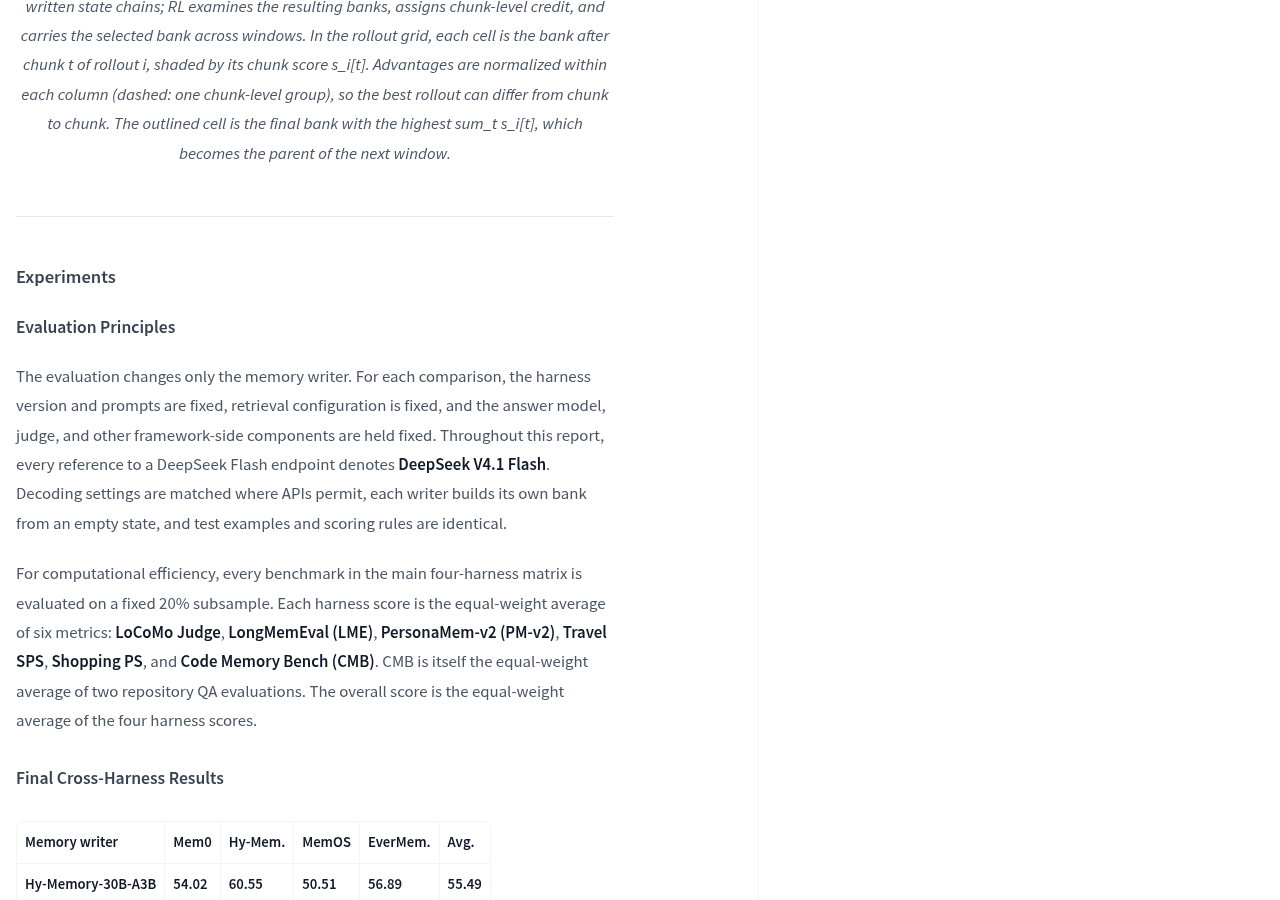
This evaluation only replaced the memory writing model. Officially, each group maintained the framework version, prompts, retrieval configuration, response model, judge model, and other framework components unchanged; Each write model built its own memory bank from a blank state, with test samples following the same scoring rules. The main evaluation used a fixed 20% subsample.
| Officially listed memory writing models | Mem0 | Hy-Memory | MemOS | EverMemOS | Overall scores |
|---|---|---|---|---|---|
| Hy-Memory-30B-A3B | 54.02 | 60.55 | 50.51 | 56.89 | 55.49 |
| Claude Opus 5 | 53.43 | 60.53 | 50.50 | 54.04 | 54.62 |
| DeepSeek V4.1 Flash | 49.73 | 60.20 | 49.17 | 55.47 | 53.64 |
Official fixed 20% of subsample results; Each framework score is averaged equally weighted by six indicators, and the composite score is then averaged equally weighted across four frames.
These numbers support a limited conclusion: in the official fixed conditions and sampling matrix, the Hy-Memory-30B-A3B scored 55.49 in combination. They are not independent retests, nor do they prove that the same results are maintained after switching to a different set of prompts, search engines, response models, or real user data.
What’s even more worth watching is how it learns to update its memory
The official approach is two-stage training: first, Memory On-Policy Distillation, where the student model learns the state chain provided by the instructor; Then, Attributed Memory Reinforcement Learning, which allocate block-level feedback based on the formed memory bank and bring the selected memory into subsequent windows.
It’s like organizing WeChat chat records: first learn how to write scattered messages into clear memos, then judge which records are truly useful based on subsequent usage. The key is not just to remember a sentence, but to keep old records usable when new evidence emerges. The official team also keeps EverMemOS outside of training, using it to observe how the model performs when migrating to a memory framework that has never been seen.
What can you get now, and what is still lacking?
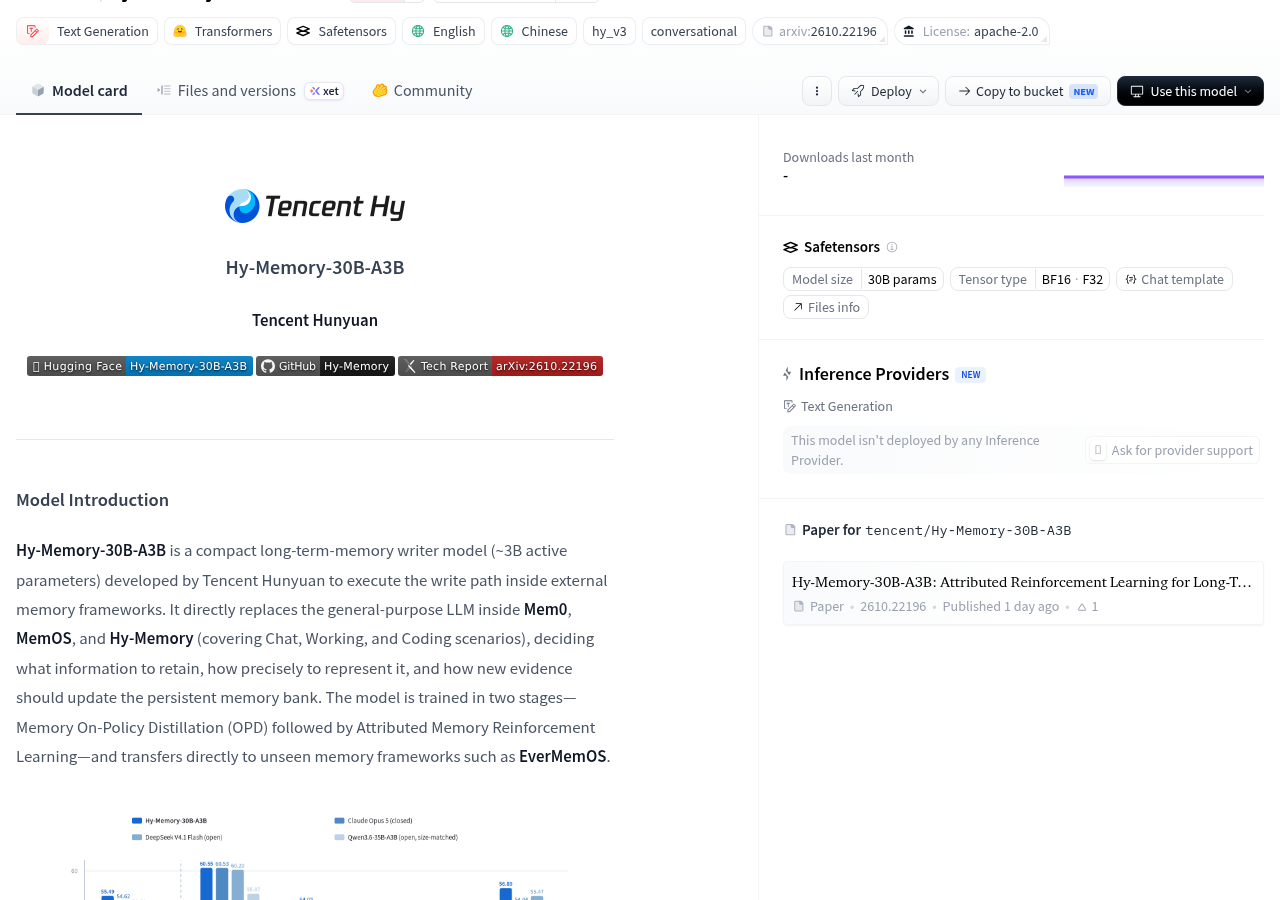
The official model page lists model weights, configurations, and model cards, and provides Hy-Memory-30B-A3B model page. The file uses Safetensors, with BF16 and F32 labeled on the page; This indicates that weights have been provided, not just future plans.
- The official deployment method is vLLM, specifying the test version as v0.31.0, and it can be called via an interface compatible with OpenAI.
- The official team also provides framework code and evaluation tool portals, suitable for further verification of data formats, memory structures, and evaluation methods.
- The model page clearly states that there is currently no Inference Provider deployment, so “Weights are open” should not be interpreted as “Existing managed interfaces can be used directly.”
Warning Downloadable weights only address the issue of “whether the file can be obtained.” Whether the license meets the specific purpose, whether the runtime is compatible, whether the hardware can fit properly, and whether the real task can work stably still need to be verified separately; Official information does not provide conclusions on memory, speed, or cost for ordinary consumer-grade devices.
When actually preparing for use, it is inspected and accepted along a complete chain
- First, confirm that the task truly requires maintaining user facts, preferences, or project status across conversations, rather than just relying on the current context.
- Then, according to the official framework, the answer model and search configuration are fixed, only replacing memory writing models, avoiding blaming changes in other components on it.
- Retain the empty database start, write results, updated memory, and final answer, and check whether the model has missed or misremembered information, or treats inferences as fact.
- Finally, add real scenarios for deletion, error correction, and preference changes. Writing once does not mean long-term maintenance, nor does it mean the entire assistant is reliable.
The value of Hy-Memory-30B-A3B is clear: it turns the writing process in long-term memory systems, which is often handled by general models, into a replaceable model. At this stage, it’s suitable for developers who already have external memory frameworks and are willing to deploy and conduct individual acceptance tests; Those who only want to directly access managed chat services or expect to run on any computer immediately after downloading weights still need to wait for more complete running conditions and independent real-world testing.
Official information
Self-made software
Versions, changes and supported installers all come from the same public release records.
LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗ScreenLex
Turn subtitles from your own films and shows into an English vocabulary library, entirely offline.
View public downloads and updates ↗HyphenScreen
Screen recording and editing with a Resolve-style timeline, automatic redaction and pre-export checks.
View public downloads and updates ↗Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Scan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan




Comments
Loading comments…