Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
Note Last retest: 2026-08-23 · HyphenTech | Request official documentation pages and interfaces from each vendor, with screenshots anchored at the free quota evidence; If you can’t get a hard number, mark it all and check it in the console—no fabrication.
Note This table only includes official free quotas issued to ordinary users. Leaked private keys, shared accounts of unknown origin, quotas obtained through quota transfer stations, fraudulent or forged regions, will not be included, tested, or forwarded.
📋 ** Quick Reference Table **
| Service | Free type | Key points of the credit limit | Direct domestic connections |
|---|---|---|---|
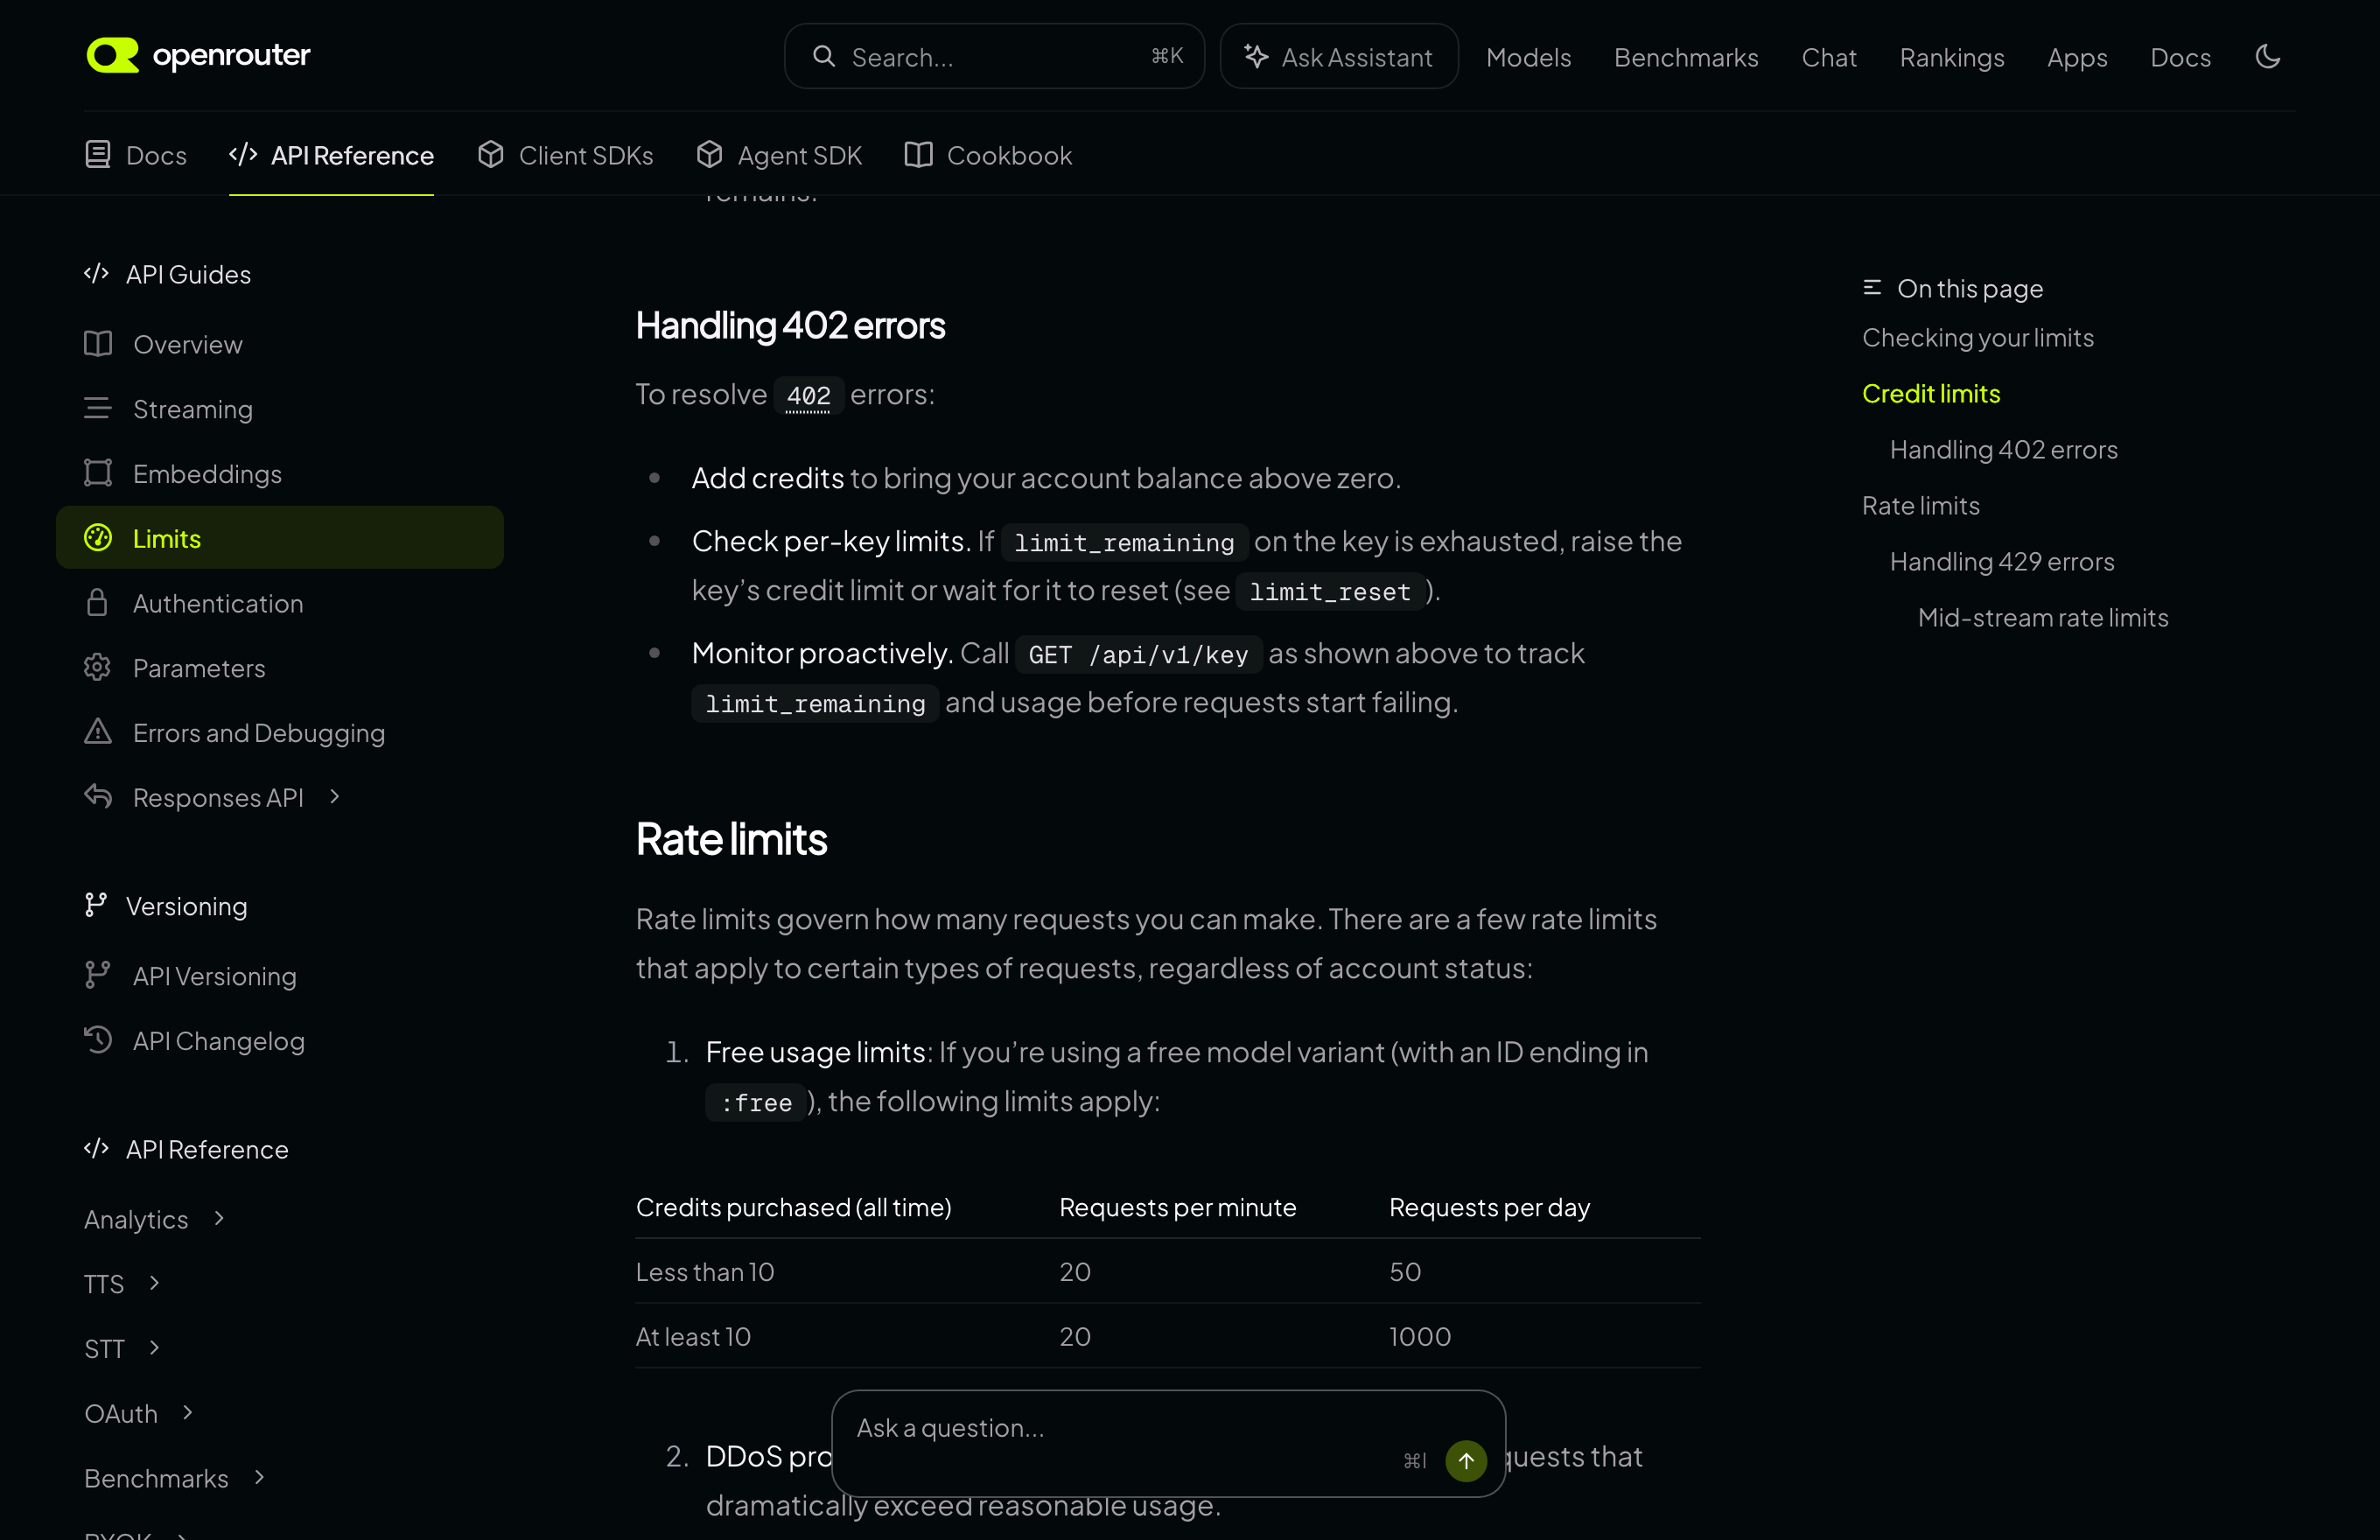
| OpenRouter | Periodic free tier | Models with the :free suffix: 20 times/minute + 50 times/day; After cumulative top-ups of 10 credits, daily limit increases to 1000 times (RPM remains at 20) | Agency required |
| SiliconFlow | Periodic free tier | Free model speed limits are fixed: language model RPM 1000–10000, TPM 50000–5000000; vector model RPM 2000–10000, TPM 500000–1000000; resort RPM 2000, TPM 5000 | Direct connection is suitable |
| Zhipu BigModel | Periodic free tier | Models labeled as “Free Model” are called for free; Specific speed limits should be checked on the console (official documentation does not provide unified numbers) | Direct connection is suitable |
| Magic ModelScope | Periodic free tier | Provided free of charge to registered users, with specific limits subject to the official “Usage Restrictions Notice.” | Direct connection is suitable |
| Groq | Periodic free tier | The free tier provides credit amounts by model: RPM 10–30, RPD 100–14,400, TPM 1.2K–70K, TPD 3.6K–500K | Agency required |
| Cloudflare Workers AI | Reset daily | 10,000 Neurons free per day | Agency required |
| Agnes AI | Periodic free tier | Free quota is limited according to plan; Video interface is about 2 times per minute | Direct connection on Mac is available; In some network environments, domain names are blocked and proxy is required |
| Hugging Face Inference Providers | Each month is granted a quota | Free users receive $0.10 per month; PRO users pay $2.00 per month; Team/Enterprise users receive $2.00 per seat | Agency required |
| NVIDIA NIM (build.nvidia.com) | Periodic free tier | The official page labels it as Free Inference / Free Endpoint. The unified credit limit has not been published and must be confirmed on the console | Agency required |
| Google Gemini API | Periodic free tier | Limits are calculated as RPM / TPM / RPD, and vary by model; The official requirement is to check the rate limit page in AI Studio, but no unified number is given | Agency required |
| Alibaba Cloud Bailian Model Studio | One-time trial payment | New users receive a quota of 100 million+ tokens | Direct connection is suitable |
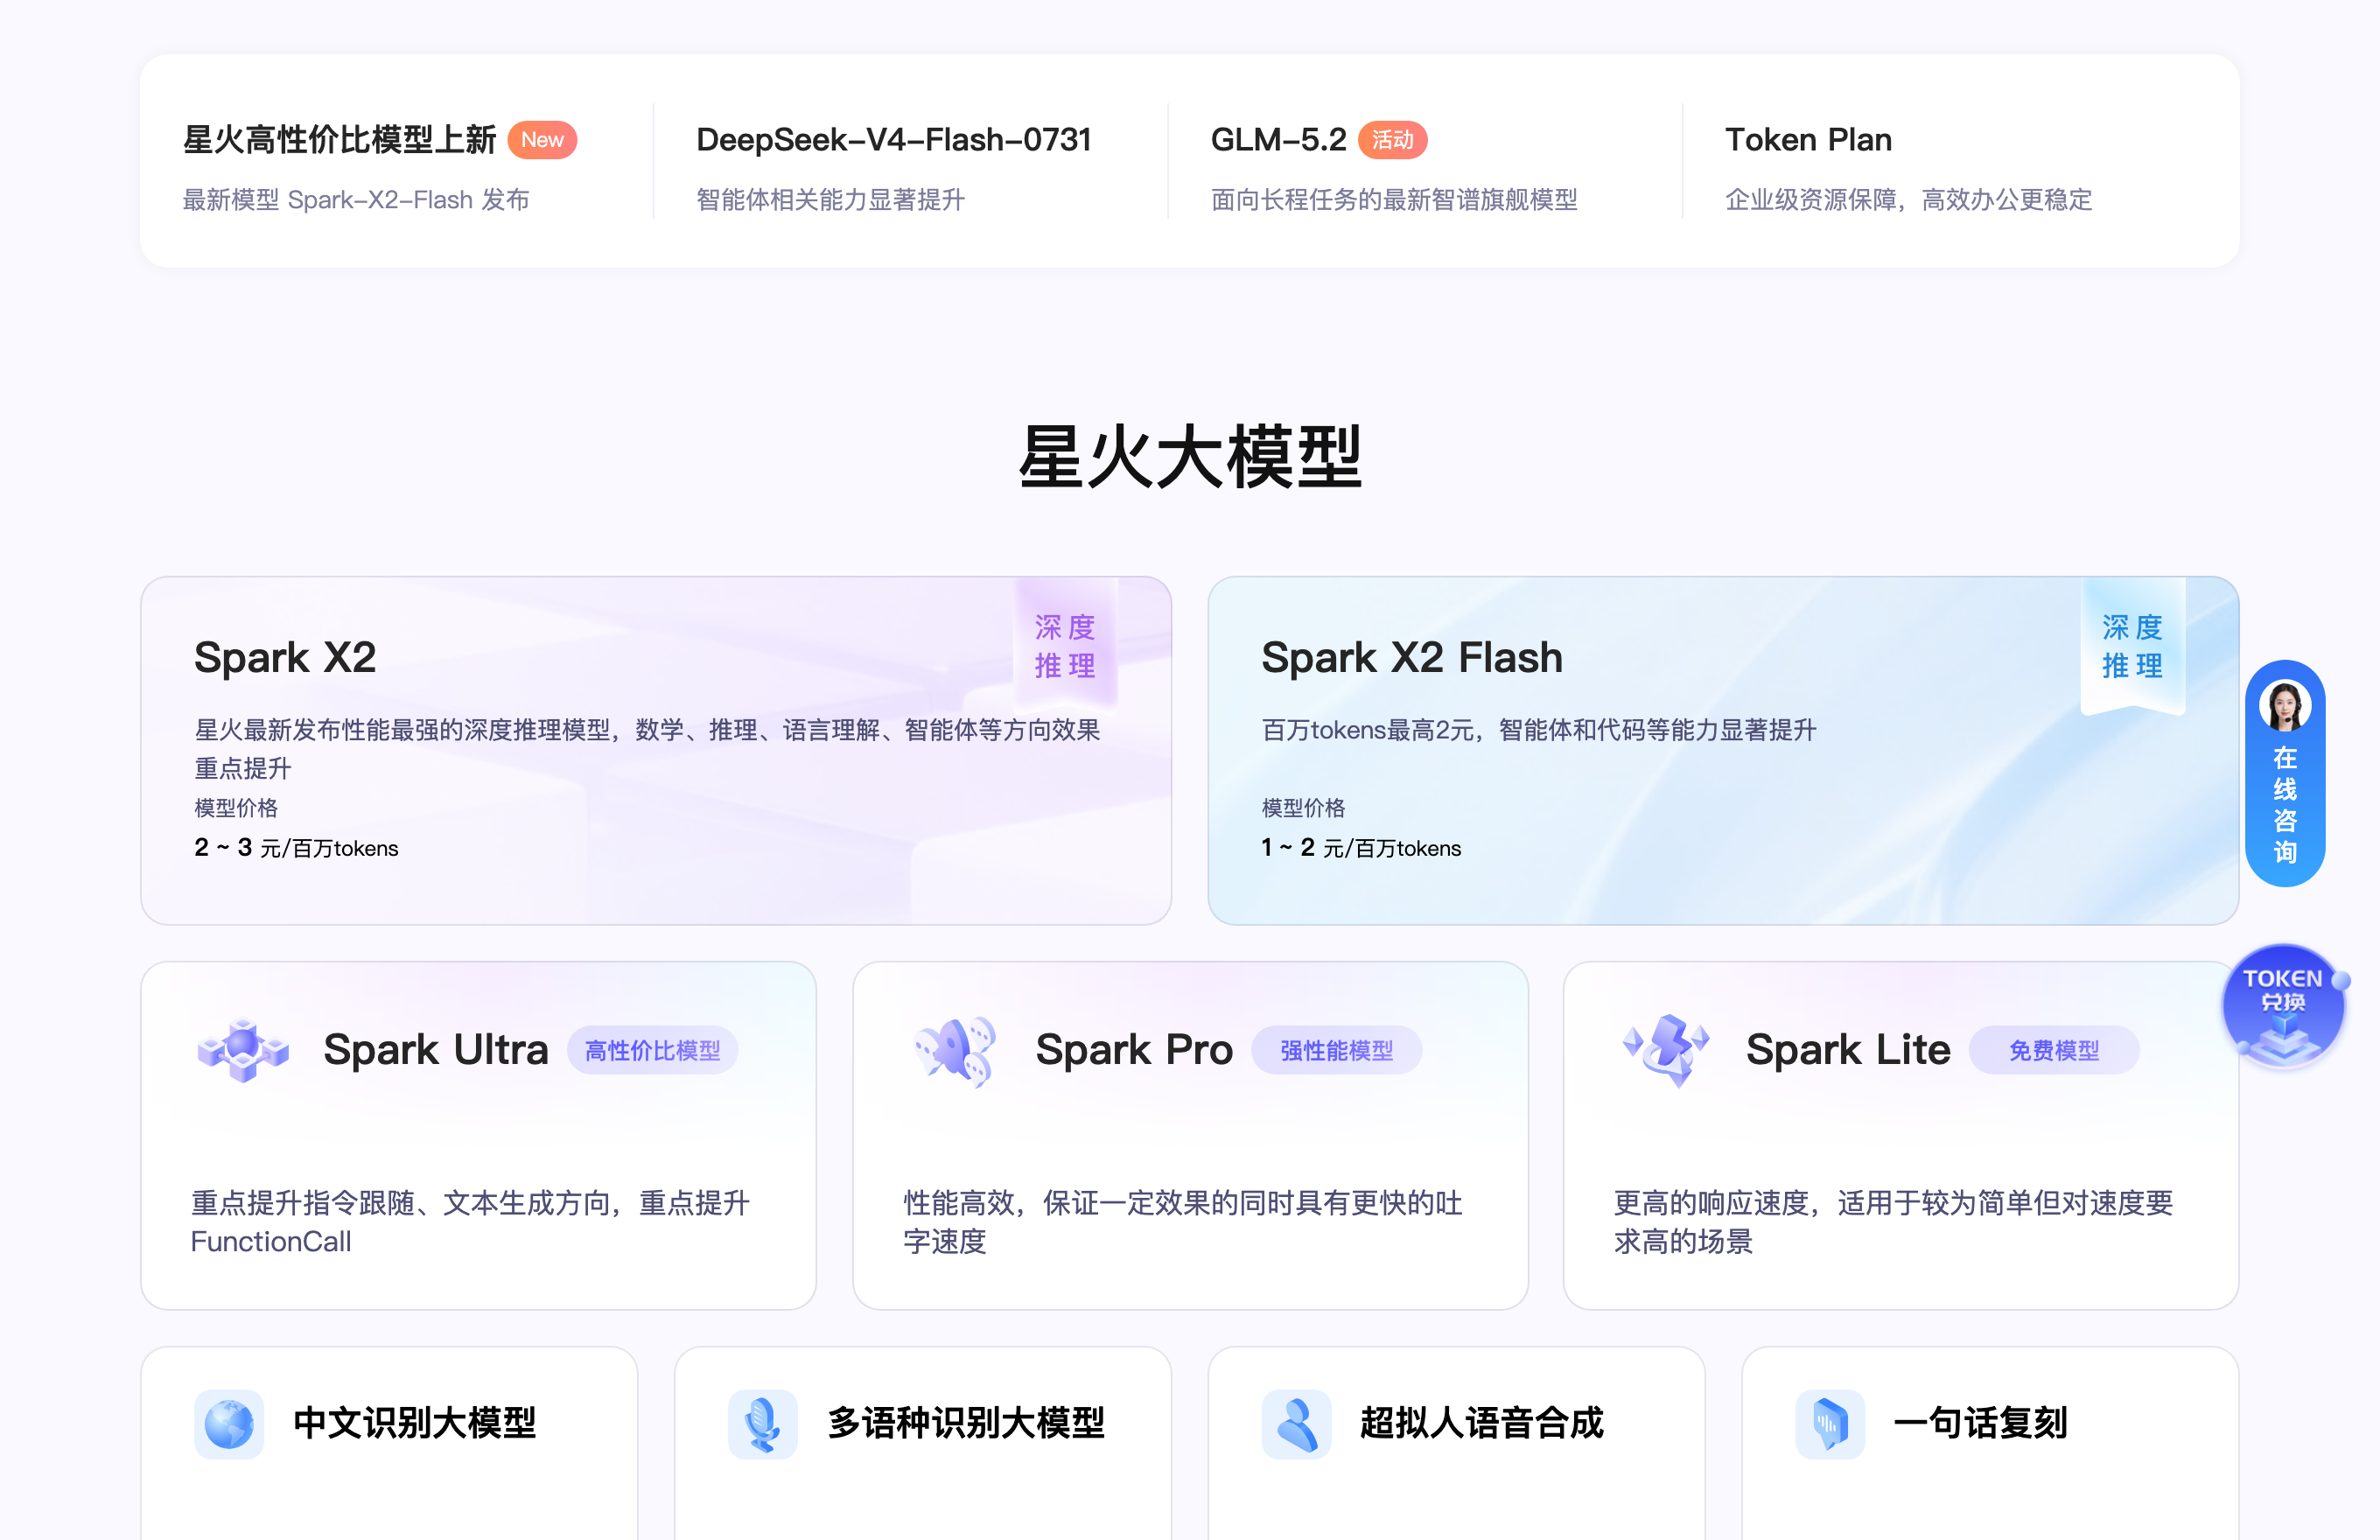
| iFlytek Spark | Periodic free tier | Some versions are marked as free to use; others are manually claimed as “free packs,” with the amount determined on the claim page | Direct connection is suitable |
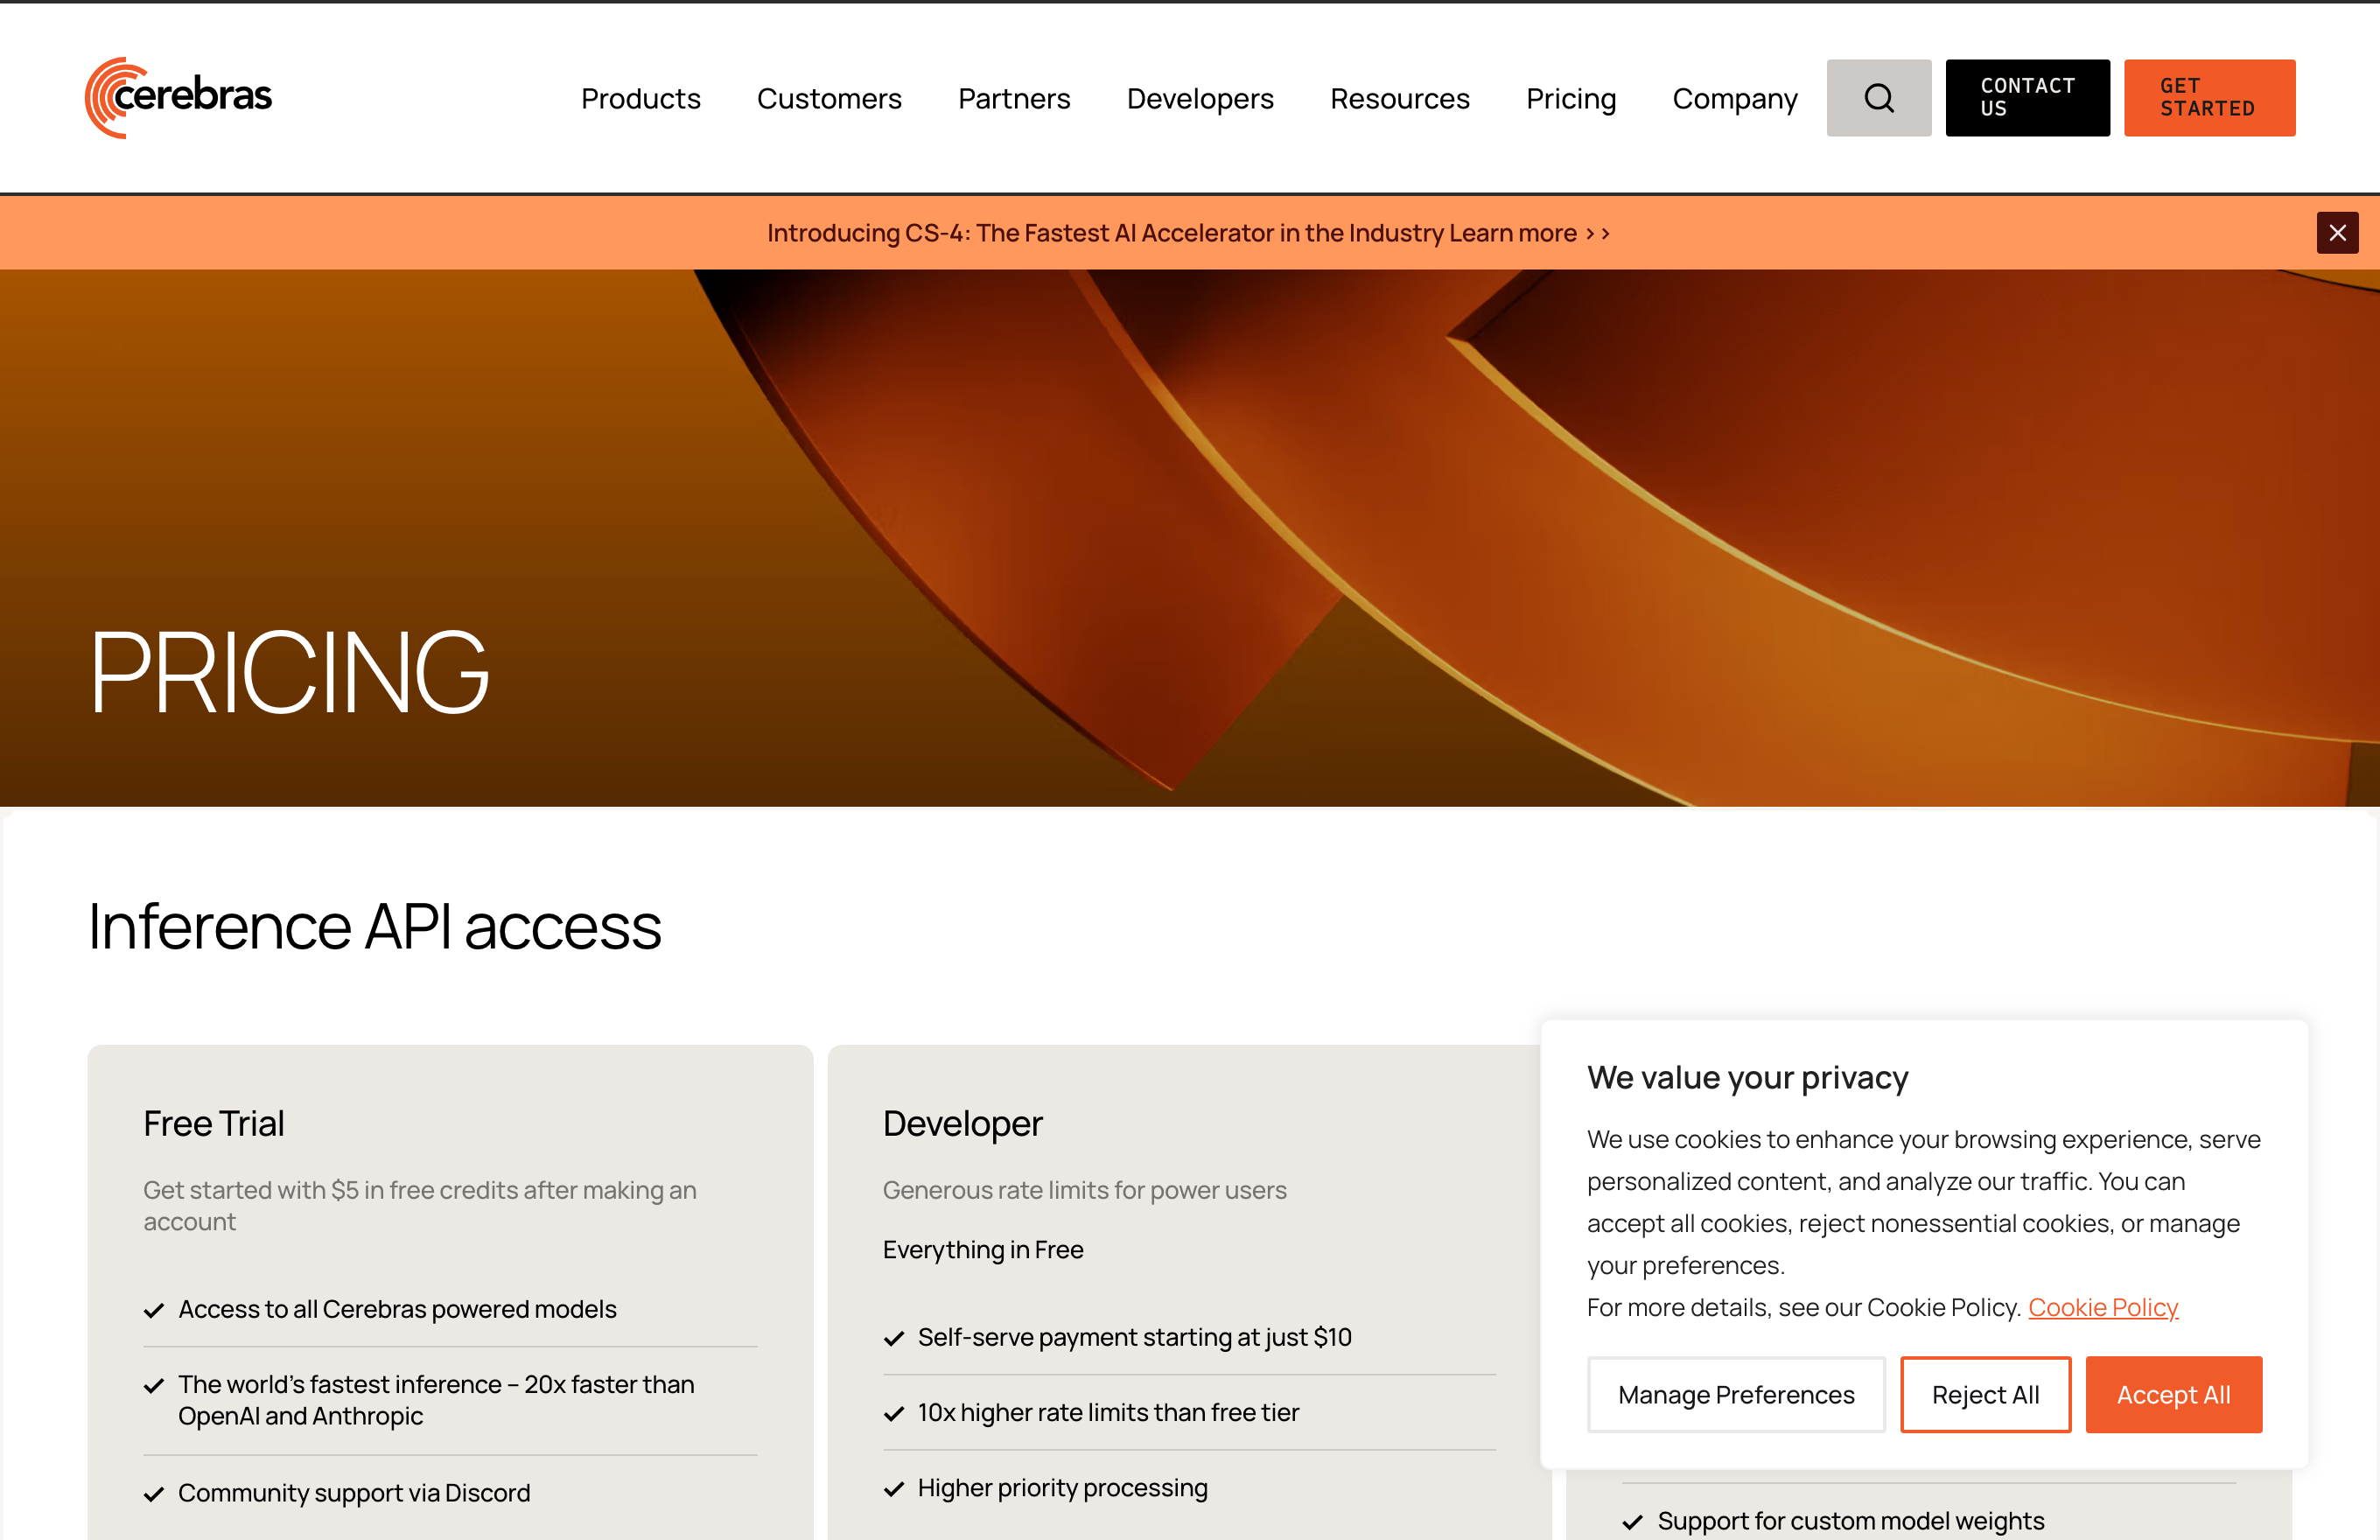
| Cerebras | One-time trial payment | Register to receive $5 in free credit | Agency required |
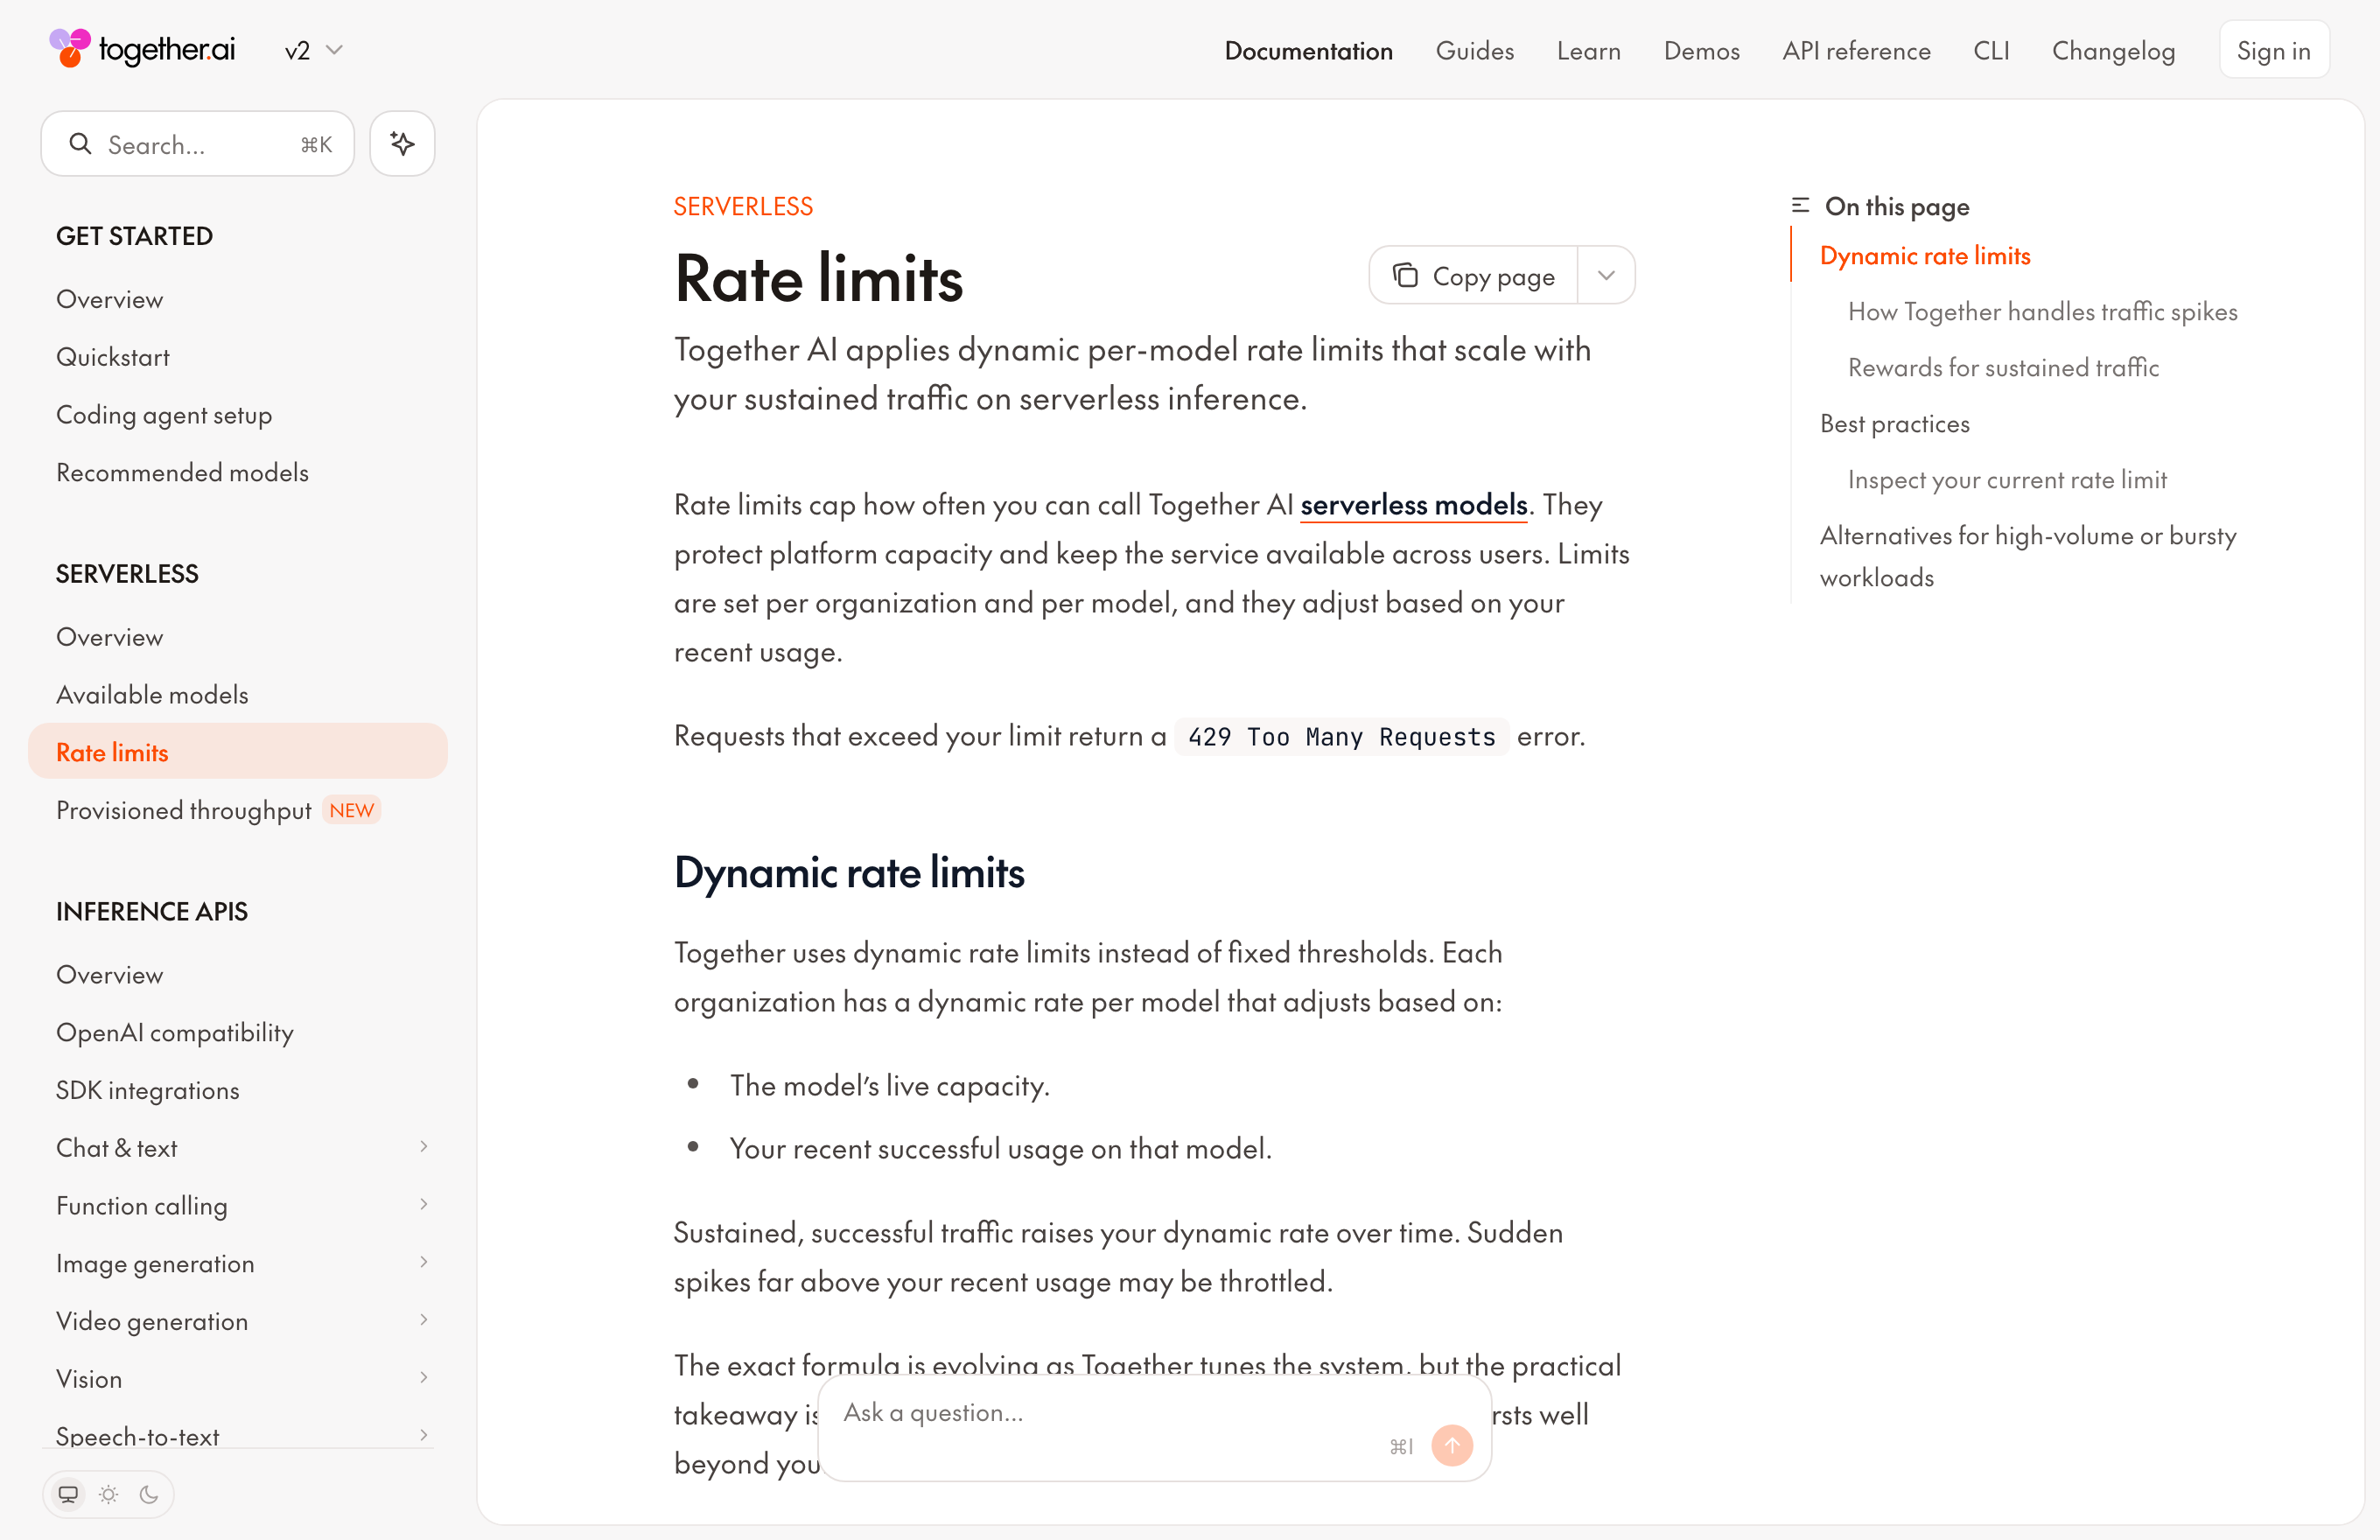
| Together AI | Periodic free tier | Dynamic rate limiting: Each organization’s rate and each model’s rate automatically adjusts with continuous traffic, with no fixed threshold | Agency required |
| Open source hosting (Ollama / llama.cpp / whisper.cpp / Piper) | Open source custody | No external credit limit restrictions | Direct connection is suitable |
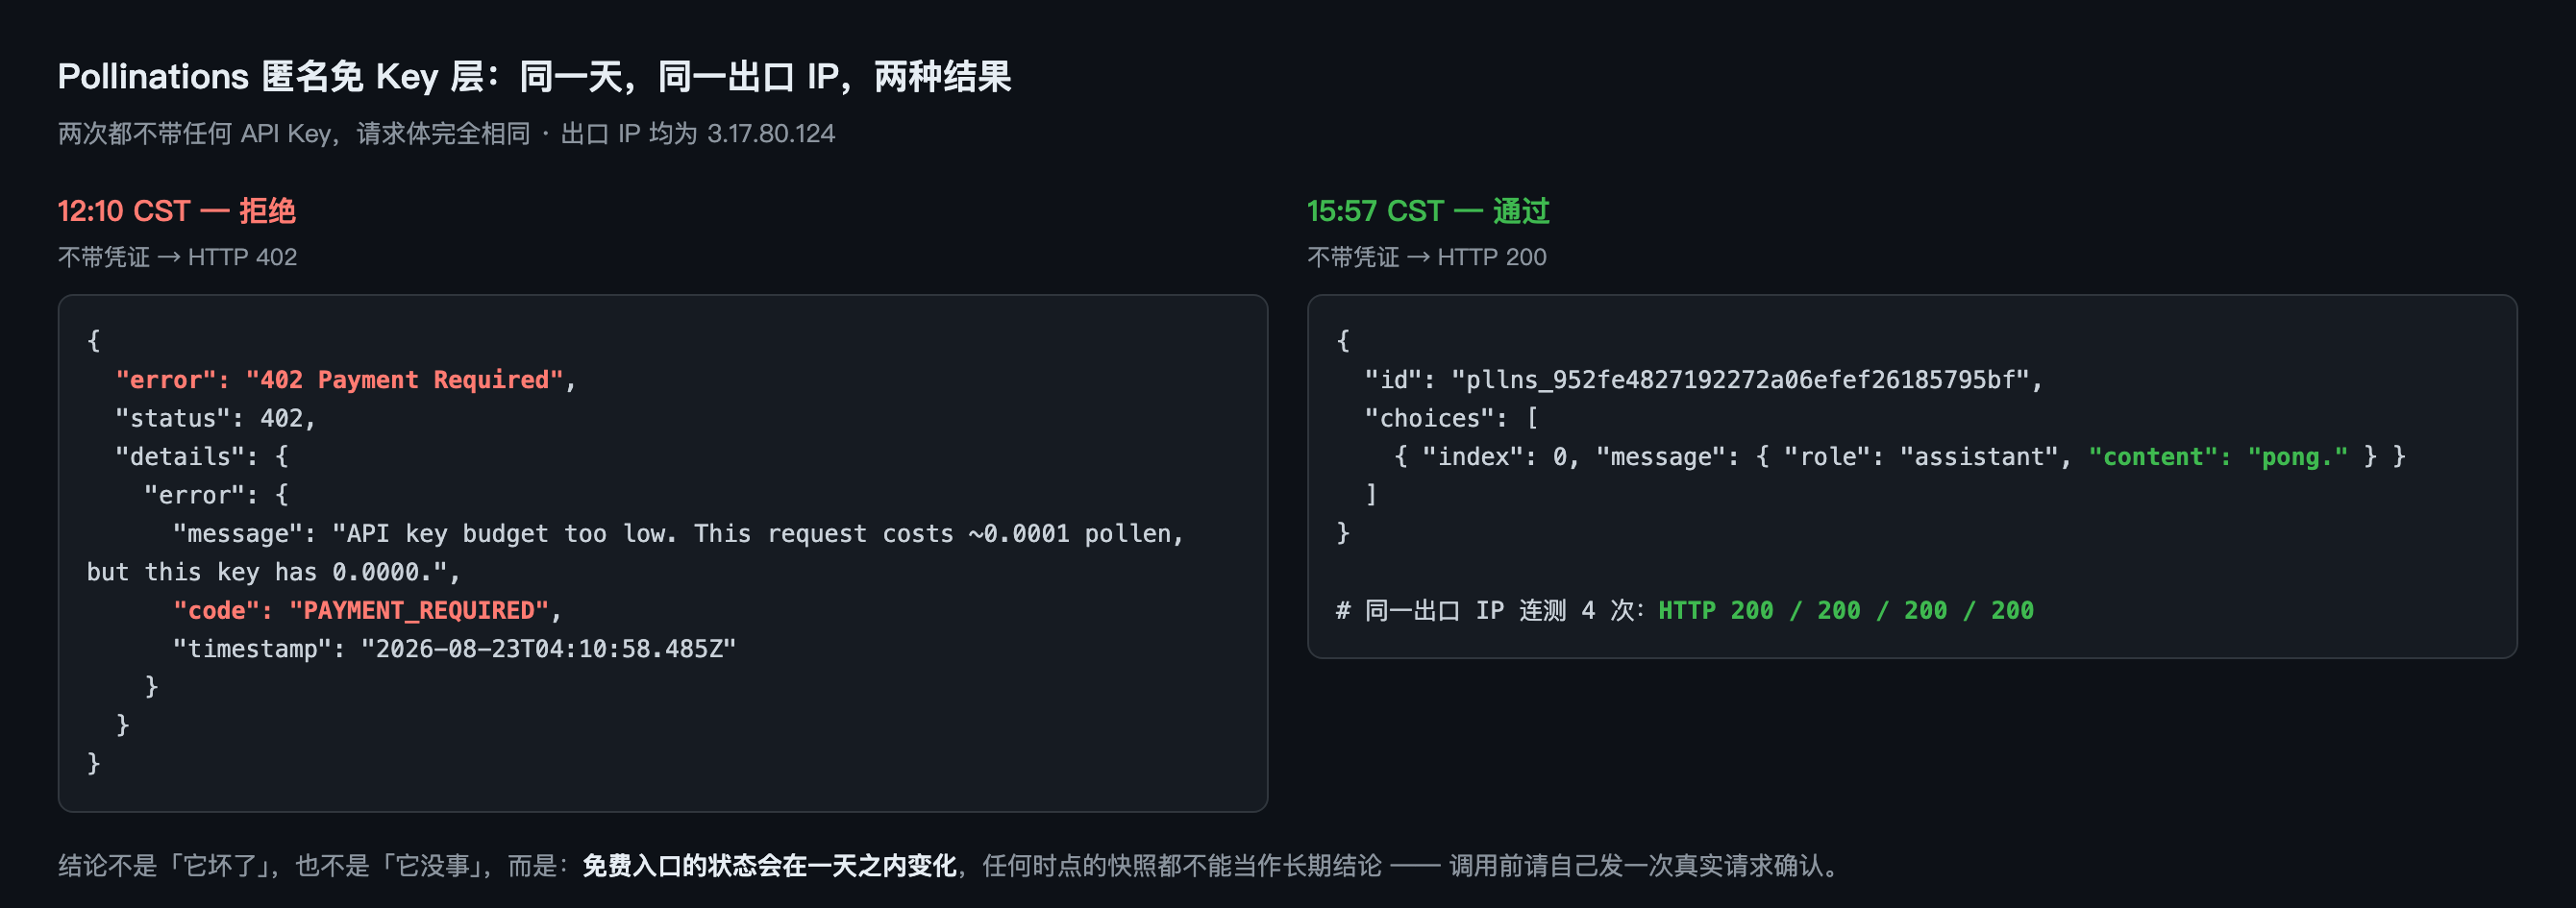
| Pollinations | Keyless public interface | The anonymous layer does not publish the quota number; In actual tests, it can be called directly, but temporary 402 may occur | Agency required |
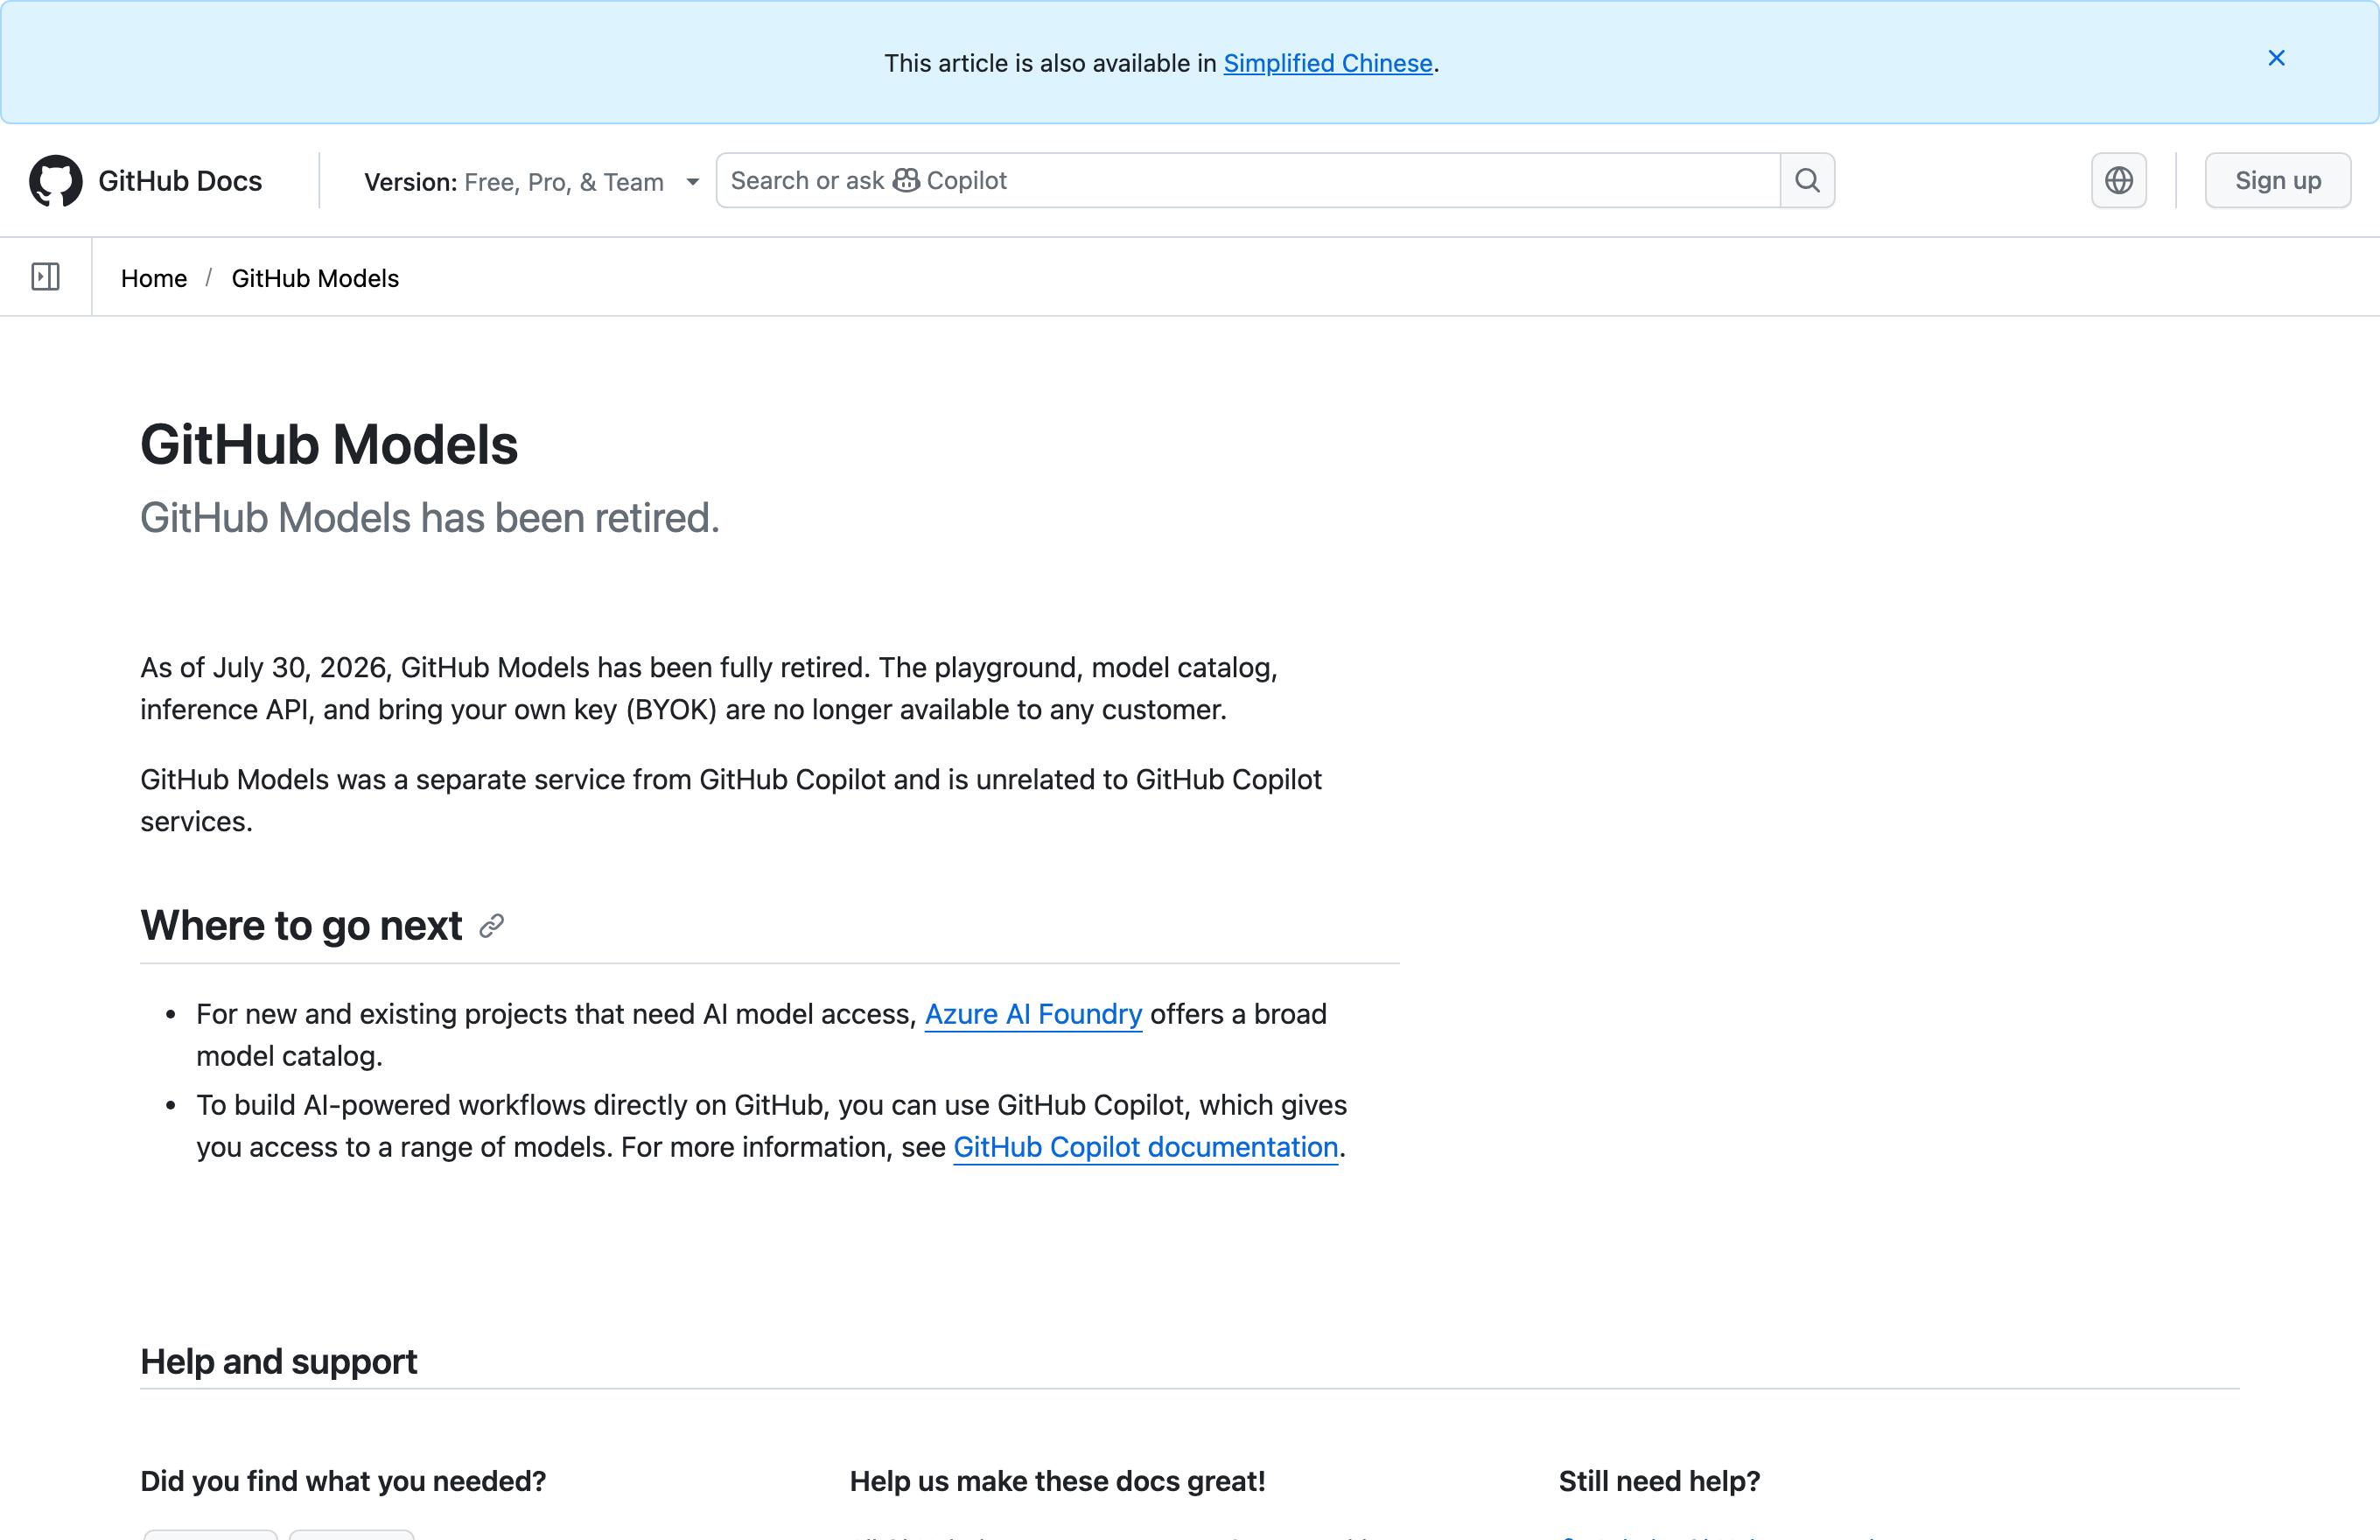
| GitHub Models | Retired / Invalid | None | — |
Note Each of the following points shows: base_url that can be directly copied, call code, features, and the most common restrictions. The screenshots are anchored at the free quota evidence section on each company’s official page.
OpenRouter
One Key connects 22 zero-price models, with the widest range of aggregation entry points among free quotas
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://openrouter.ai/ |
| base_url | https://openrouter.ai/api/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Register an account and create a Key, and use the free variant without a credit card |
| Quota | Models with the :free suffix: 20 times/minute + 50 times/day; After cumulative top-ups of 10 credits, daily limit increases to 1000 times (RPM remains at 20) |
| Reset cycle | Reset every day |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | I pulled /api/v1/models on 2026-08-23 with full price verification + screenshot of the official rate limit table |
Features
-
2026-08-23 Actual Take: Out of 422 models across the site, 22 have dual zero pricing for input and output, with 5 contexts reaching 1 million
-
18 with the ‘free’ suffix (limited by the platform’s free tier), 4 without (vendor-side pricing is 0, not included in this cap)
-
Four without extensions: stealth/ox-alpha, google/lyria-3-pro-preview, google/lyria-3-clip-preview, openrouter/free
-
NVIDIA alone accounts for 8 out of 22 free models
Note Not being restricted by the platform’s free tier does not mean unlimited traffic: providers may still return 429, Cloudflare’s DDoS passport is always active, and when the account balance is negative, the free model also shows errors.
from openai import OpenAI
client = OpenAI(api_key="<KEY>", base_url="https://openrouter.ai/api/v1")
r = client.chat.completions.create(
    model="nvidia/nemotron-3-ultra-550b-a55b:free",
    messages=[{"role":"user","content":"你好"}])
SiliconFlow
The most generous provider in China for direct connection and free model speed limits; free and paid versions are distinguished by model prefixes
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://cloud.siliconflow.cn/ |
| base_url | https://api.siliconflow.cn/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Registration + Real-name authentication (you can use all free models after real-name verification) |
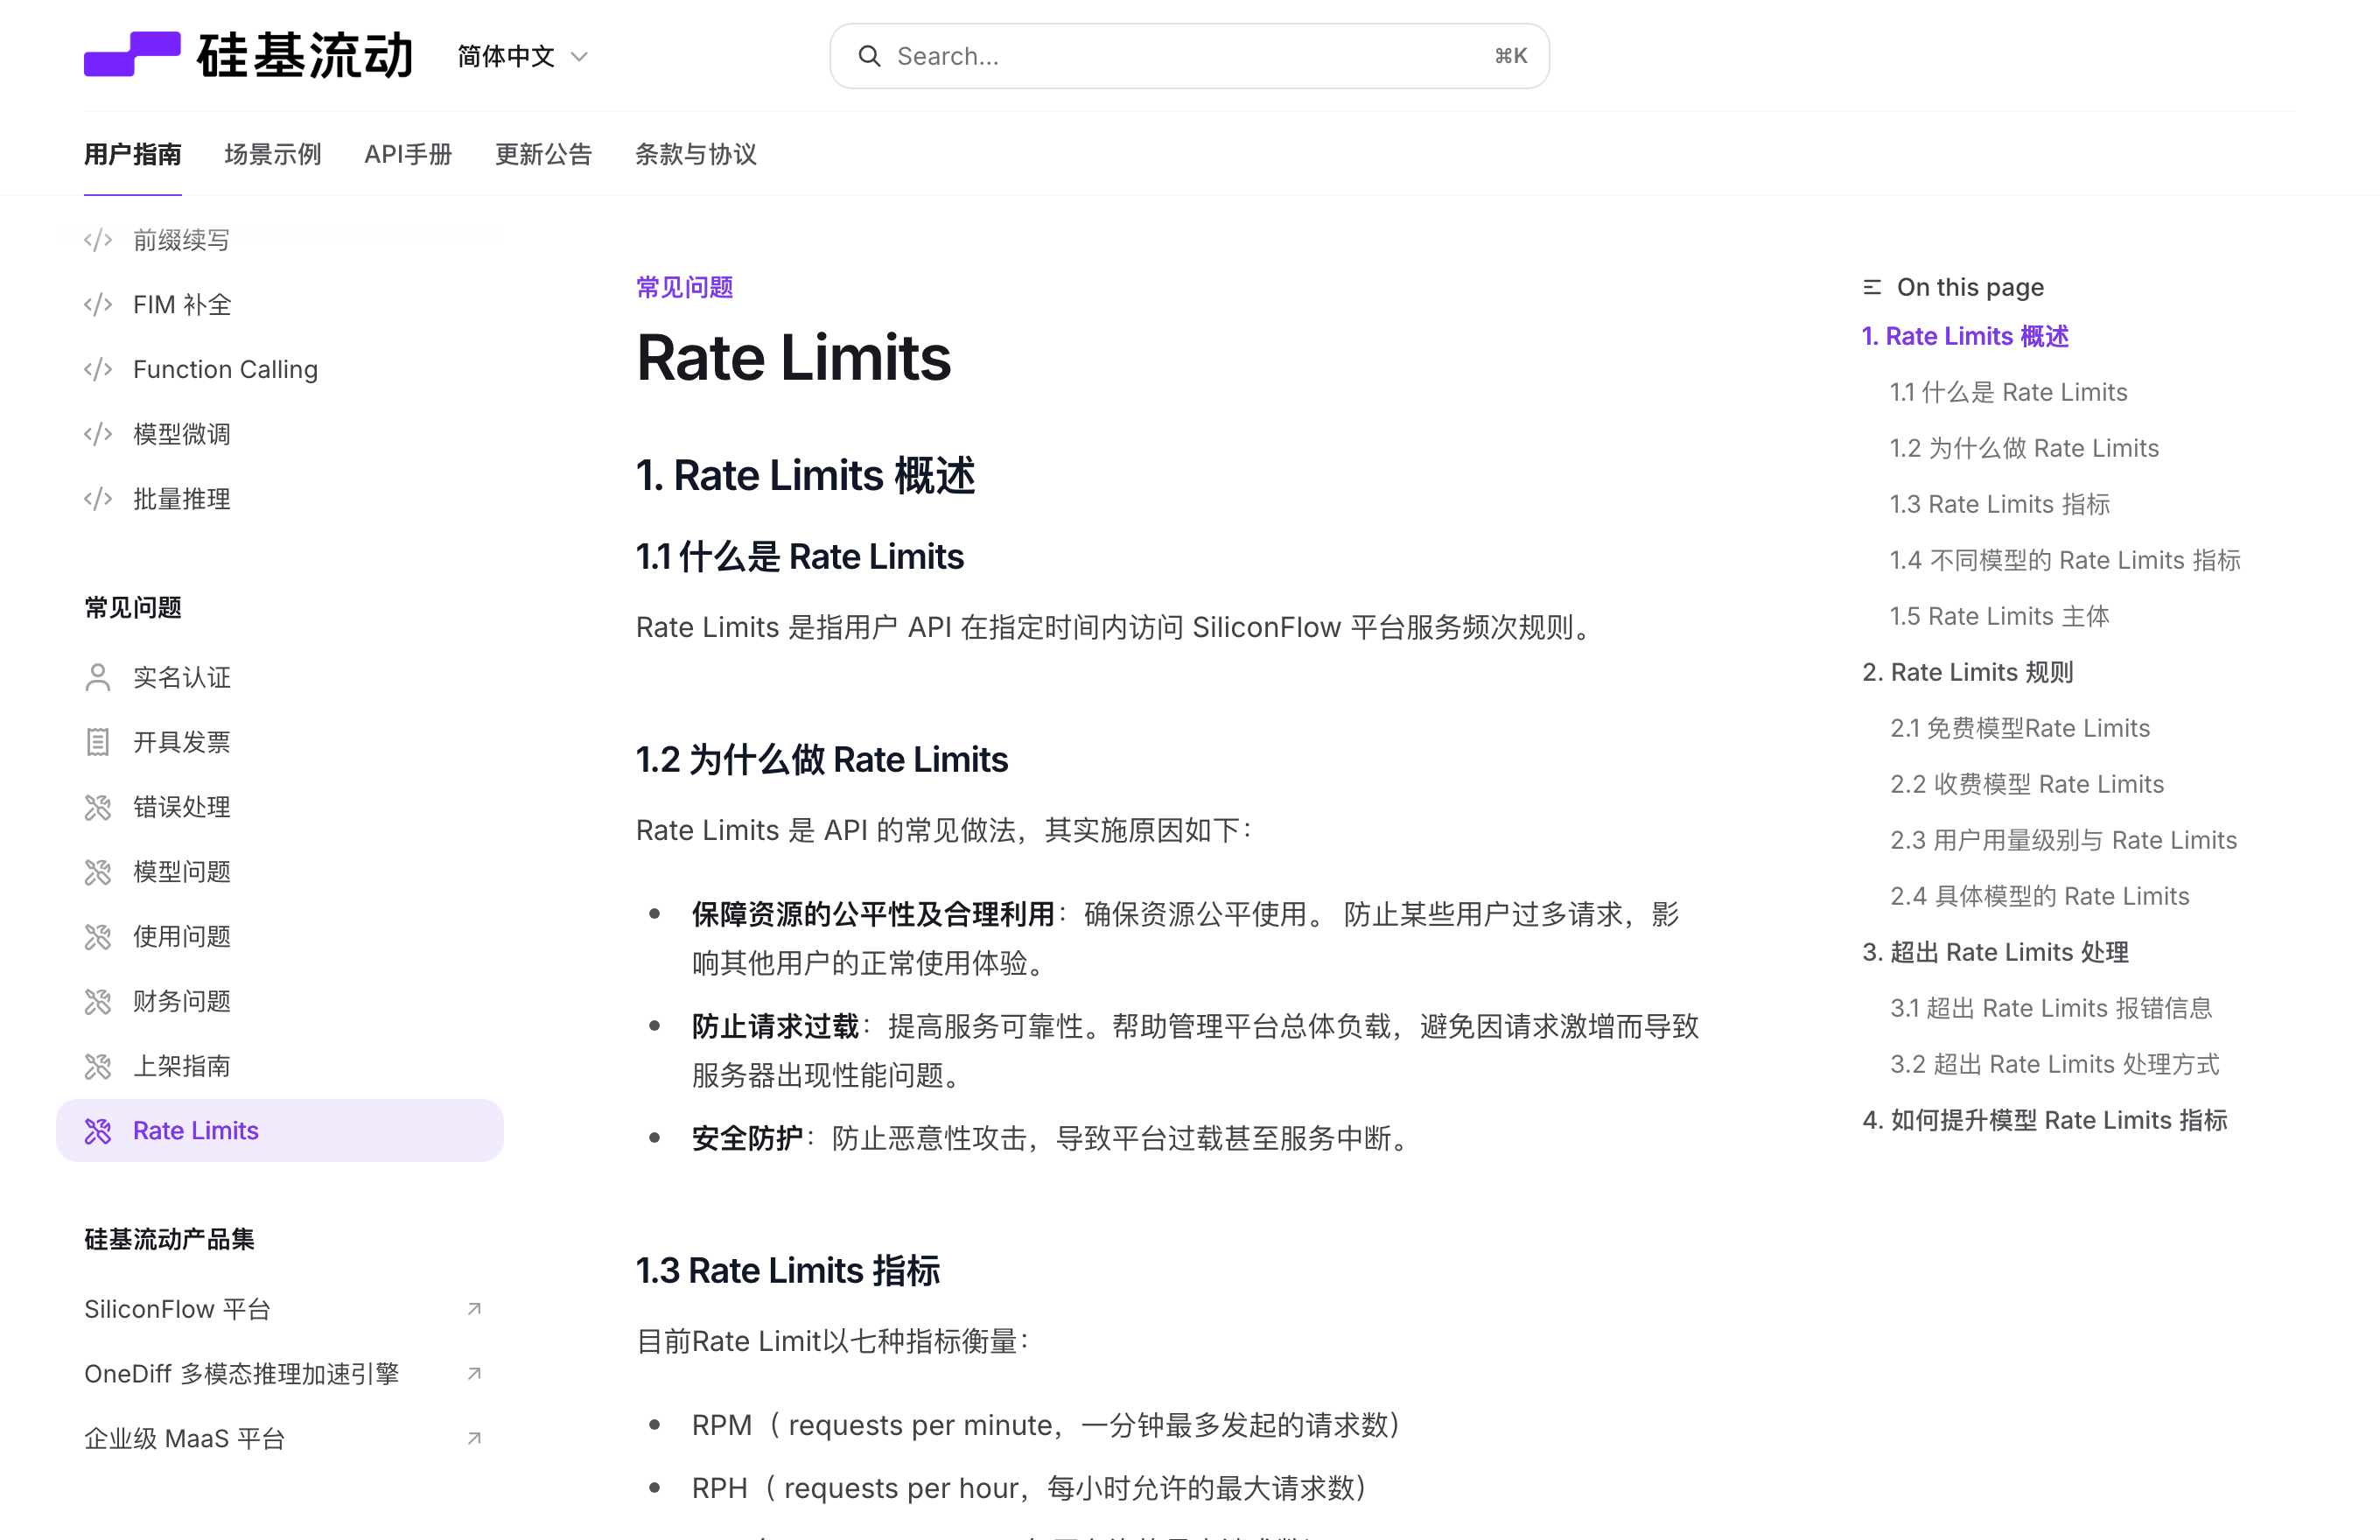
| Quota | Free model speed limits are fixed: language model RPM 1000–10000, TPM 50000–5000000; vector model RPM 2000–10000, TPM 5000000–1000000; resort RPM 2000, TPM 500000; image generation IPM 2, IPD 400 |
| Reset cycle | Rolling by minute per day |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
| Verification basis | Official speed limit document 2026-08-23 Reviewed and screenshotted |
Features
-
⚠️ The most common pitfall: the free version uses the original model name (Qwen/Qwen2.5-7B-Instruct), while the paid version adds the Pro/ prefix (Pro/Qwen/Qwen2.5-7B-Instruct) before the name. If you fill in the wrong prefix, the free version becomes a fee.
-
The speed limit for free models is fixed and does not rank according to account usage; Only paid models fluctuate according to usage level
-
After calling the free model, the bill shows a fee of 0
Note When RPM, RPH, RPD, TPM, TPD, IPM, IPD reaches peak first, rate limiting is triggered, not just by the number of requests.
from openai import OpenAI
client = OpenAI(api_key="<SILICONFLOW_KEY>", base_url="https://api.siliconflow.cn/v1")
r = client.chat.completions.create(
    model="Qwen/Qwen2.5-7B-Instruct",   # 免费版:无 Pro/ 前缀
    messages=[{"role":"user","content":"你好"}])
BigModel Zhipu
The only domestic platform with a complete set of four items: text, visuals, text-to-image, and text-to-video
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://bigmodel.cn/ |
| base_url | https://open.bigmodel.cn/api/paas/v4 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Register an account to obtain an API Key |
| Quota | Models labeled as “Free Model” are called for free; Specific speed limits should be checked on the console (official documentation does not provide unified numbers) |
| Reset cycle | Based on the control console |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
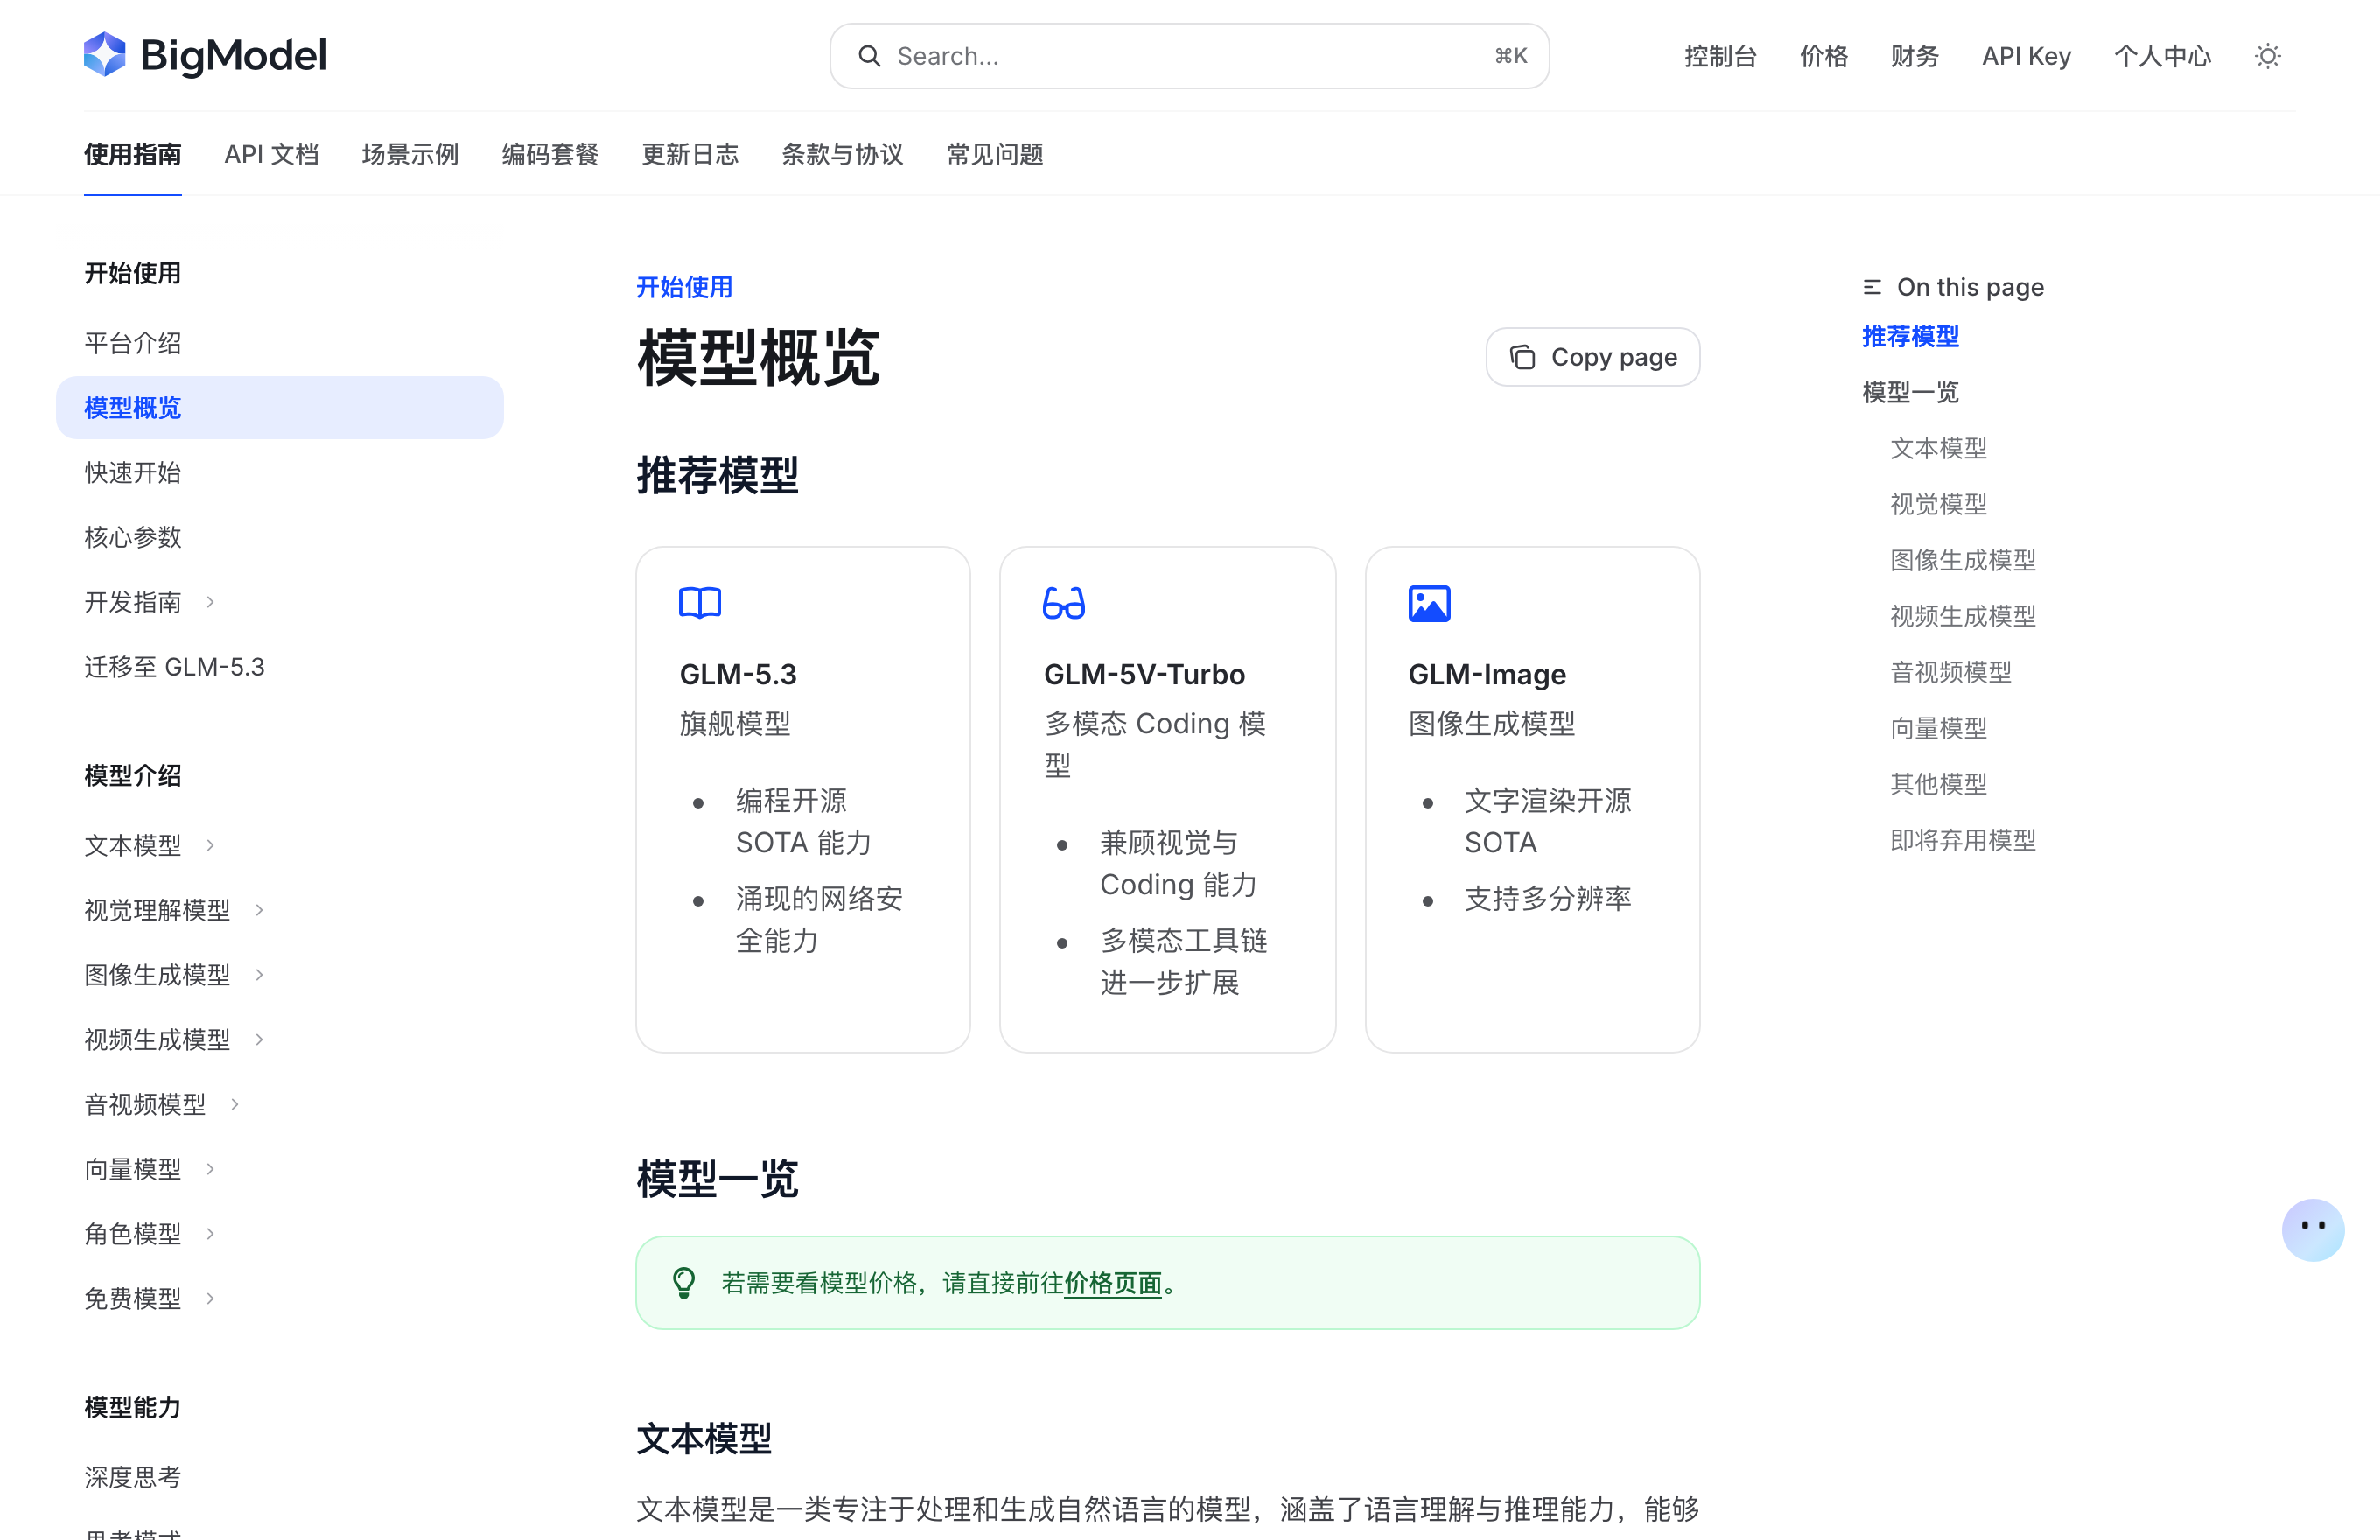
| Verification basis | Official Model Overview Page 2026-08-23 View and Screenshot (Free Model Categories) |
Features
-
Text: GLM-4.7-Flash, GLM-4-Flash-250414 (128K context / 16K output)
-
Vision: GLM-4.6V-Flash, GLM-4.1V-Thinking-Flash, GLM-4V-Flash (64K / 16K)
-
Text-to-image image: CogView-3-Flash
-
Text-to-Video Video: CogVideoX-Flash
-
The same company has gathered all four types of free versions for the same mode, which is rare among free limits
Note Free models will be discontinued with each version iteration (the documentation already marks the model as “going offline”). Before integration, check the current status on the model overview page.
from openai import OpenAI
client = OpenAI(api_key="<ZHIPU_KEY>",
                base_url="https://open.bigmodel.cn/api/paas/v4")
r = client.chat.completions.create(
    model="glm-4-flash-250414",
    messages=[{"role":"user","content":"你好"}])
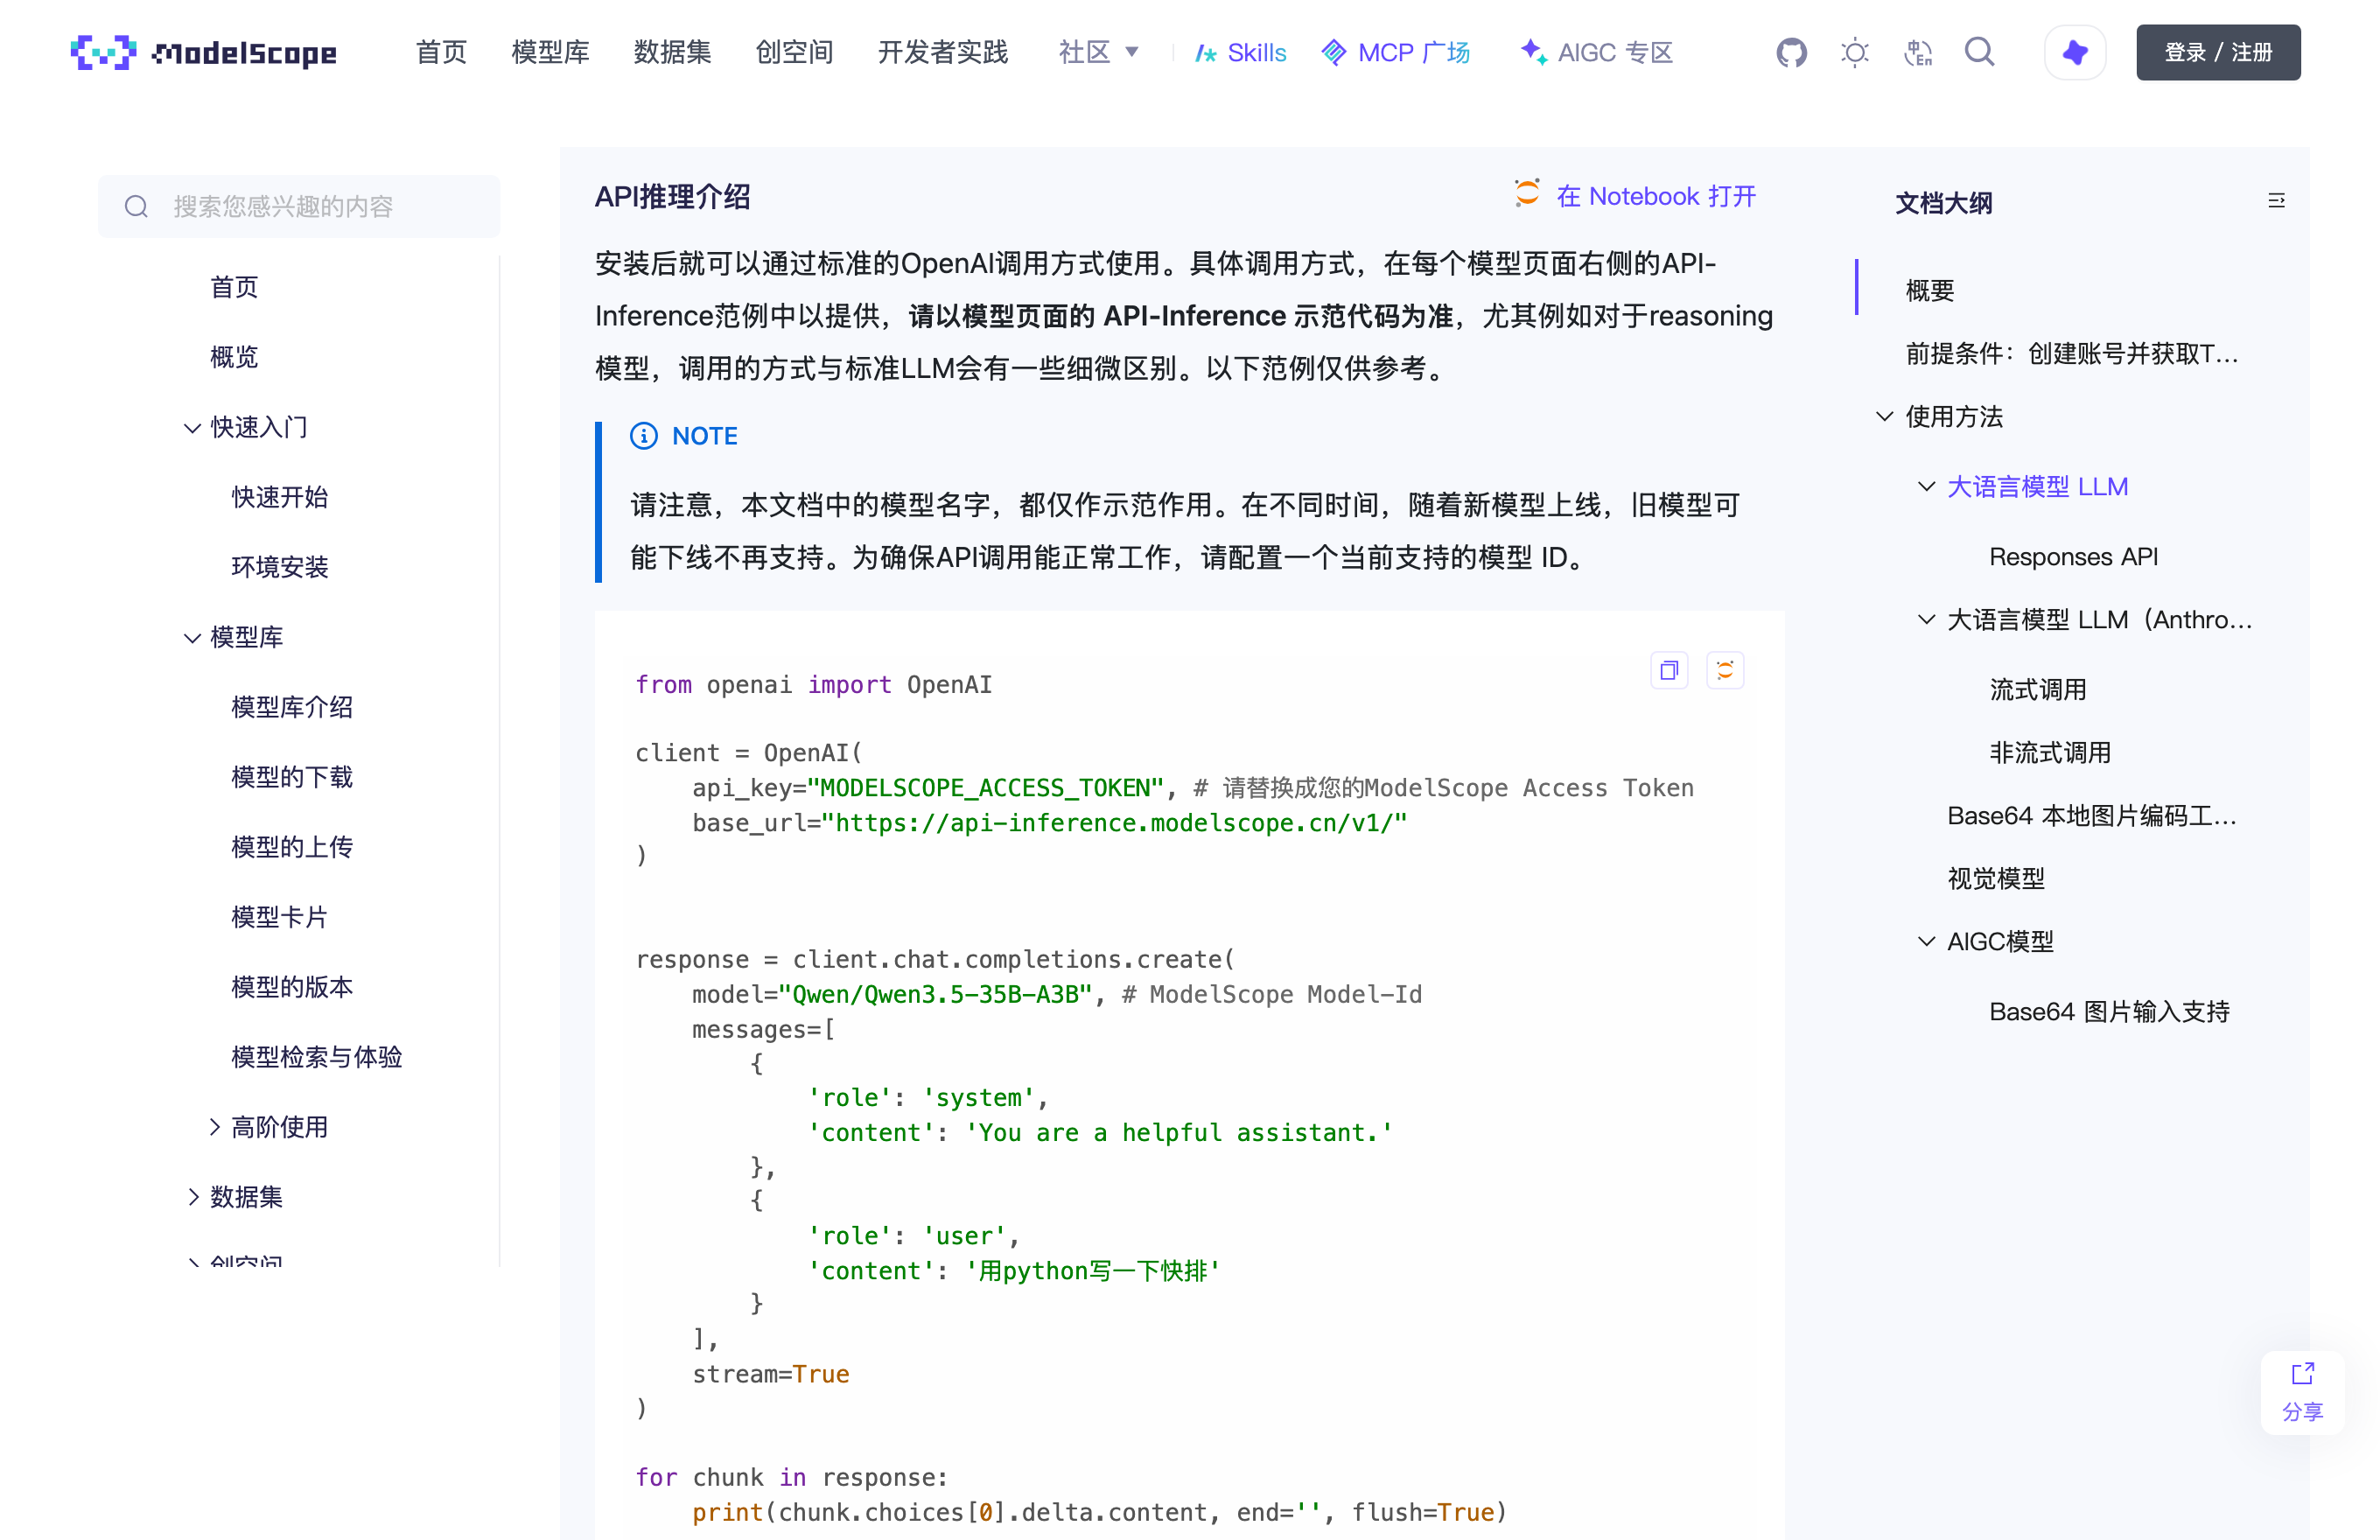
ModelScope
Register and use immediately, no real-name real-name required for domestic inference entry; both text and text-to-image follow the same OpenAI-compatible interface
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://www.modelscope.cn/ |
| base_url | https://api-inference.modelscope.cn/v1/ |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | After registering an account, obtain an Access Token at https://modelscope.cn/my/myaccesstoken |
| Quota | Provided free of charge to registered users, with specific limits subject to the official “Usage Restrictions Notice.” |
| Reset cycle | Please refer to the official documentation |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
| Verification basis | Official API-Inference documentation 2026-08-23 Reviewed and screenshotted |
Features
-
Text-to-image uses v1/images/generations, while asynchronous tasks use v1/tasks/{task_id} for polling
-
When higher concurrency is needed, external providers can be bound via API-Provider capabilities
Note The official figure has not been released for a unified quota; high-concurrency scenarios must be confirmed on the console manually.
from openai import OpenAI
client = OpenAI(api_key="<MODELSCOPE_ACCESS_TOKEN>",
                base_url="https://api-inference.modelscope.cn/v1/")
Groq
The lowest latency among the free tiers, but what really lags is TPM, not request count
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://console.groq.com/ |
| base_url | https://api.groq.com/openai/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Register an account and create a Key |
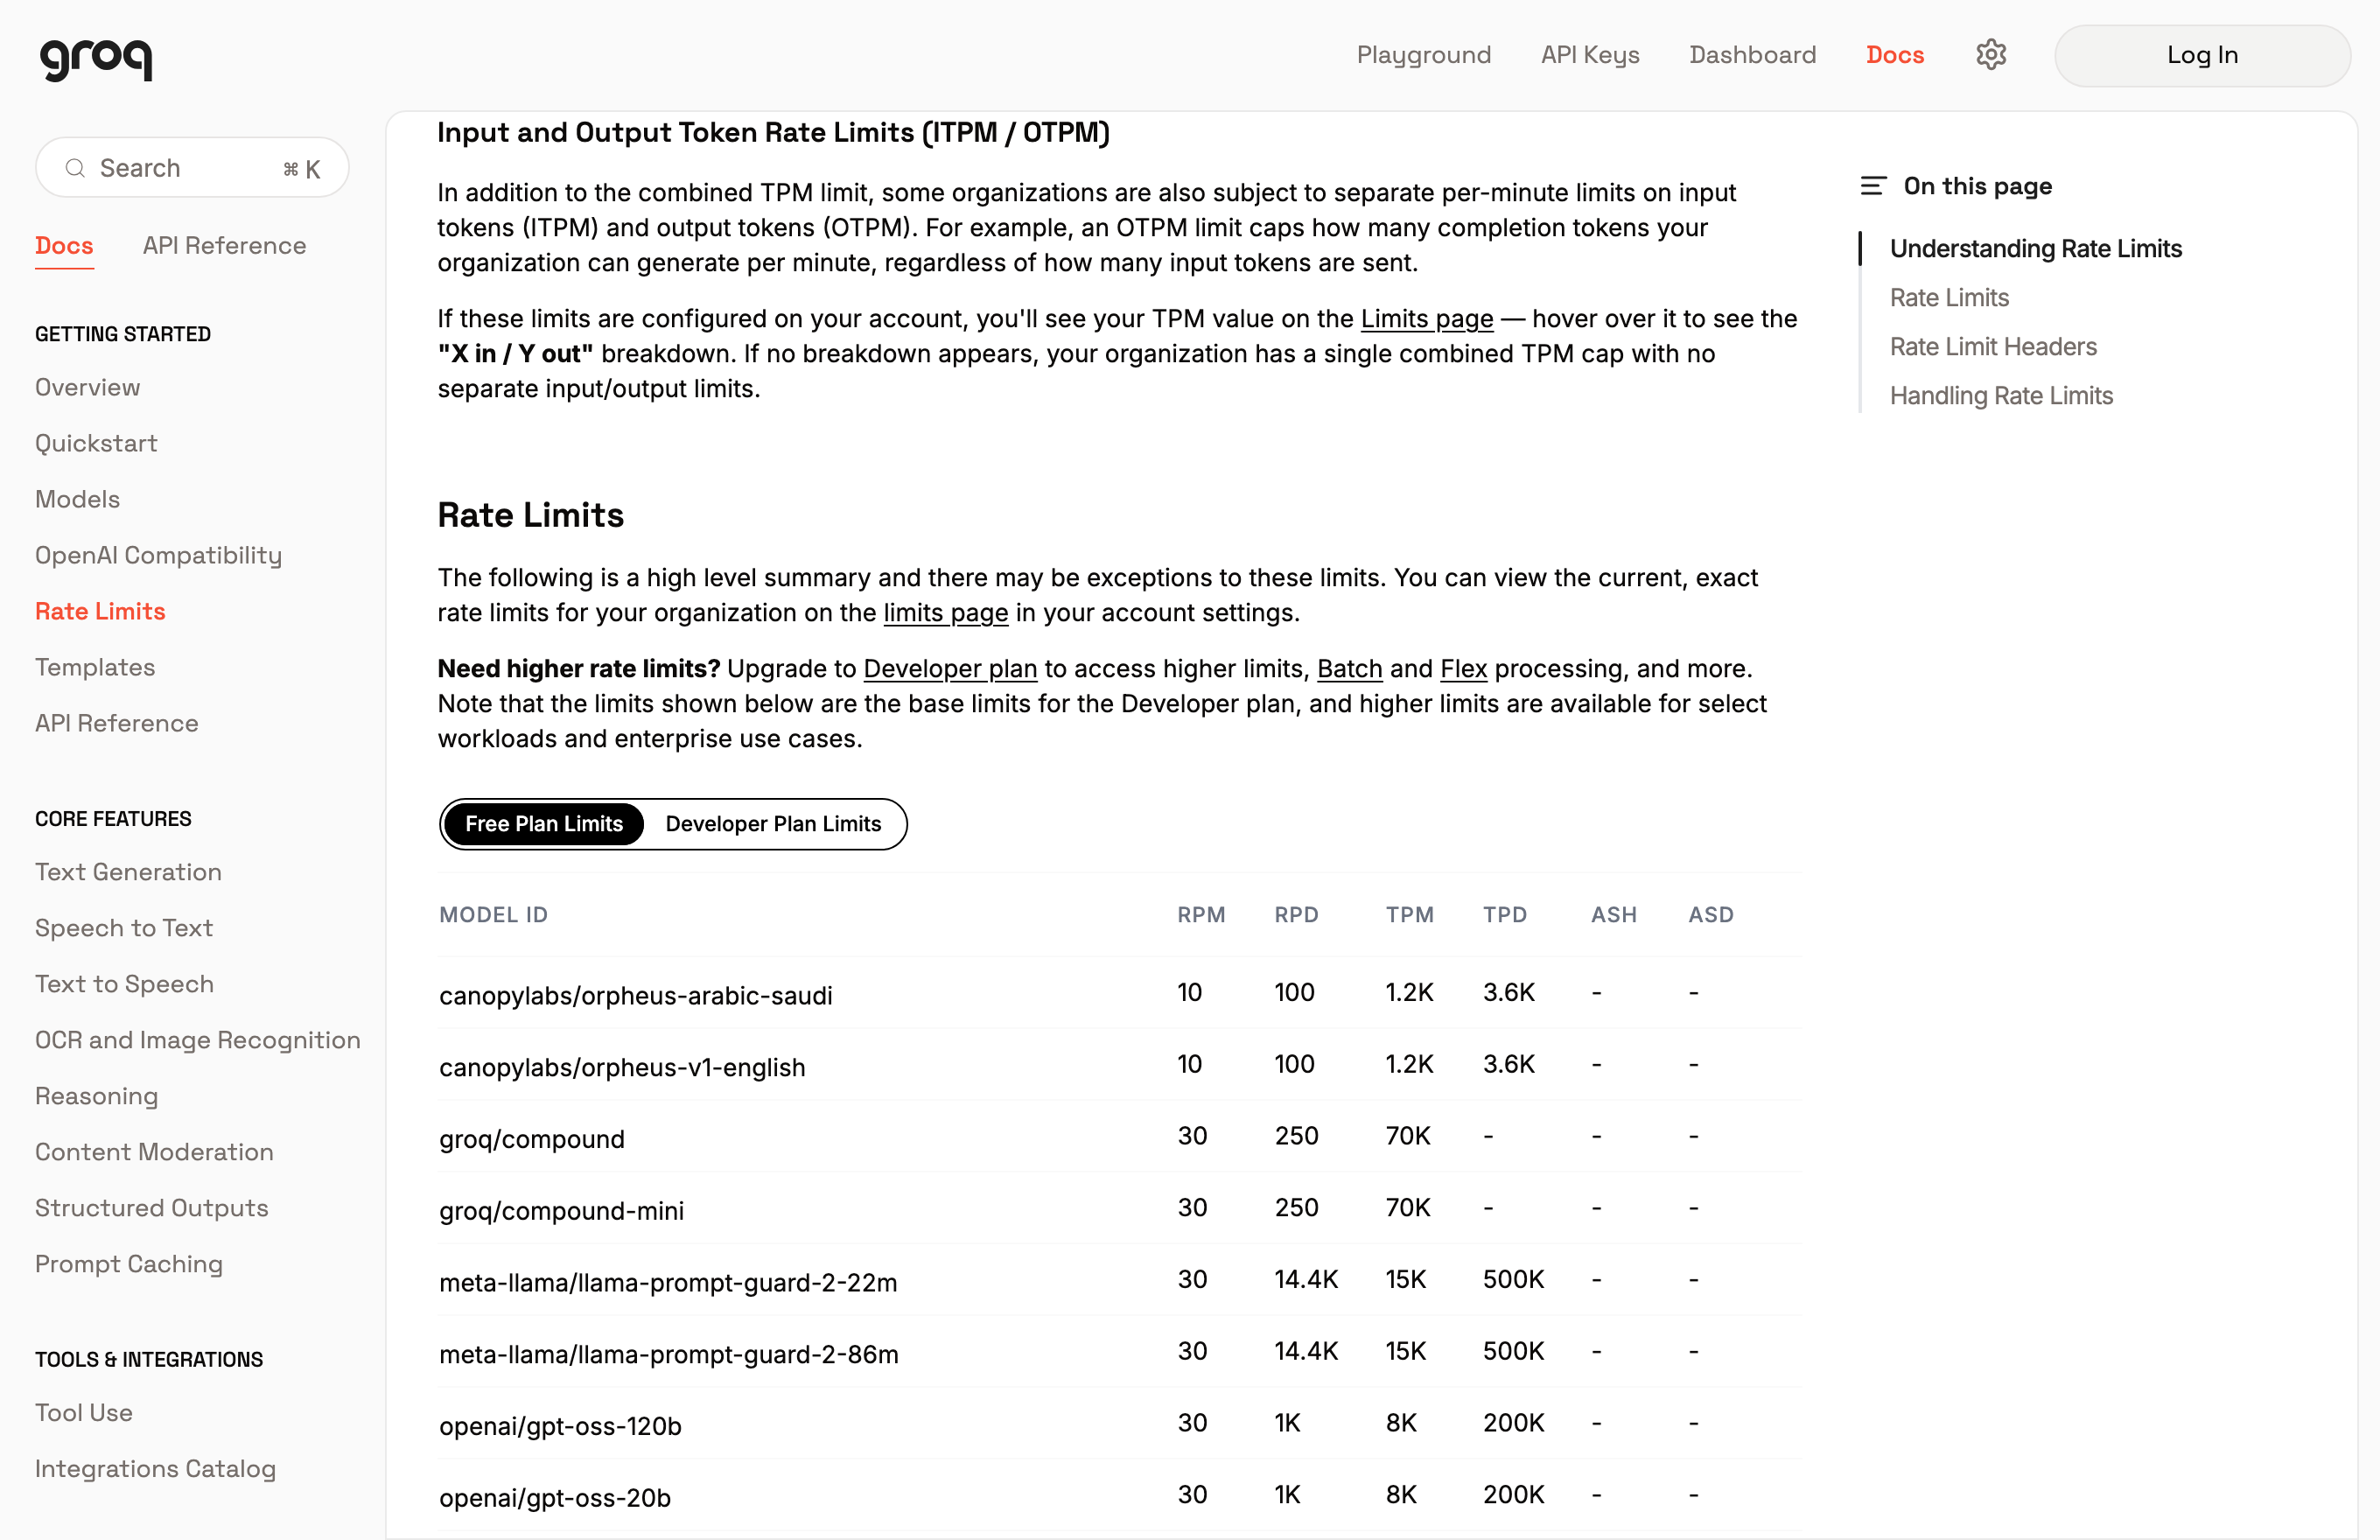
| Quota | The free tier provides credit amounts by model: RPM 10–30, RPD 100–14,400, TPM 1.2K–70K, TPD 3.6K–500K |
| Reset cycle | By minute/day |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | Official Rate Limits document 2026-08-23 Reviewed and screenshotted |
Features
-
GPT-OSS series: 30 RPM / 1K RPD / 8K TPM / 200K TPD
-
Orpheus series: 10 RPM / 100 RPD / 1.2K TPM / 3.6K TPD
-
Besides text, it can also run Whisper’s speech recognition
Note ⚠️ TPM is the real gate. A single long-context request can eat up an entire minute’s token quota, manifesting as ‘429 after just a few times.’ Batch tasks should be counted as concurrency according to TPM, not by RPM.
from openai import OpenAI
client = OpenAI(api_key="<GROQ_KEY>",
                base_url="https://api.groq.com/openai/v1")
Cloudflare Workers AI
The only free tier based on computing power rather than usage, with the broadest coverage
| Project | Content |
|---|---|
| Free type | Reset daily |
| Official entrance | https://dash.cloudflare.com/ |
| base_url | https://api.cloudflare.com/client/v4/accounts/\{account\_id\}/ai/run/\{model\} |
| Interface protocol | REST (Within Worker, you can directly env. AI.run) |
| Eligibility requirements | Cloudflare account; Both Free and Paid Workers plans enjoy this free quota |
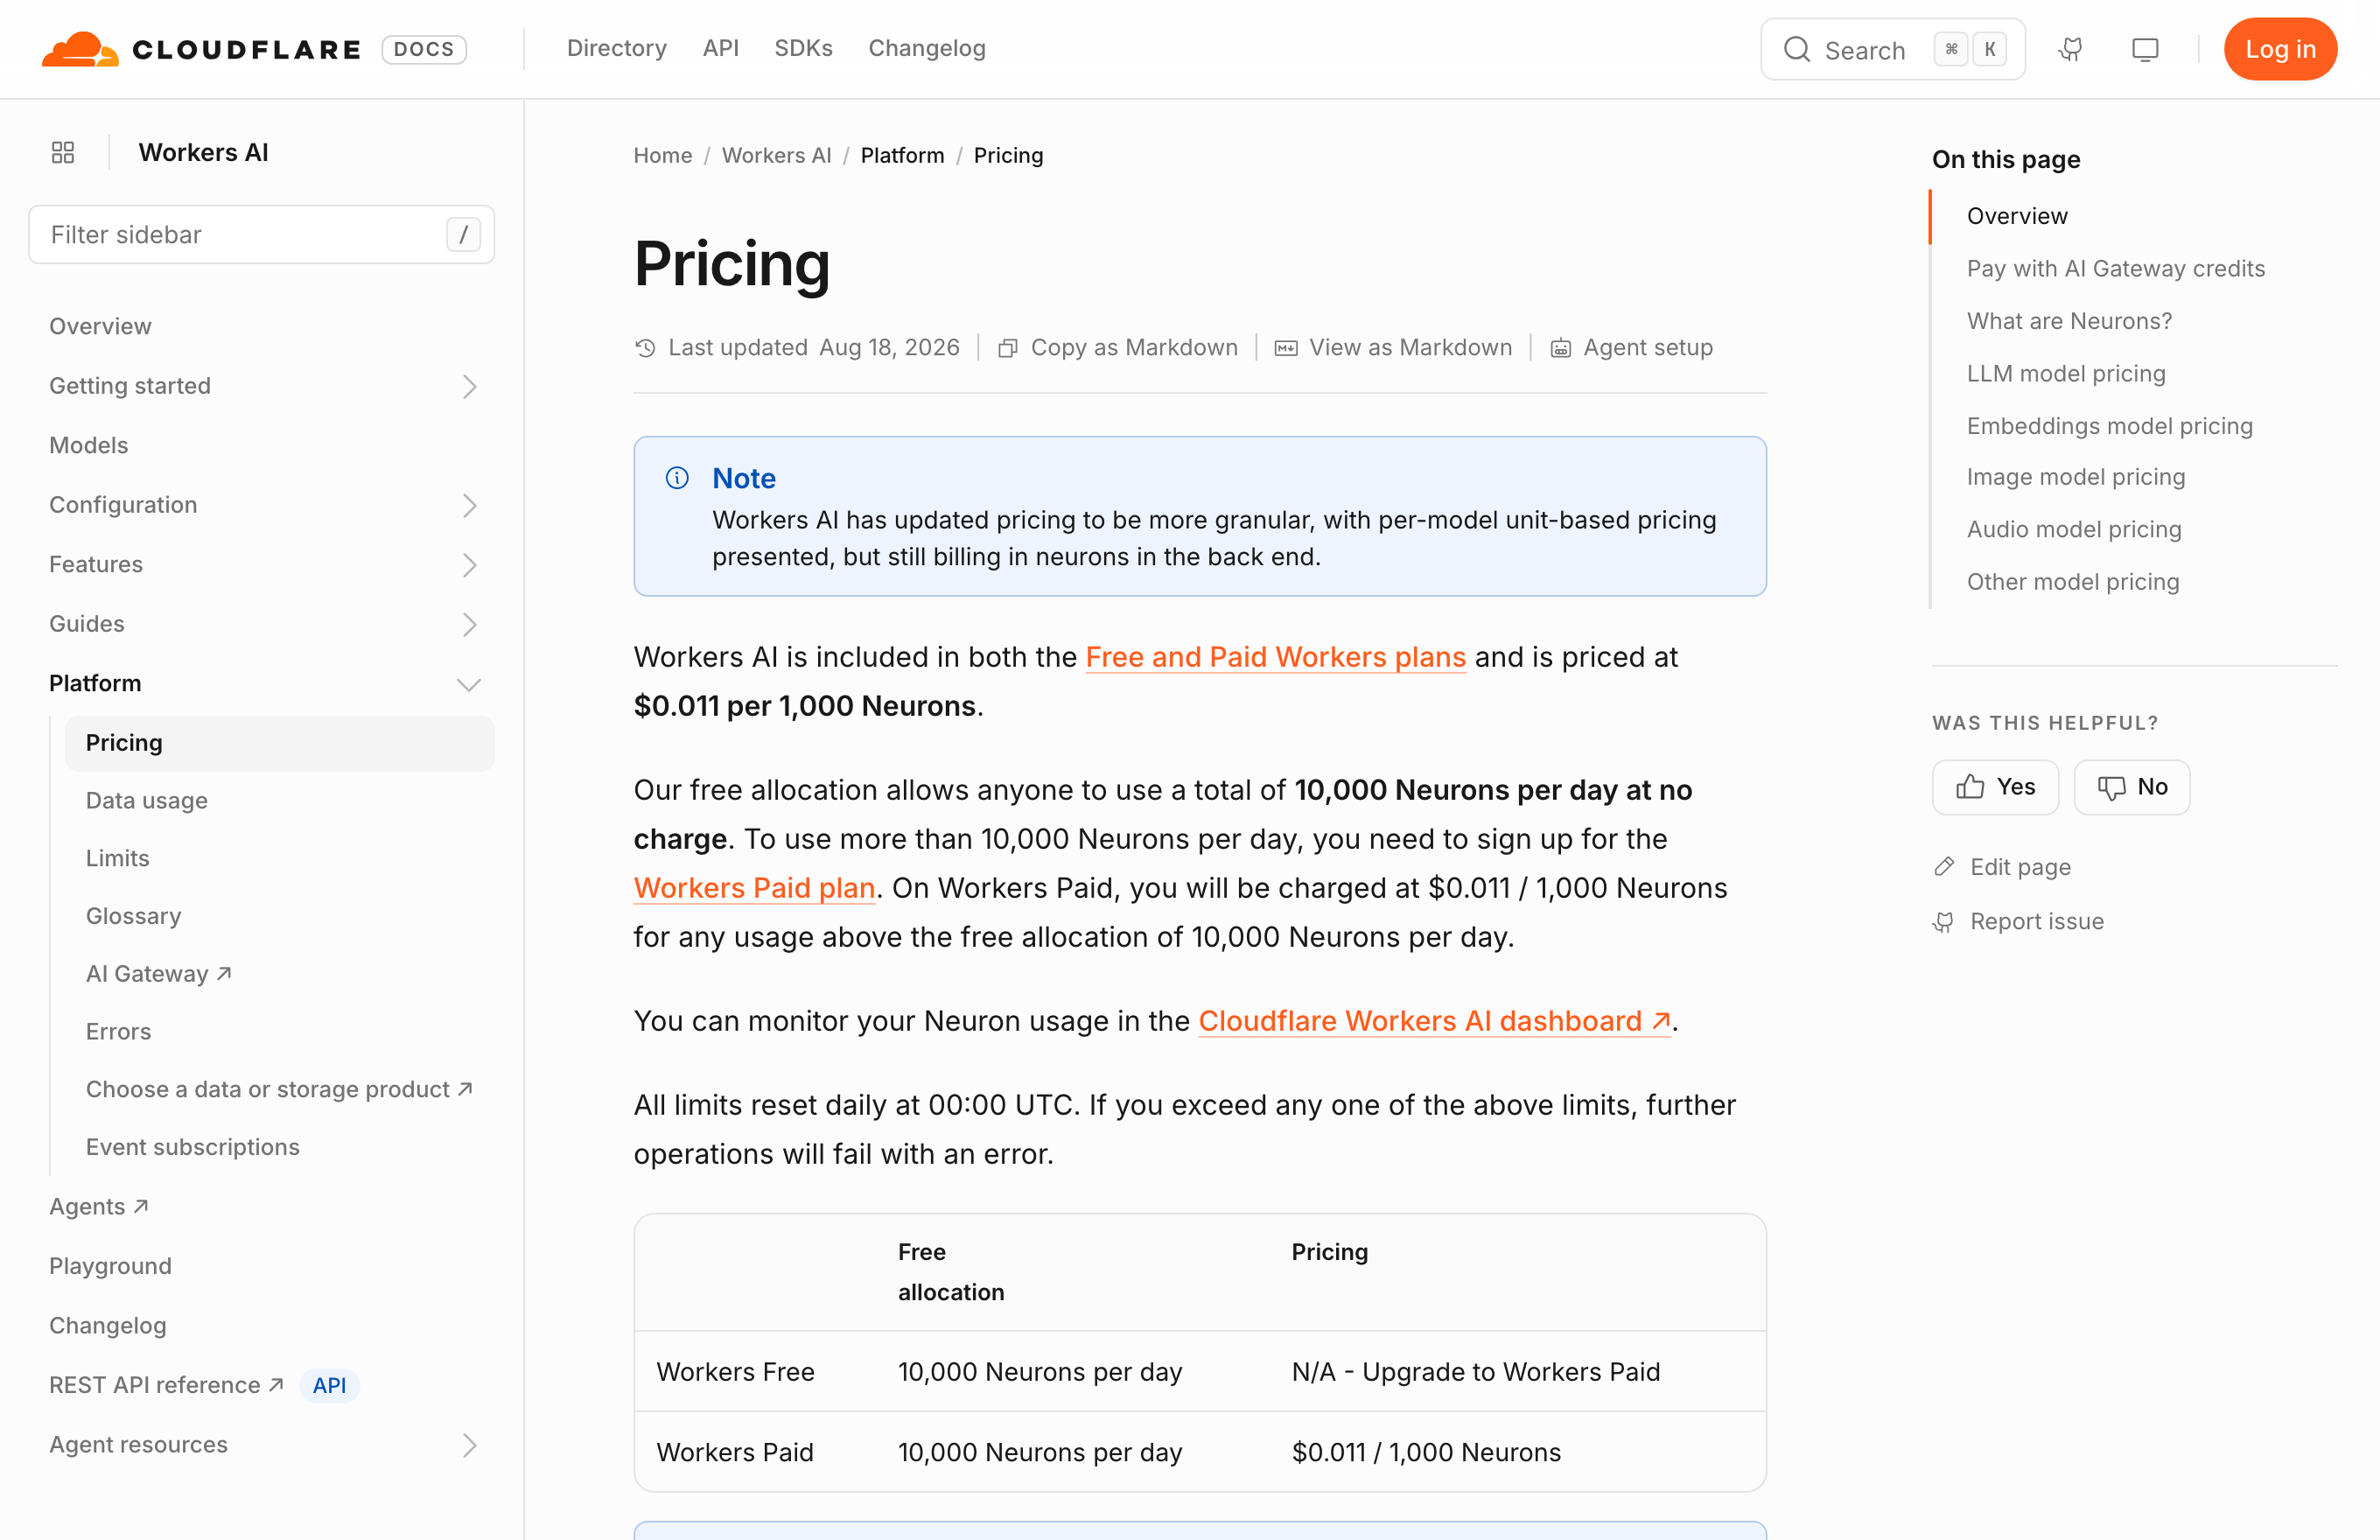
| Quota | 10,000 Neurons free per day |
| Reset cycle | Reset every day |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | Official pricing page 2026-08-23 Viewed and screenshotted |
Features
-
Neuron is a unit of computing power, not a number of requests, and many small requests are especially cost-effective
-
Covers LLMs, embeddings, text-to-image, speech recognition, speech synthesis, classification, translation, and vision
Note ⚠️ Overrunning is neither slowdown nor automatic charge, but a direct error failure; Afterwards, pricing is $0.011 / 1,000 Neurons. Running a large image or long audio session can consume a large portion of the daily quota at once. Some advanced models require binding payment methods.
// Worker 内直接调用
const r = await env.AI.run('@cf/meta/llama-3.1-8b-instruct', {
  messages: [{ role: 'user', content: '你好' }]
});
Agnes AI
Rare images and videos included in the free quota are provided, but there are three document errors in endpoints and fields
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://agnes-ai.com/ |
| base_url | https://apihub.agnes-ai.com |
| Interface protocol | REST (Image Synchronization / Video Asynchronous Polling) |
| Eligibility requirements | You can activate it by logging in with your Google account to obtain the API Key |
| Quota | Free quota is limited according to plan; Video interface is about 2 times per minute |
| Reset cycle | Subject to account plan |
| Domestic availability | Direct connection on Mac is available; In some network environments, domain names are blocked and proxy is required |
| Current status | Available |
| Verification basis | I actually called the image on 2026-08-23, took 41 seconds |
Features
-
Image model: agnes-image-2.1-flash, video model: agnes-video-v2.0
-
My test on 2026-08-23: image output in 41 seconds, 2624×1472
-
Image-to-video is about 100 seconds, pure text-to-video is about 292 seconds — if you can give the first frame, don’t use pure text
Note ⚠️ Four pitfalls you must face: (1) The domain name is apihub.agnes-ai.com, written as API. Directly 404; (2) The video result URL is in the response top-level URL, but the metadata.url written in the document does not exist; (3) Image size only supports 1K/2K/3K/4K levels and ratio; sending 1920x1080 will be standardized to 1312×736; (4) num_frames must be ≤441 and meet 8n+1 requirements. Additionally, local image input must be converted to data URI. Using a public URL can create tasks, but the product is corrupt. The return file extension is .jpg, but the actual encoding may be PNG, so you must truly transcode it before forwarding to WeChat.
# 视频:建任务 → 轮询 → 从响应顶层 url 下载
# POST https://apihub.agnes-ai.com/v1/videos
# GET  https://apihub.agnes-ai.com/agnesapi?video_id=<id>
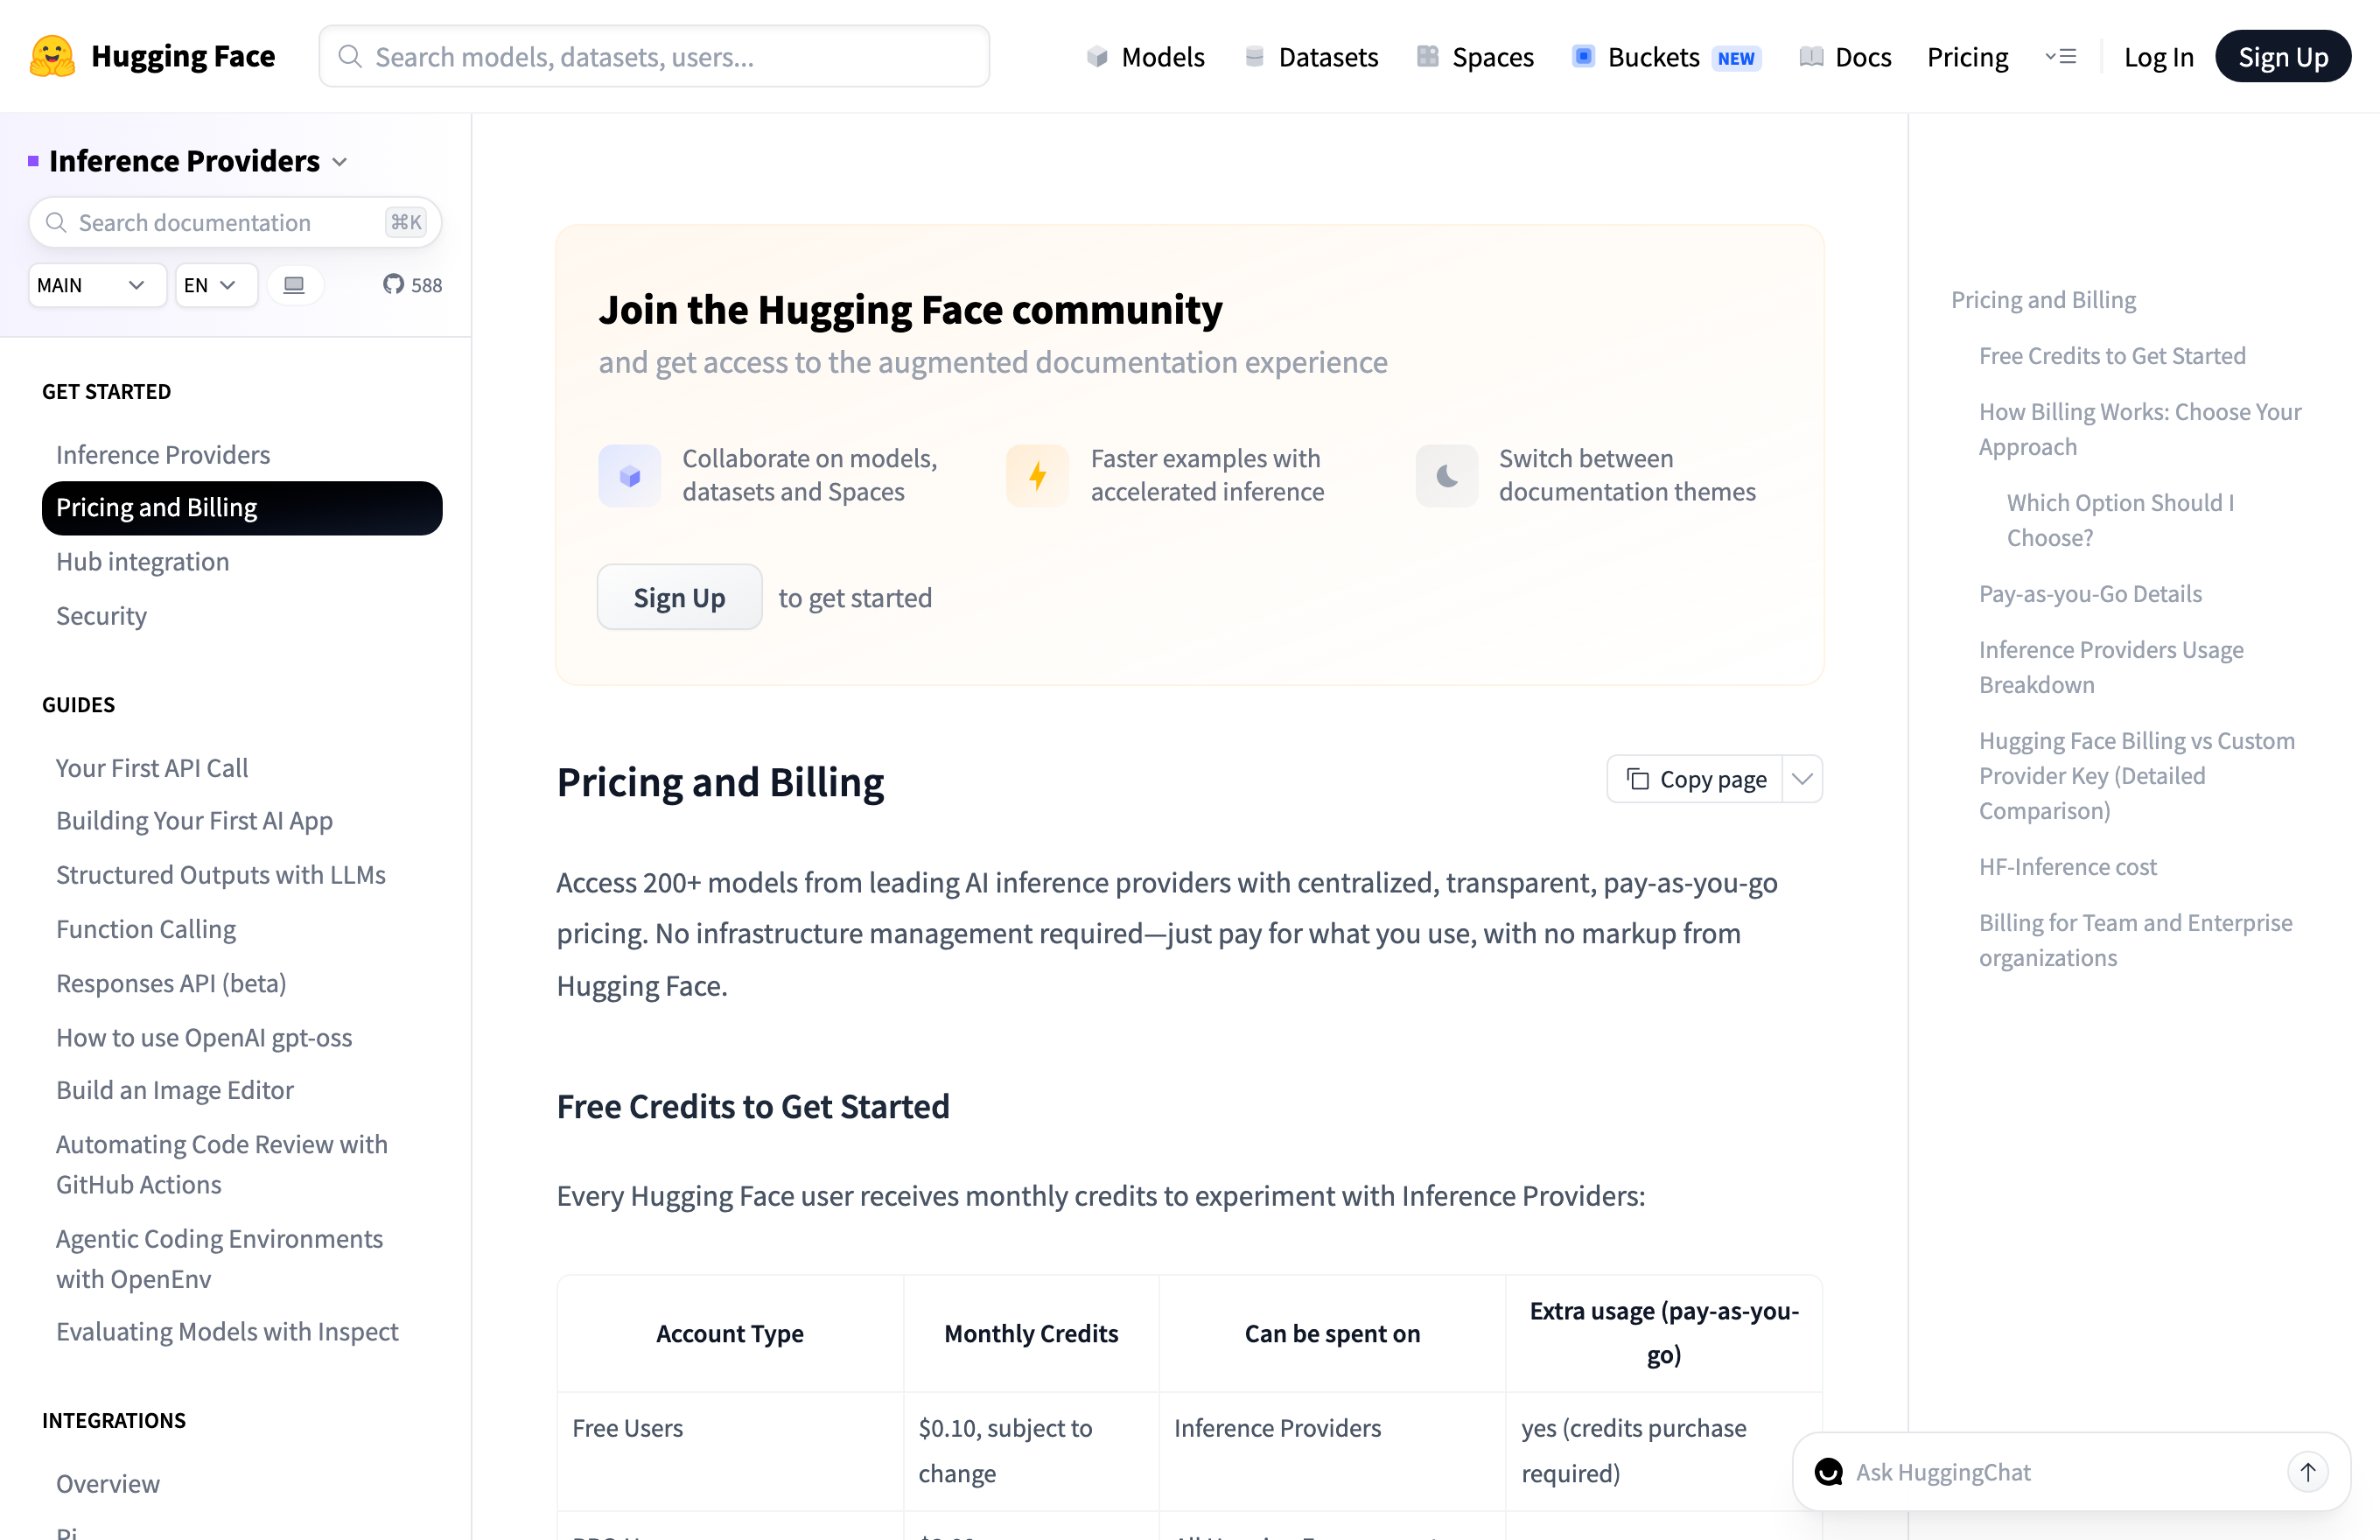
Hugging Face Inference Providers
The quota is very small, suitable for connectivity testing rather than production
| Project | Content |
|---|---|
| Free type | Each month is granted a quota |
| Official entrance | https://huggingface.co/settings/tokens |
| base_url | https://router.huggingface.co/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | HF account + Access Token |
| Quota | Free users receive $0.10 per month; PRO users pay $2.00 per month; Team/Enterprise users receive $2.00 per seat |
| Reset cycle | Monthly |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | Official pricing page 2026-08-23 Viewed and screenshotted |
Features
-
Quotas are only automatically deducted when routing requests through HF; Direct connections do not apply to all providers
-
When your quota runs out, you can purchase additional credits to continue using
Note ⚠️ The $0.10 per free user per month is a very small amount, and the official note is that it may change. When used for connectivity testing and toy projects, don’t use it as a production gateway.
from openai import OpenAI
client = OpenAI(api_key="<HF_TOKEN>",
                base_url="https://router.huggingface.co/v1")
NVIDIA NIM (build.nvidia.com)
A whole row of models labeled as Free Endpoints, perfect for trying out new models
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://build.nvidia.com/ |
| base_url | https://integrate.api.nvidia.com/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | NVIDIA developer account |
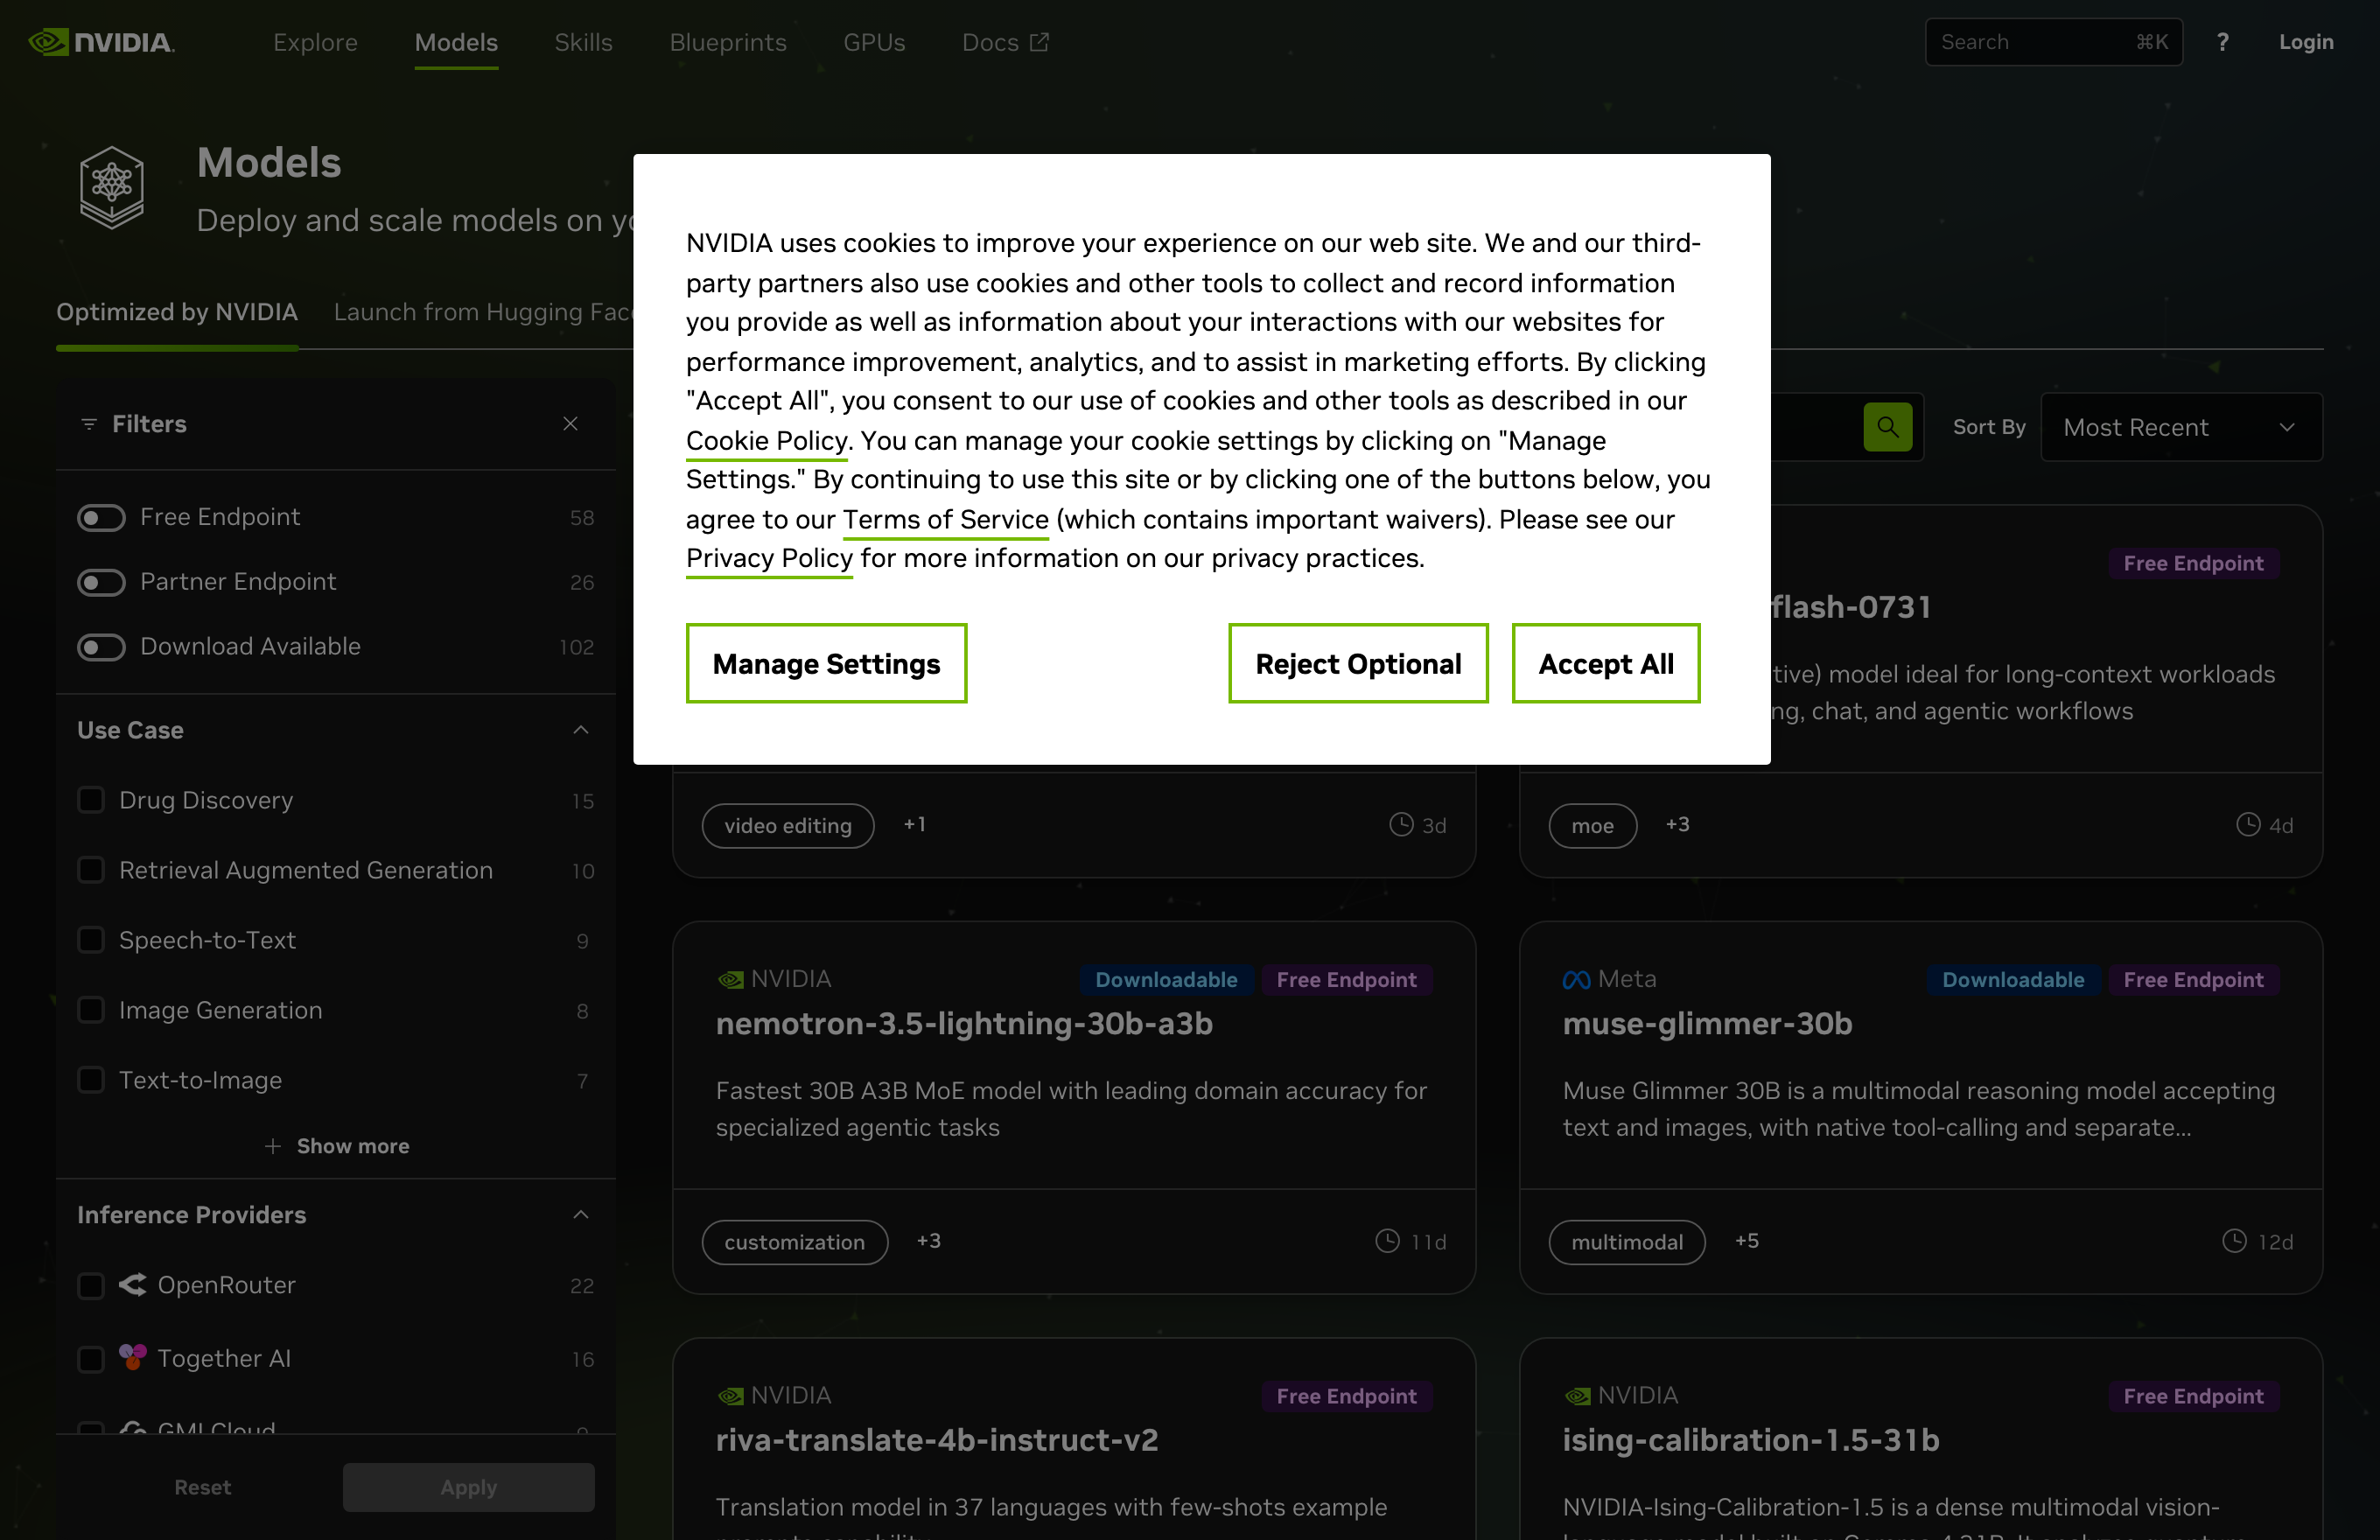
| Quota | The official page labels it as Free Inference / Free Endpoint. The unified credit limit has not been published and must be confirmed on the console |
| Reset cycle | Based on the control console |
| Domestic availability | Agency required |
| Current status | Available (credit pending approval) |
| Verification basis | Official model page 2026-08-23 Viewed and screenshotted |
Features
-
Many entries on the model plaza are directly marked as Free Endpoint
-
NVIDIA also ranks 8 out of 22 on the OpenRouter free list, making it the most aggressive in free deployment
Note The official number of free credit limits is not provided on the public page; you must verify it on the console before connecting to production.
from openai import OpenAI
client = OpenAI(api_key="<NVIDIA_KEY>",
                base_url="https://integrate.api.nvidia.com/v1")
Google Gemini API
The free tier does not require binding a settlement account, but each model’s quota must be checked by yourself in AI Studio
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://aistudio.google.com/apikey |
| base_url | https://generativelanguage.googleapis.com/v1beta/openai/ |
| Interface protocol | Native REST + OpenAI compatibility layer |
| Eligibility requirements | The free tier qualification requirement is “valid project or free trial,” with no need to link a settlement account |
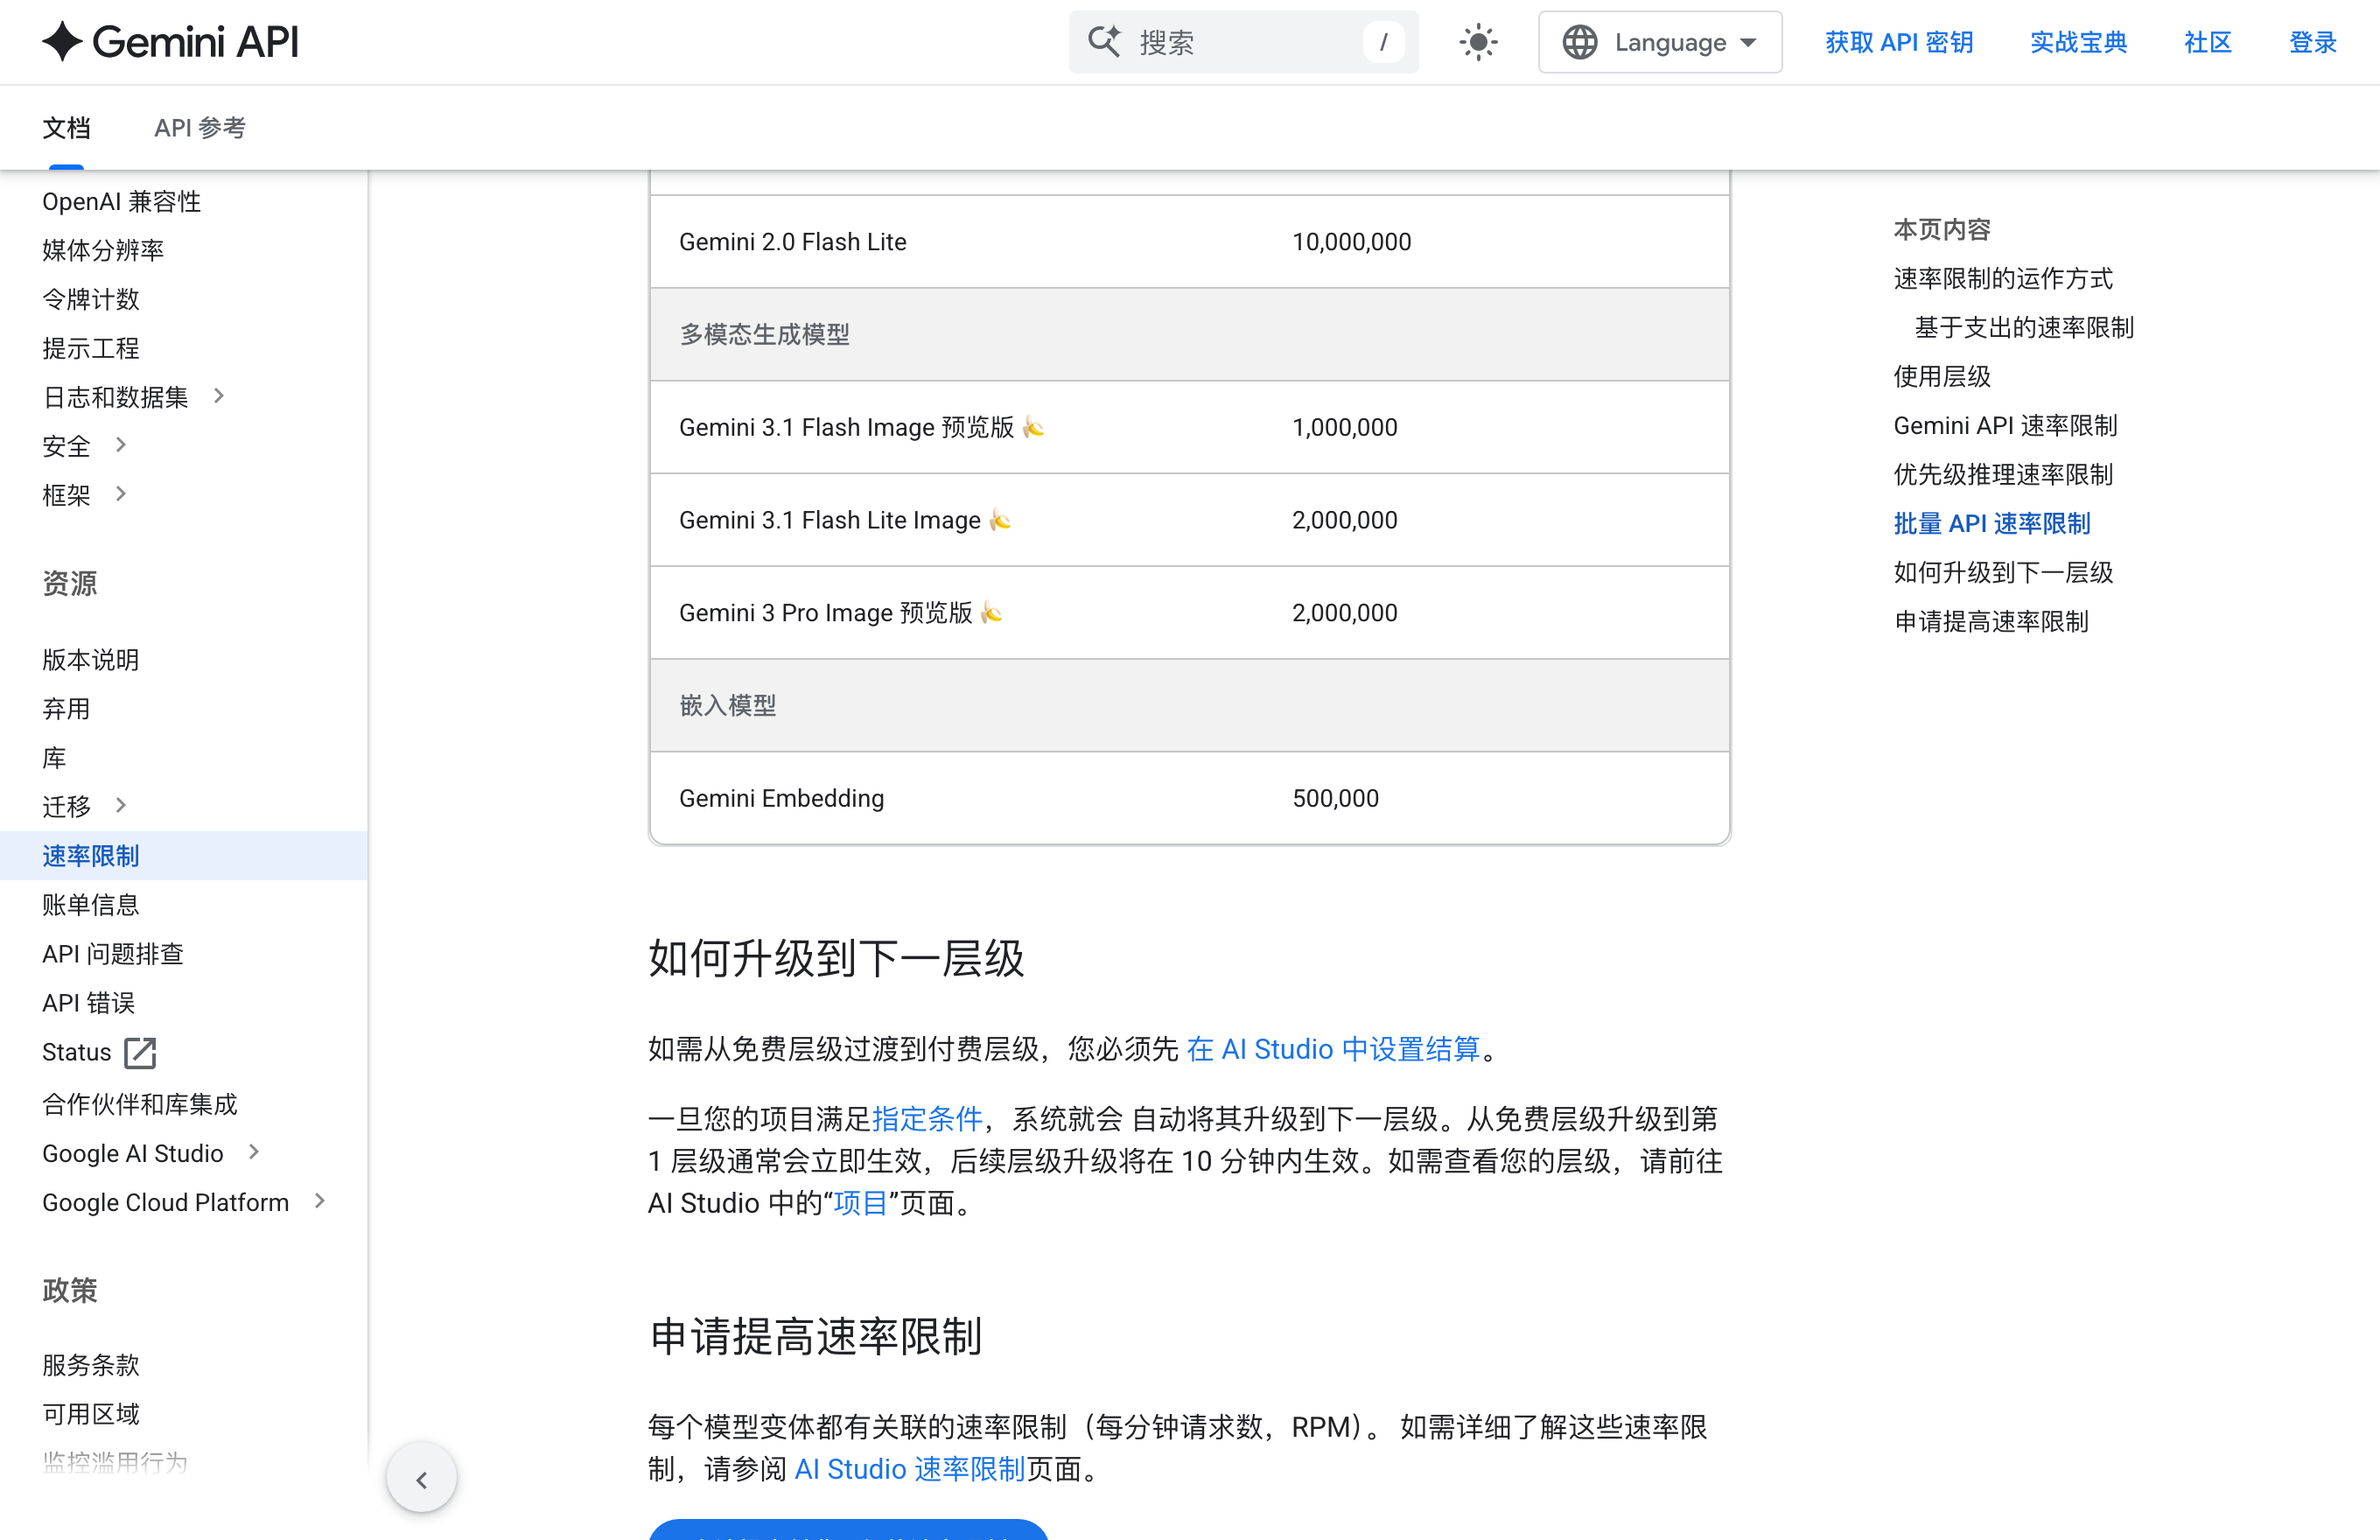
| Quota | Limits are calculated as RPM / TPM / RPD, and vary by model; The official requirement is to check the rate limit page in AI Studio, but no unified number is given |
| Reset cycle | RPD resets at midnight Pacific Time |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | Official rate limit document 2026-08-23 View and screenshot (free tier line) |
Features
-
Rate limits are applied by project, not by API keys
-
Exceeding any one of RPM, TPM, RPD, will trigger rate limiting
-
The raw image model also has an IPM (Images Per Minute) metric
Note ⚠️ This table does not provide specific limits for Gemini—the official statement states that limits automatically change with user level and account status, and any numbers written in death will expire.
from openai import OpenAI
client = OpenAI(api_key="<GEMINI_KEY>",
    base_url="https://generativelanguage.googleapis.com/v1beta/openai/")
Alibaba Cloud Bailian Model Studio
New users receive 100+ million tokens, but this is a one-time trial fee, not a permanent free tier
| Project | Content |
|---|---|
| Free type | One-time trial payment |
| Official entrance | https://bailian.console.aliyun.com/ |
| base_url | https://dashscope.aliyuncs.com/compatible-mode/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Some benefits for Alibaba Cloud accounts require real-name verification |
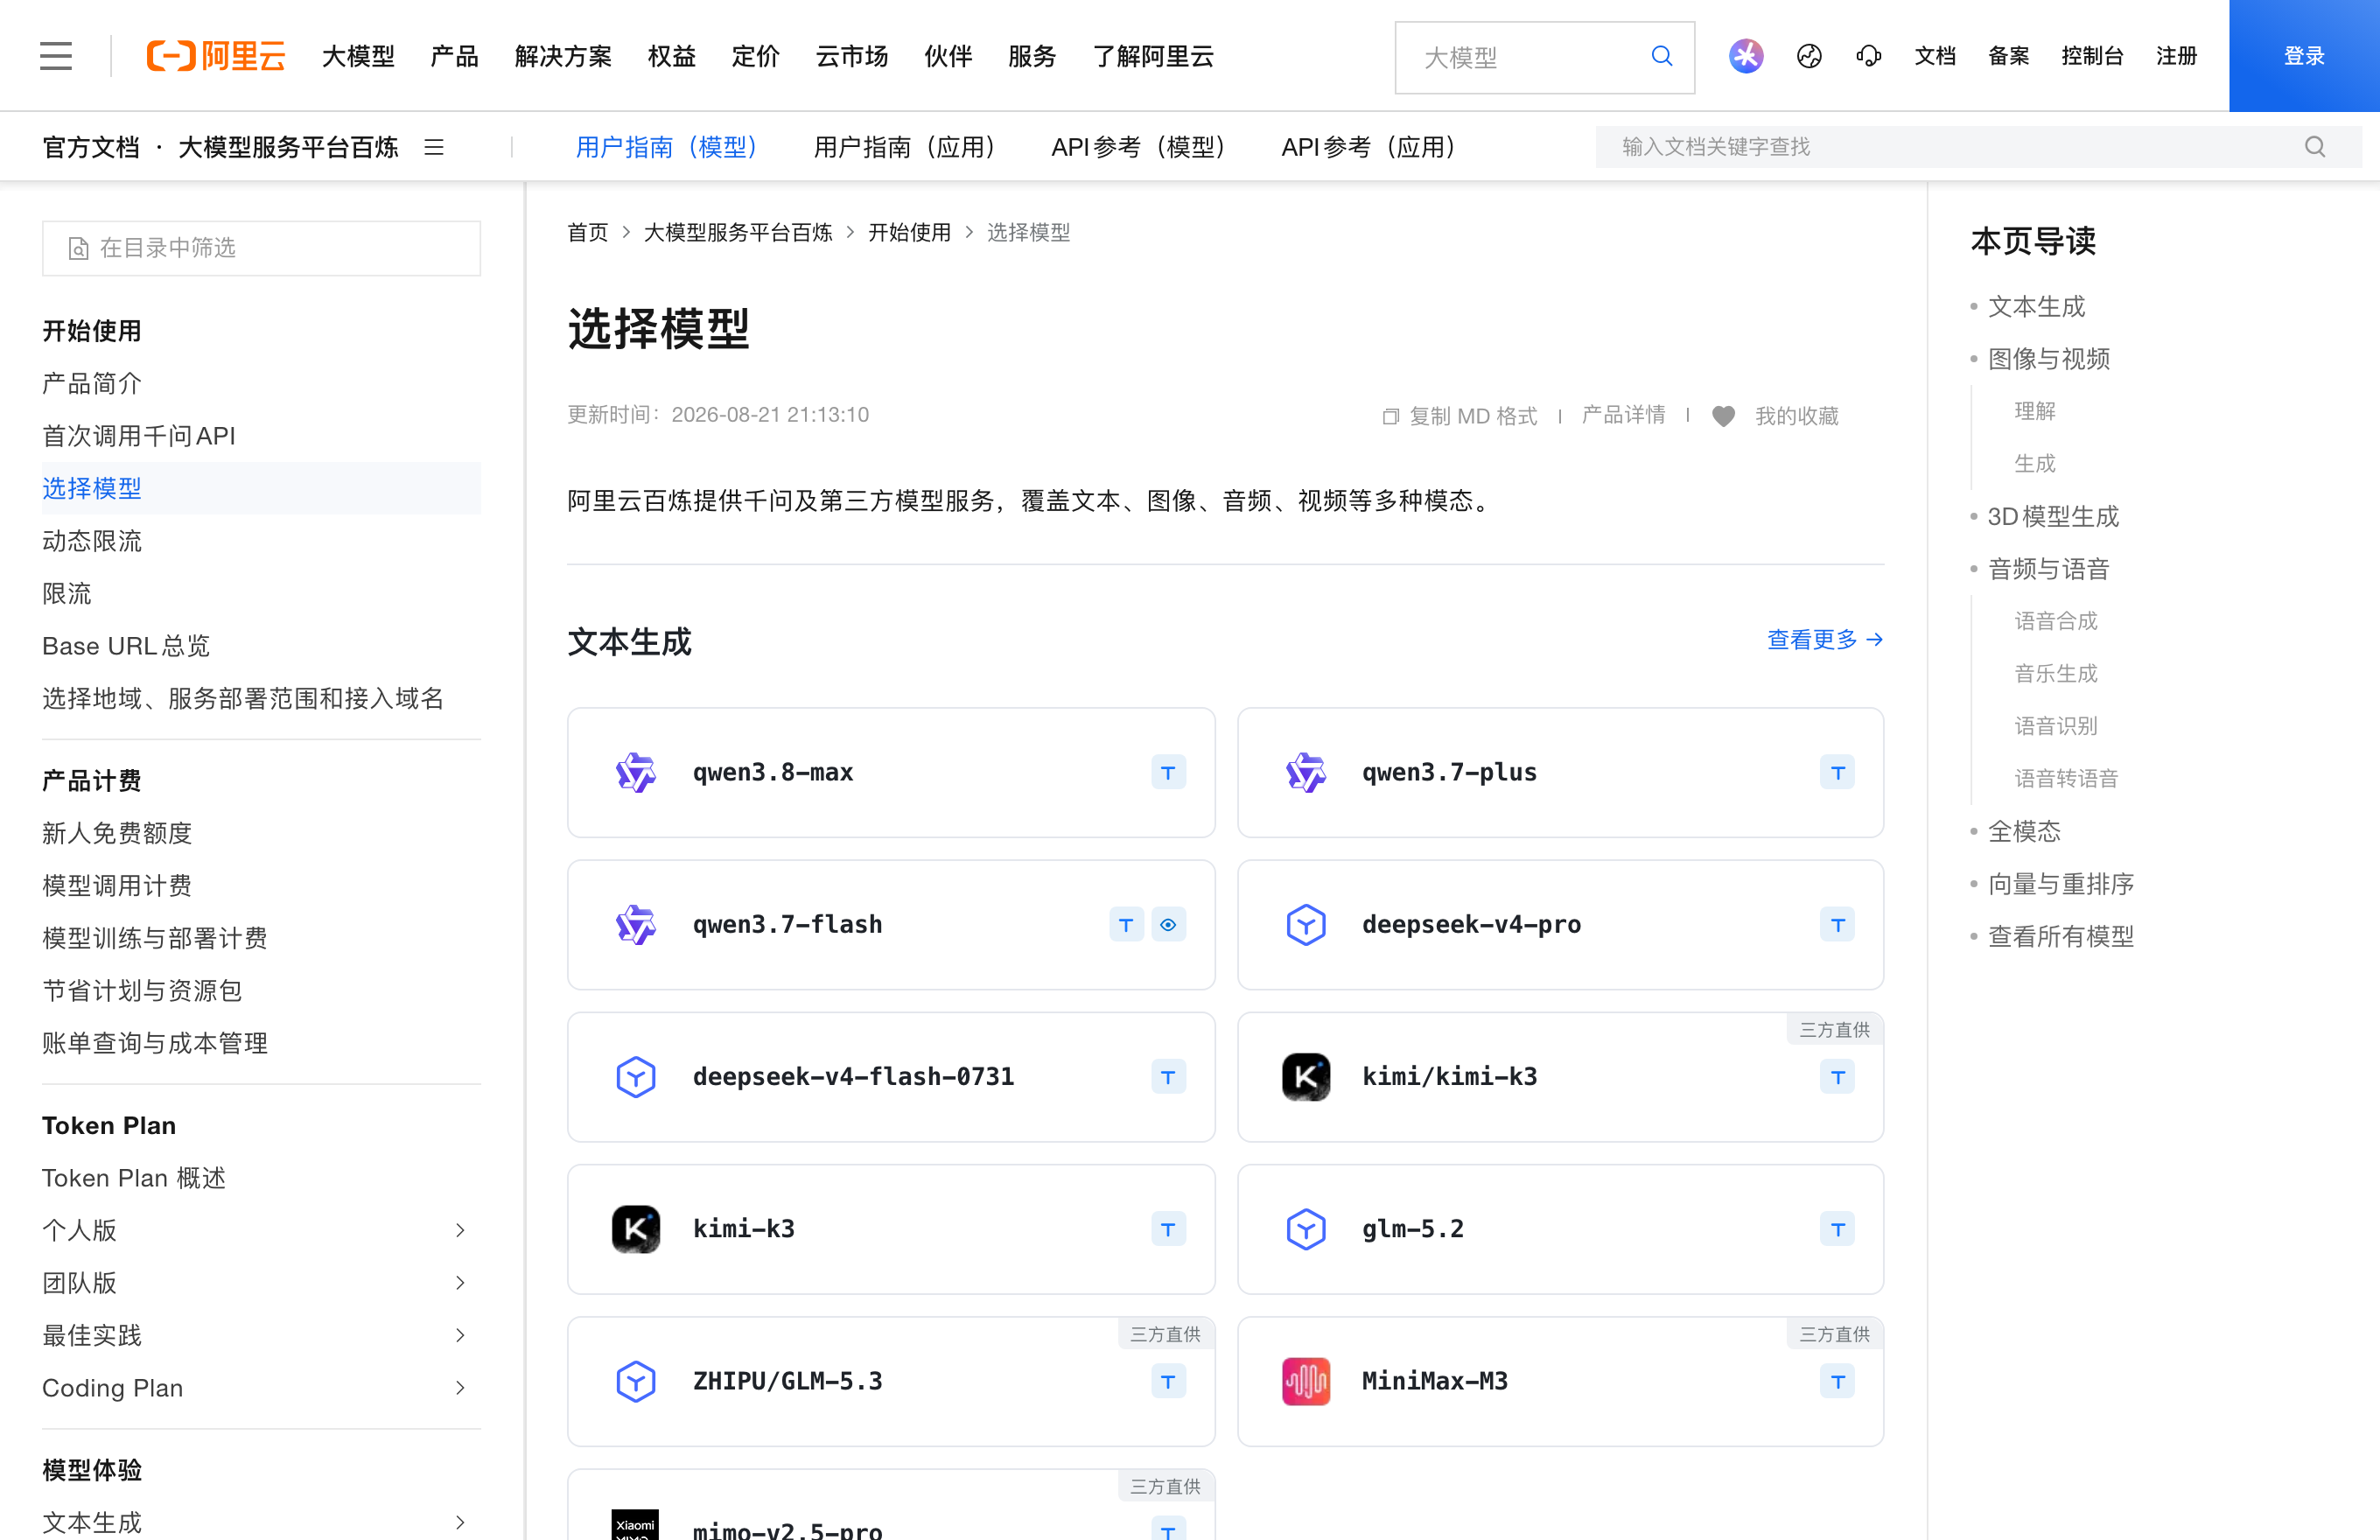
| Quota | New users receive a quota of 100 million+ tokens |
| Reset cycle | One-time, no replacement |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
| Verification basis | Official model page 2026-08-23 Viewed and screenshotted |
Features
-
The Tongyi Qianwen system is entirely useful
-
Large quota, suitable for running batch tasks all at once
Note ⚠️ This is ONE_TIME_TRIAL, not PERMANENT_FREE_TIER. Calling it ‘forever free’ is the most common lie in these kinds of tutorials. You have to pay once you use it.
from openai import OpenAI
client = OpenAI(api_key="<DASHSCOPE_KEY>",
    base_url="https://dashscope.aliyuncs.com/compatible-mode/v1")
iFlytek Spark
There are permanent free model tiers, as well as free packs that need to be claimed manually
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://xinghuo.xfyun.cn/sparkapi |
| base_url | wss://spark-api.xf-yun.com/ (WebSocket) |
| Interface protocol | WebSocket native protocol (not compatible with OpenAI) |
| Eligibility requirements | After registering, get the AppID, APIKey, and APISecret trio in the console, and claim the free credit on the product page |
| Quota | Some versions are marked as free to use; others are manually claimed as “free packs,” with the amount determined on the claim page |
| Reset cycle | Refer to the collection page |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
| Verification basis | Official product page and documentation 2026-08-23 Viewed and screenshotted |
Features
-
Lite, Pro, Pro-128K, Max, Max-32K, and 4.0 Ultra each measure tokens independently
-
1 token is approximately equivalent to 1.5 Chinese characters or 0.8 English words
Note ⚠️ Authentication is a three-piece setup of AppID + APIKey + APISecret, and it runs via WebSocket. Unlike other providers, you can’t just switch to a base/_url and connect, which is significantly more expensive to access.
# 非 OpenAI 兼容:需按官方 WebSocket 鉴权流程签名后连接
# 详见 https://www.xfyun.cn/doc/spark/Web.html
Cerebras
Register and receive a $5 trial fee, a one-time bonus, not permanent free
| Project | Content |
|---|---|
| Free type | One-time trial payment |
| Official entrance | https://cloud.cerebras.ai/ |
| base_url | https://api.cerebras.ai/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Register an account |
| Quota | Register to receive $5 in free credit |
| Reset cycle | One-time, no replacement |
| Domestic availability | Agency required |
| Current status | Available |
| Verification basis | Official pricing page 2026-08-23 Viewed and screenshotted |
Features
-
Renowned for his extremely fast reasoning speed
-
The paid tier starts at $10, with a speed limit ten times that of the free tier
Note ⚠️ ONE_TIME_TRIAL. $5 is available while supplies last; don’t plan for permanent free instead.
from openai import OpenAI
client = OpenAI(api_key="<CEREBRAS_KEY>",
                base_url="https://api.cerebras.ai/v1")
Together AI
Dynamic Speed Limiting, No Fixed Free Quota
| Project | Content |
|---|---|
| Free type | Periodic free tier |
| Official entrance | https://api.together.xyz/ |
| base_url | https://api.together.xyz/v1 |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Register an account and create a Key |
| Quota | Dynamic rate limiting: Each organization’s rate and each model’s rate automatically adjusts with continuous traffic, with no fixed threshold |
| Reset cycle | Dynamic |
| Domestic availability | Agency required |
| Current status | Available (Variable Limit) |
| Verification basis | Official speed limit document 2026-08-23 Reviewed and screenshotted |
Features
-
You can query your current real-time speed limit through the interface
-
Suitable for long-term tasks with stable traffic, not for sudden batch calls
Note ⚠️ There is no fixed free limit number to be cited. Any tutorial claiming ‘how many times a day’ for the Together free tier is questionable; use the real-time speed limit found on your own account as the standard.
from openai import OpenAI
client = OpenAI(api_key="<TOGETHER_KEY>",
                base_url="https://api.together.xyz/v1")
Open Source Hosting (Ollama / llama.cpp / whisper.cpp / Piper)
The path without worrying about others’ opinions: the credit limit is your hardware, not someone else’s policy
| Project | Content |
|---|---|
| Free type | Open source custody |
| Official entrance | https://ollama.com/ |
| base_url | http://localhost:11434/v1 (Ollama default) |
| Interface protocol | OpenAI compatible |
| Eligibility requirements | Your own machine; VRAM/memory determines how large the model can run |
| Quota | No external credit limit restrictions |
| Reset cycle | — |
| Domestic availability | Direct connection is suitable |
| Current status | Available |
| Verification basis | Long-term local operation |
Features
-
Ollama provides OpenAI-compatible endpoints, allowing you to reuse existing code by switching base_url
-
llama.cpp Responsible for reasoning, whisper.cpp Speech recognition, Piper for speech synthesis
-
The only solution that won’t fail overnight just because the other party changes its policy
Note The cost is hardware and operations: model size is limited by video memory, speed is limited by local computing power. It solves the problem of “not being cut off,” not “faster and stronger.”
from openai import OpenAI
client = OpenAI(api_key="ollama", base_url="http://localhost:11434/v1")
r = client.chat.completions.create(model="qwen3",
    messages=[{"role":"user","content":"你好"}])
Pollinations
Keyless anonymous layer is still alive, but I tested two results on the same day
| Project | Content |
|---|---|
| Free type | Keyless public interface |
| Official entrance | https://pollinations.ai/ |
| base_url | https://text.pollinations.ai |
| Interface protocol | REST / OpenAI compatible path |
| Eligibility requirements | The anonymity layer of text interfaces does not require Keys; Generation class interfaces require a built-in Key and Pollen balance |
| Quota | The anonymous layer does not publish the quota number; In actual tests, it can be called directly, but temporary 402 may occur |
| Reset cycle | Not yet published |
| Domestic availability | Agency required |
| Current status | Available (unstable state, two results observed on the day) |
| Verification basis | On 2026-08-23 at 12:10, I tested 402 and retested at 15:57 with 4 consecutive 200 points. Screenshots of both states are shown below |
Features
-
The Models interface entry is marked with “tier”: “anonymous”, and the official notice states that anonymous requests are not affected by the deprecated plan
-
OpenAI is compatible with POST/OpenAI paths and also supports direct read GET formats
-
⚠️ My two tests that day had different results: at 12:10 CST, HTTP 402 was returned (budget too low); at 15:57 CST, the same exit IP was tested four times, all of which reached HTTP 200
Note ⚠️ This is the most important methodological sample in this table: on the same day, with the same exit IP, the same request body, it was rejected in the morning and passed in the afternoon. The status of the free entry can change within a few hours; snapshots at any point in time (including this table) cannot be considered long-term conclusions—please send a real request confirmation before calling.
curl -s https://text.pollinations.ai/openai \
  -H 'Content-Type: application/json' \
  -d '{"model":"openai-fast","messages":[{"role":"user","content":"ping"}]}'
# 不带任何 Key;先自测一次再决定是否接入
GitHub Models
2026-07-30 Fully retired, full network tutorials now full of dead links
| Project | Content |
|---|---|
| Free type | Retired / Invalid |
| Official entrance | https://docs.github.com/en/github-models |
| base_url | — |
| Interface protocol | — |
| Eligibility requirements | — |
| Quota | None |
| Reset cycle | — |
| Domestic availability | — |
| Current status | Retired from service |
| Verification basis | GitHub official retirement announcement 2026-08-23 Viewed and screenshotted |
Features
- The official migration direction is Azure AI Foundry or GitHub Copilot
Note Official original text: As of July 30, 2026, GitHub Models has been fully retired. The playground, model catalog, inference API, and bring your own key (BYOK) are no longer available to any customer.
# 已退役,无调用方式
Note The free list has no expiration date, only the last verification date. This table was retested on 2026-08-23; Please send a real request to confirm the current status before calling it.
🧰 Tools I build
I maintain all of these tools myself. Preview builds are clearly labeled; the release pages are the source of truth for downloads, updates and known limits.
Info: HyphenBox Status: Official releases
A radar for free LLM APIs: availability is re-tested continuously, one local interface for all of them, and keys stay on your machine
Info: LocalBrain Status: Official releases
A multimodal MCP toolbox for local models: TTS, Whisper and video generation in one place
Info: ScreenLex Status: Official releases
Learn new words while you watch shows. Free, for Mac and Windows
Info: HyphenScreen Status: Official releases
Screen recording and smart editing in one: a DaVinci-style timeline, automatic redaction and a check of the finished video before export. Free
Quote: HyphenTech Make AI your superpower Local deployment · Free resources · Self-made software https://hyphentech.top
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Scan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

Comments
Loading comments…