
Info: Machine translation This post was machine-translated from the Chinese original. Wording may be rough in places — the Chinese version is authoritative.
Summary From two 503 to model change to complete the task HyphenTech · Data and measurements from November 2, 2026
The first time I called Gemini, both questions only received 503 service busy. After switching to gemini-3.5-flash-lite, both the order and Chinese rewrite came back: the order waited 28.262 seconds, and the rewrite took 18.393 seconds. This process explains the actual experience better than the phrase “Gemini is free and available.”
First, give the same question without different prompts to compare speed
In the order, two devices A each cost 1200 yuan, and three devices B each cost 350 yuan. Add 80 yuan for shipping, reduce 130 yuan off, so the correct total price is 3400 yuan. Request to return product details and fixed fields. Another task is to compress the technical description into two sentences in Chinese; the original four requirements must not be omitted.
This time, using an existing account, the local HyphenBox forwarded the request to the corresponding platform. The timing ranged from the local machine’s request to receiving the response, including network and service waiting; Each model’s order question was only run once. The account was configured to the free mode and did not read the final bill.
| Request model/task | Completing it takes time | Actually return |
|---|---|---|
| gemini-3.1-flash-lite <br>order | 1.695 seconds | 503; Call failed |
| gemini-3.1-flash-lite <br>rewrite | 1.422 seconds | 503; Call failed |
| gemini-3-flash-preview <br>order | 3.276 seconds | 200; JSON field and amount match the standard answer |
| Gemini-3.5-Flash <br>order | 4.252 seconds | 200; JSON field and amount match the standard answer |
| Gemini-3.6-flash <br>order | 4.512 seconds | 200; JSON field and amount match the standard answer |
| gemini-3.5-flash-lite <br>order | 28.262 seconds | 200; JSON field and amount match the standard answer |
| gemini-3.5-flash-lite <br>rewrite | 18.393 seconds | 200; returned, four pieces of information retained |
This machine forwards via HyphenBox; One request per line, not multi-turn averaging. Time consumption includes network and upstream waiting.
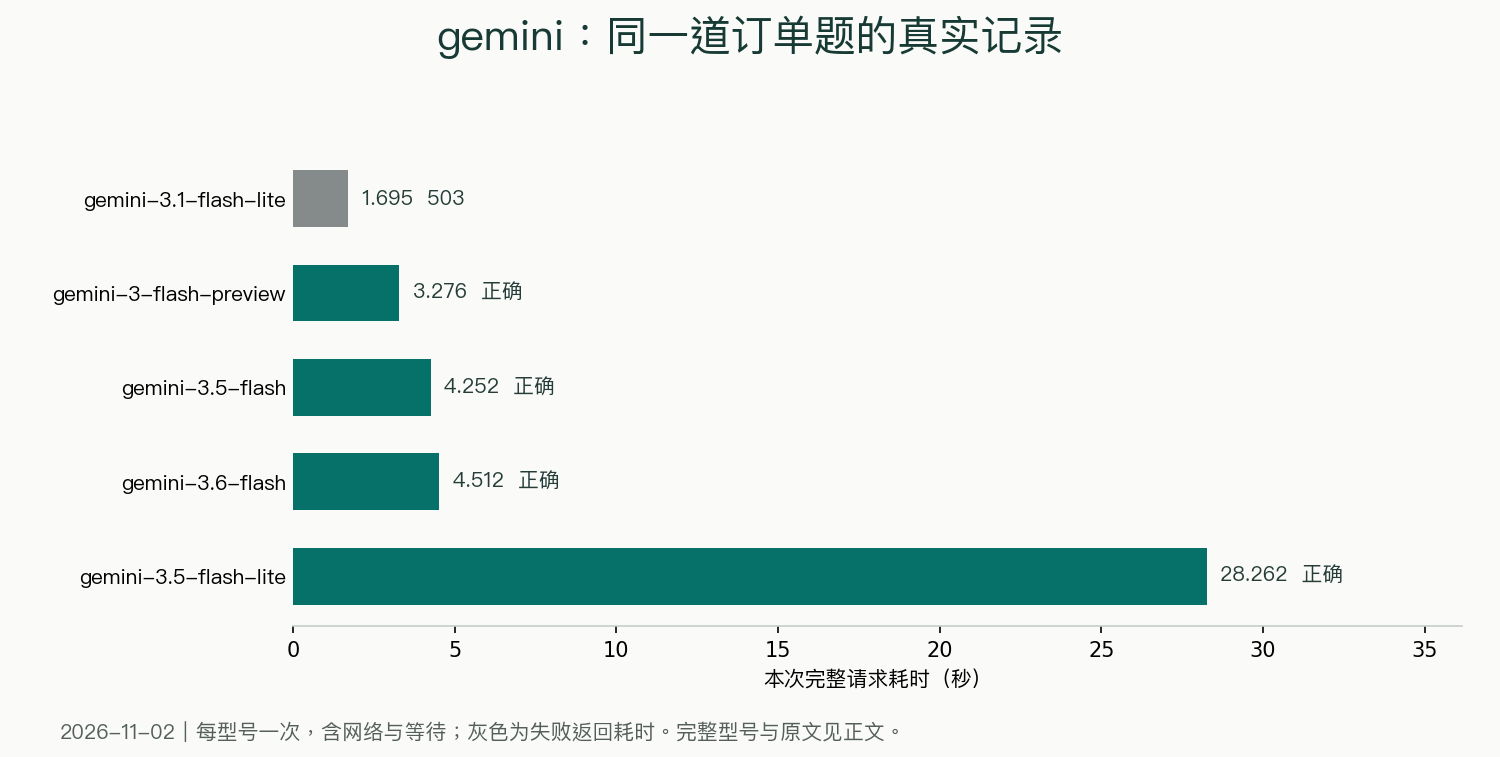
The first request for gemini-3.1-flash-lite both errors indicated that current demand was too high. Later, I changed the model and resent the original task, but it wasn’t made simpler, nor did the error page be deleted from the log.
After 28 seconds, the result is complete
{
  "items": [
    {
      "name": "设备A",
      "quantity": 2,
      "unit_price": 1200,
      "subtotal": 2400
    },
    {
      "name": "设备B",
      "quantity": 3,
      "unit_price": 350,
      "subtotal": 1050
    }
  ],
  "shipping": 80,
  "discount": 130,
  "total": 3400
}
Orders returned to original after model replacement
Product name, quantity, subtotal, shipping fee, discount, and total price all match the standard answer. The 28-second period includes both network and server waiting, and may also include internal model processing; This time, not enough stage timing was saved, so not all time can be considered “thinking.”
每天自动重置免费额度,每任务限生成一张图。若失败会保留错误信息,需自行申请密钥使用。
The order requests for the other three models are 3.276 seconds, 4.252 seconds, and 4.512 seconds respectively, all of which are correct. Having ‘Lite’ in the name doesn’t mean it’s always faster end-to-end; When choosing, running through the task you actually want to complete is more reliable than guessing speed based on the name.
Don’t mix free and paid options together when connecting
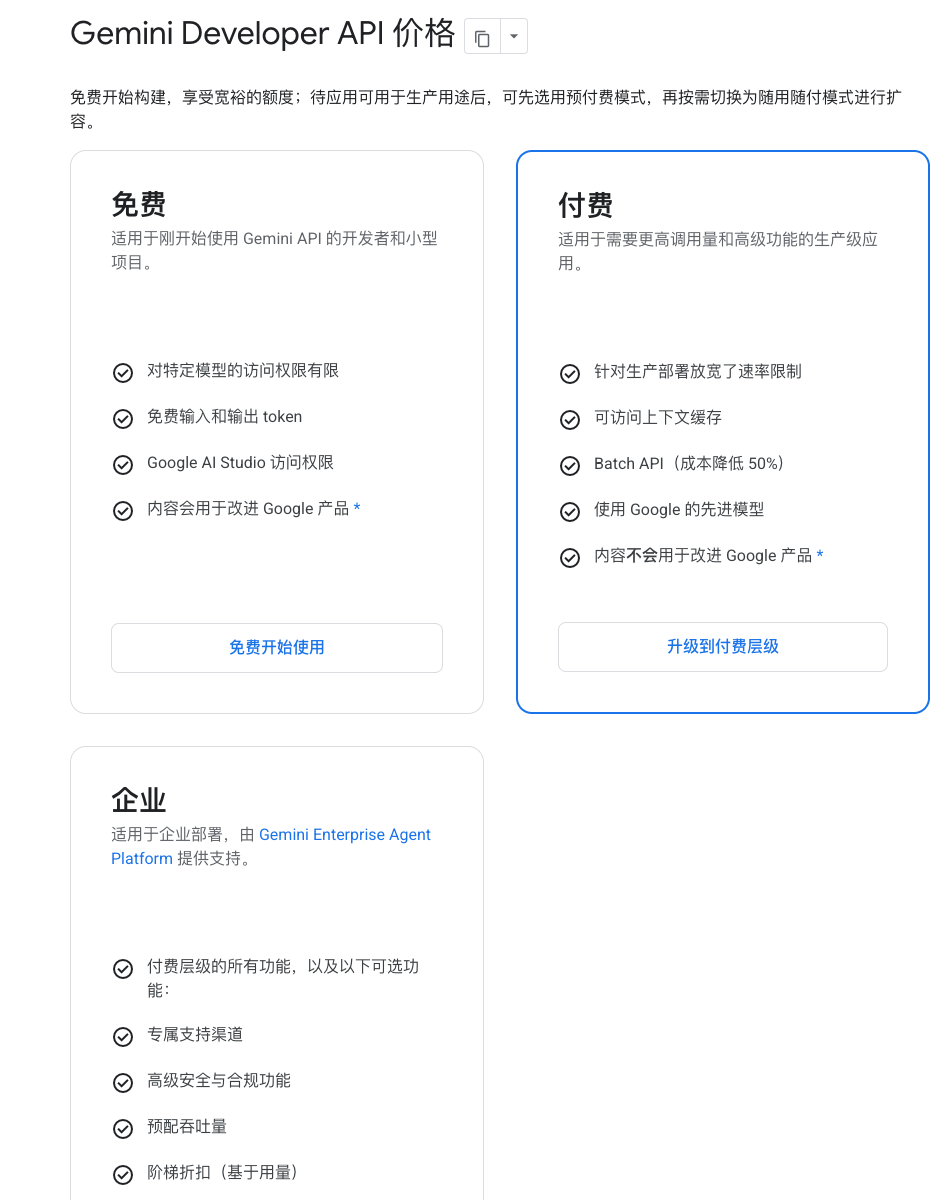
Create your own project and key from Google AI Studio key page, then quickly start with official access. Free benefits are valid based on project, model, and supported regions; For the same brand name, benefits for text understanding, image generation, and voice generation vary. This article only lists the text skills tested this time.
The official newbie document is currently demonstrated using the Interactions interface, while this round of HyphenBox uses existing text routing. The latest model recommended in the document is considered separately from the actual requested model in this article: the table retains the actual name sent at the time, and does not replace old records with new names.
When configuring third-party clients, select the Gemini interface it clearly supports or set compatible interfaces according to official documentation. Google Pass, other platform keys, and local routing tokens are different keys and cannot be used interchangeably if filled incorrectly.
How should the software handle busy situations?
503 is suitable for retrying later, 429 indicates rate limiting; Both should retain the original error and task state. Text requests can still be resent, but asynchronous tasks like images and videos must confirm whether the original task was successfully submitted to avoid duplicate generation.
I let users know in the interface that they are waiting, busy with messages, or have already received complete answers. Leaving “Generating Generation” on the list, then quietly switching to another service, shows no failure and prevents a real experience.
Quote: My judgment Gemini’s free text entry is worth considering, but the model must be tested separately. This time, complete and correct answers are available, as well as 503 and longer wait times. For tasks sensitive to waiting, first test the full time consumption with your short task, then decide on the default model.
Main sources of verification
Self-made software
Versions, changes and supported installers all come from the same public release records.
HyphenAssistant
Continue your computer’s DeepSeek Harness session from a phone browser. The service, computer and network must stay online; model costs follow your existing setup.
View public downloads and updates ↗LocalBrain
A local AI toolbox for transcription, speech, images, video, and MCP tools. Features vary by platform version.
View public downloads and updates ↗HyphenBox
A free model API radar and local router, with ongoing availability checks and keys kept on your device.
View public downloads and updates ↗ScreenLex
Turn subtitles from your own films and shows into an English vocabulary library, entirely offline.
View public downloads and updates ↗HyphenScreen
Screen recording and editing with a Resolve-style timeline, automatic redaction and pre-export checks.
View public downloads and updates ↗Support HyphenTech
Late nights and burned API credits went in,a cup of tea comes back out — only if you feel like it.
Save the QR codeScan with WeChatPress and hold to save the image, then open it from your album in WeChat Scan

WeChat tips · Any amount welcome



Comments
Loading comments…